vLLM Blog
25 stories
vLLM BlogToolsDay 0 support for Mistral Large 4 on vLLM Day-0 vLLM support for Mistral Large 4 with sparse MLA, cross-layer KV sharing, DSpark speculative decoding, DCP/PCP long context and NIXL P/D on NVIDIA Blackwell.
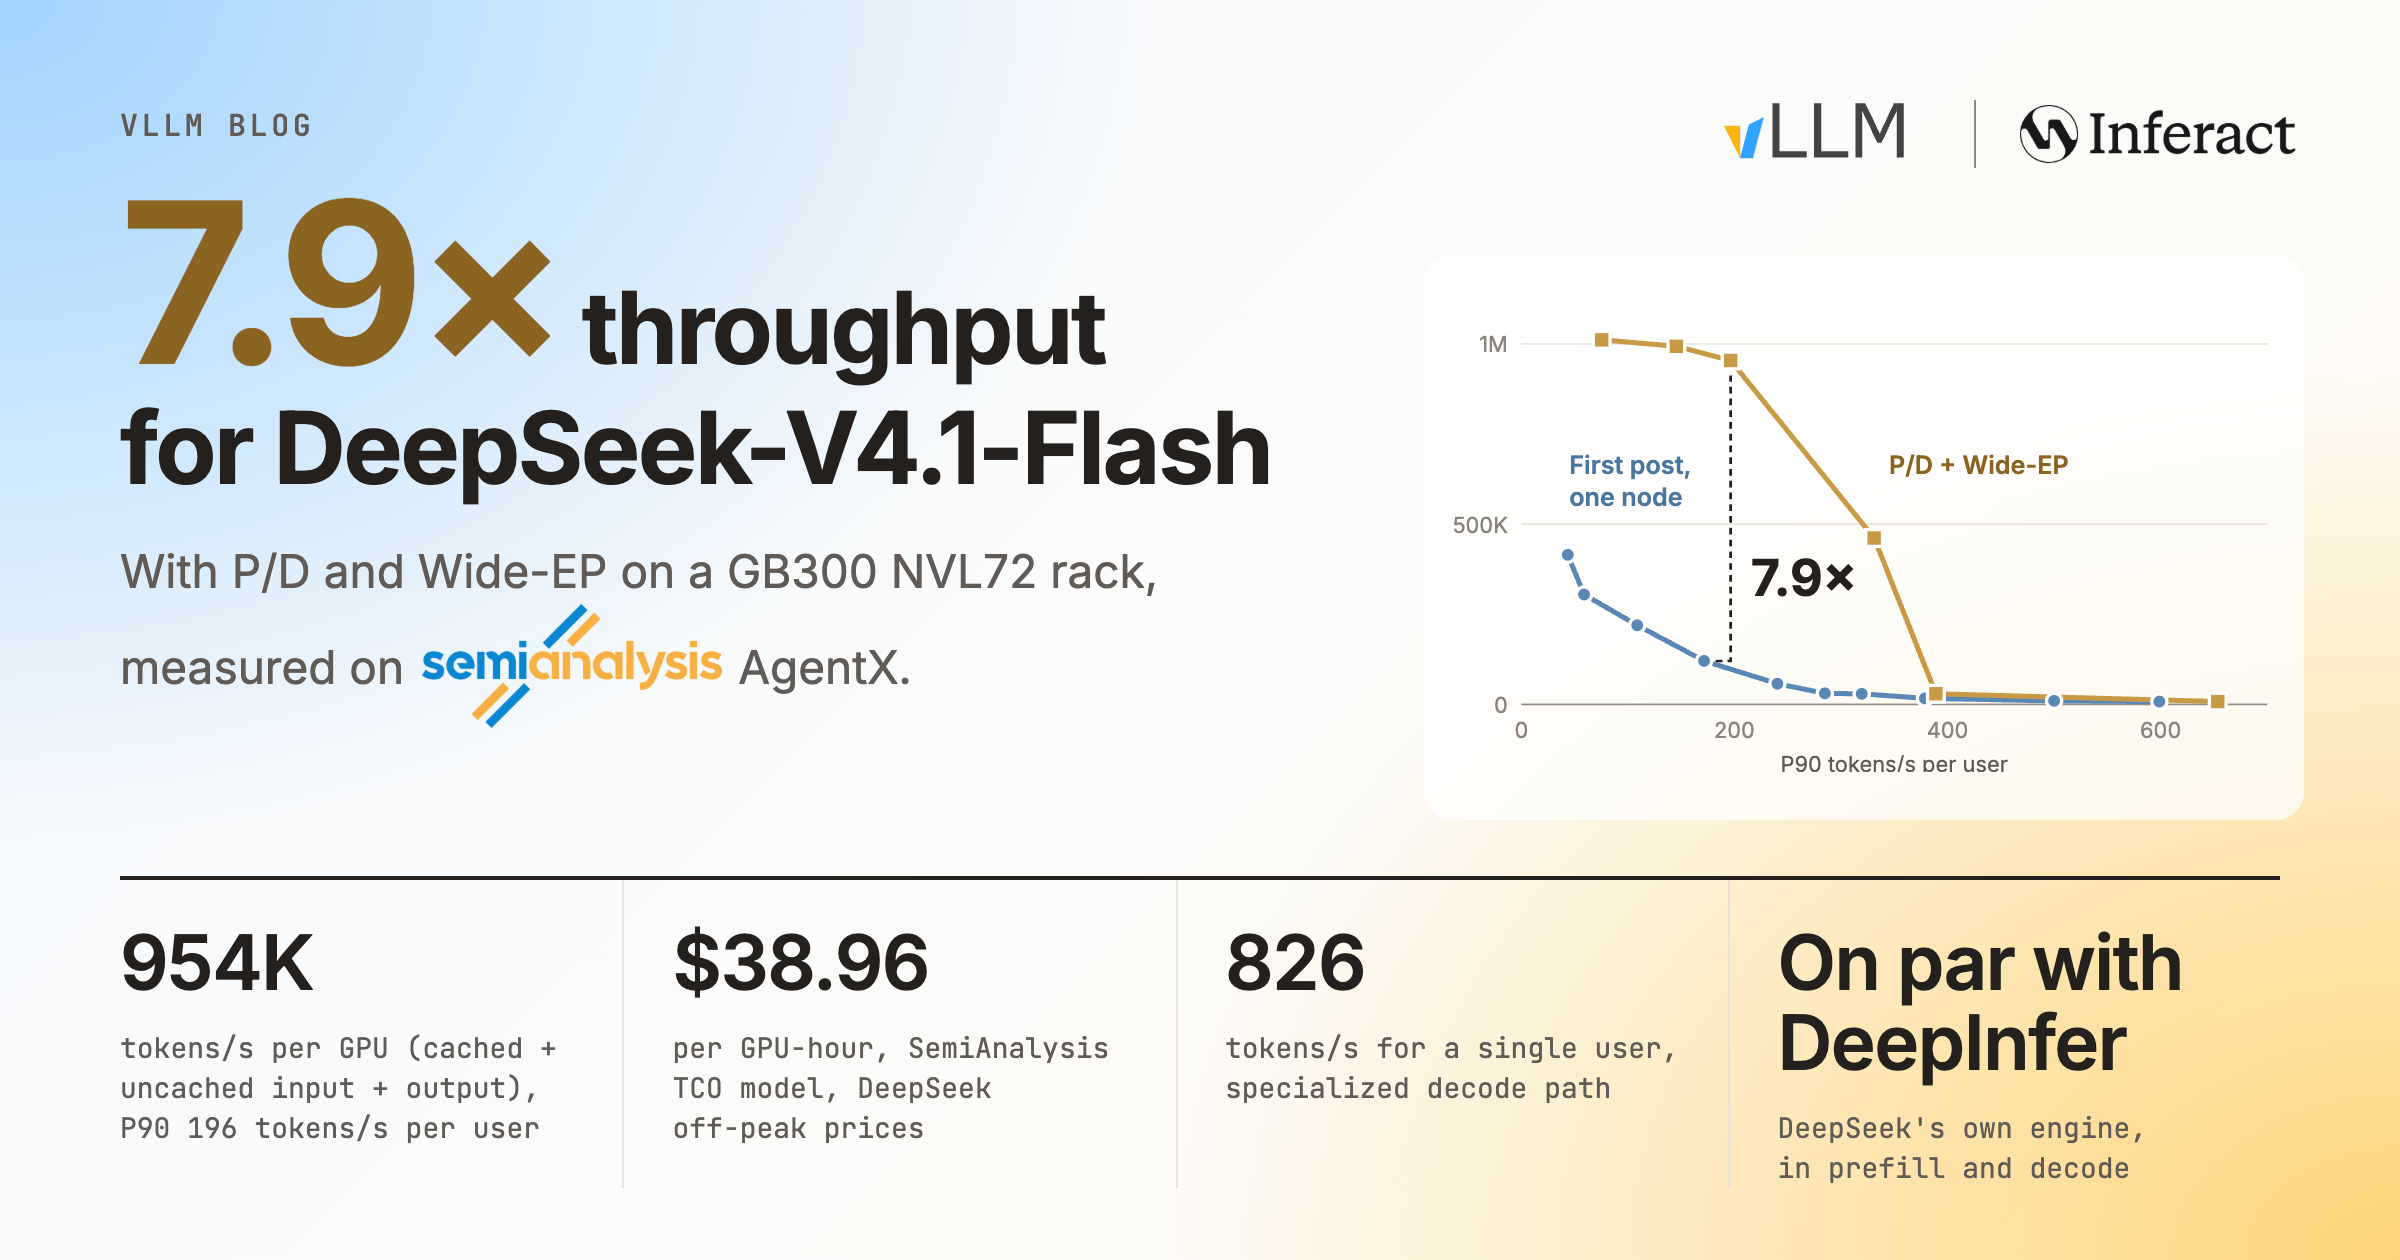
vLLM BlogToolsServing DeepSeek-V4.1-Flash at Scale: vLLM Matches DeepInfer and Scales to GB300 NVL72 With P/D disaggregation and Wide-EP on a GB300 NVL72 rack, vLLM serves DeepSeek-V4.1-Flash on SemiAnalysis AgentX at 954K tokens/s per GPU at a P90 of 196 tokens/s per user, 7.9x our aggregated…
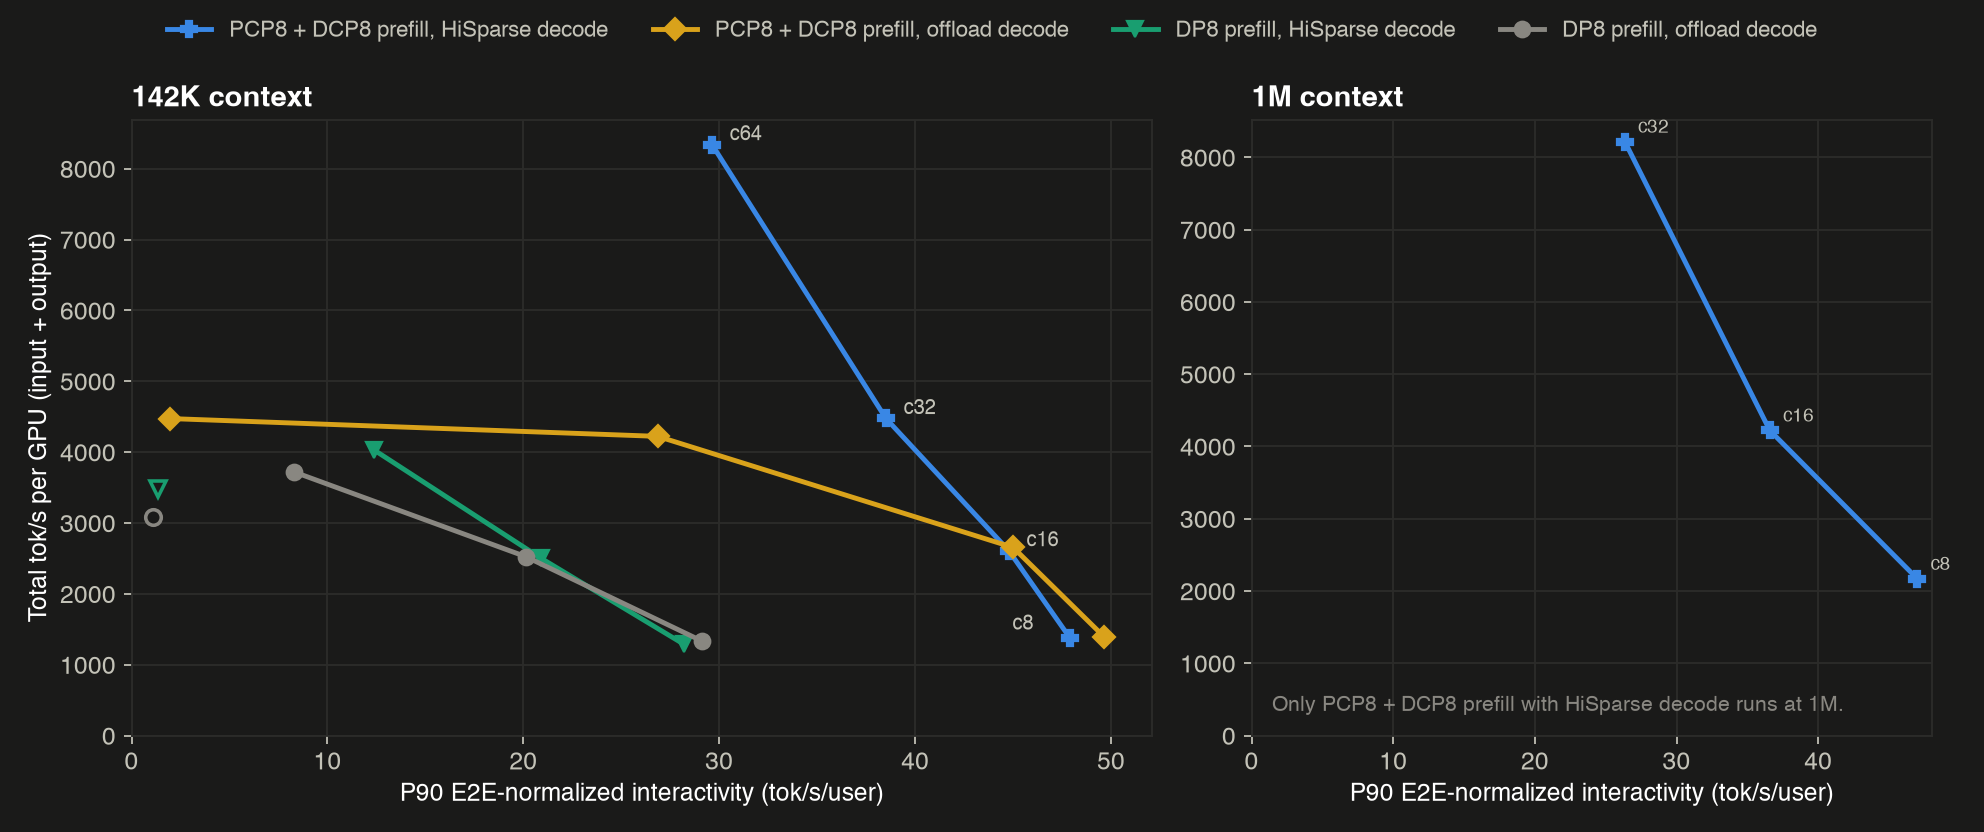
vLLM BlogToolsGLM-5.3 Optimizations, Part 2: PCP, DCP, and Hybrid HiSparse on 16 H200s vLLM serves GLM-5.3 on 16 H200s with PCP and DCP prefill and Hybrid HiSparse decode, reaching 1M-token contexts and 1.7–3.2× the per-user speed of data-parallel P/D on the AgentX agentic benchmark.
vLLM BlogToolsvLLM Delivers Day-0 Support for MiniMax-M3.1-Flash Day-0 vLLM support for MiniMax-M3.1-Flash on NVIDIA Blackwell, NVIDIA Rubin, and AMD MI350-series GPUs, with NVFP4 MSA kernels, NVFP4 MegaMoE, DSpark speculative decoding, AgentX results, and day-0…
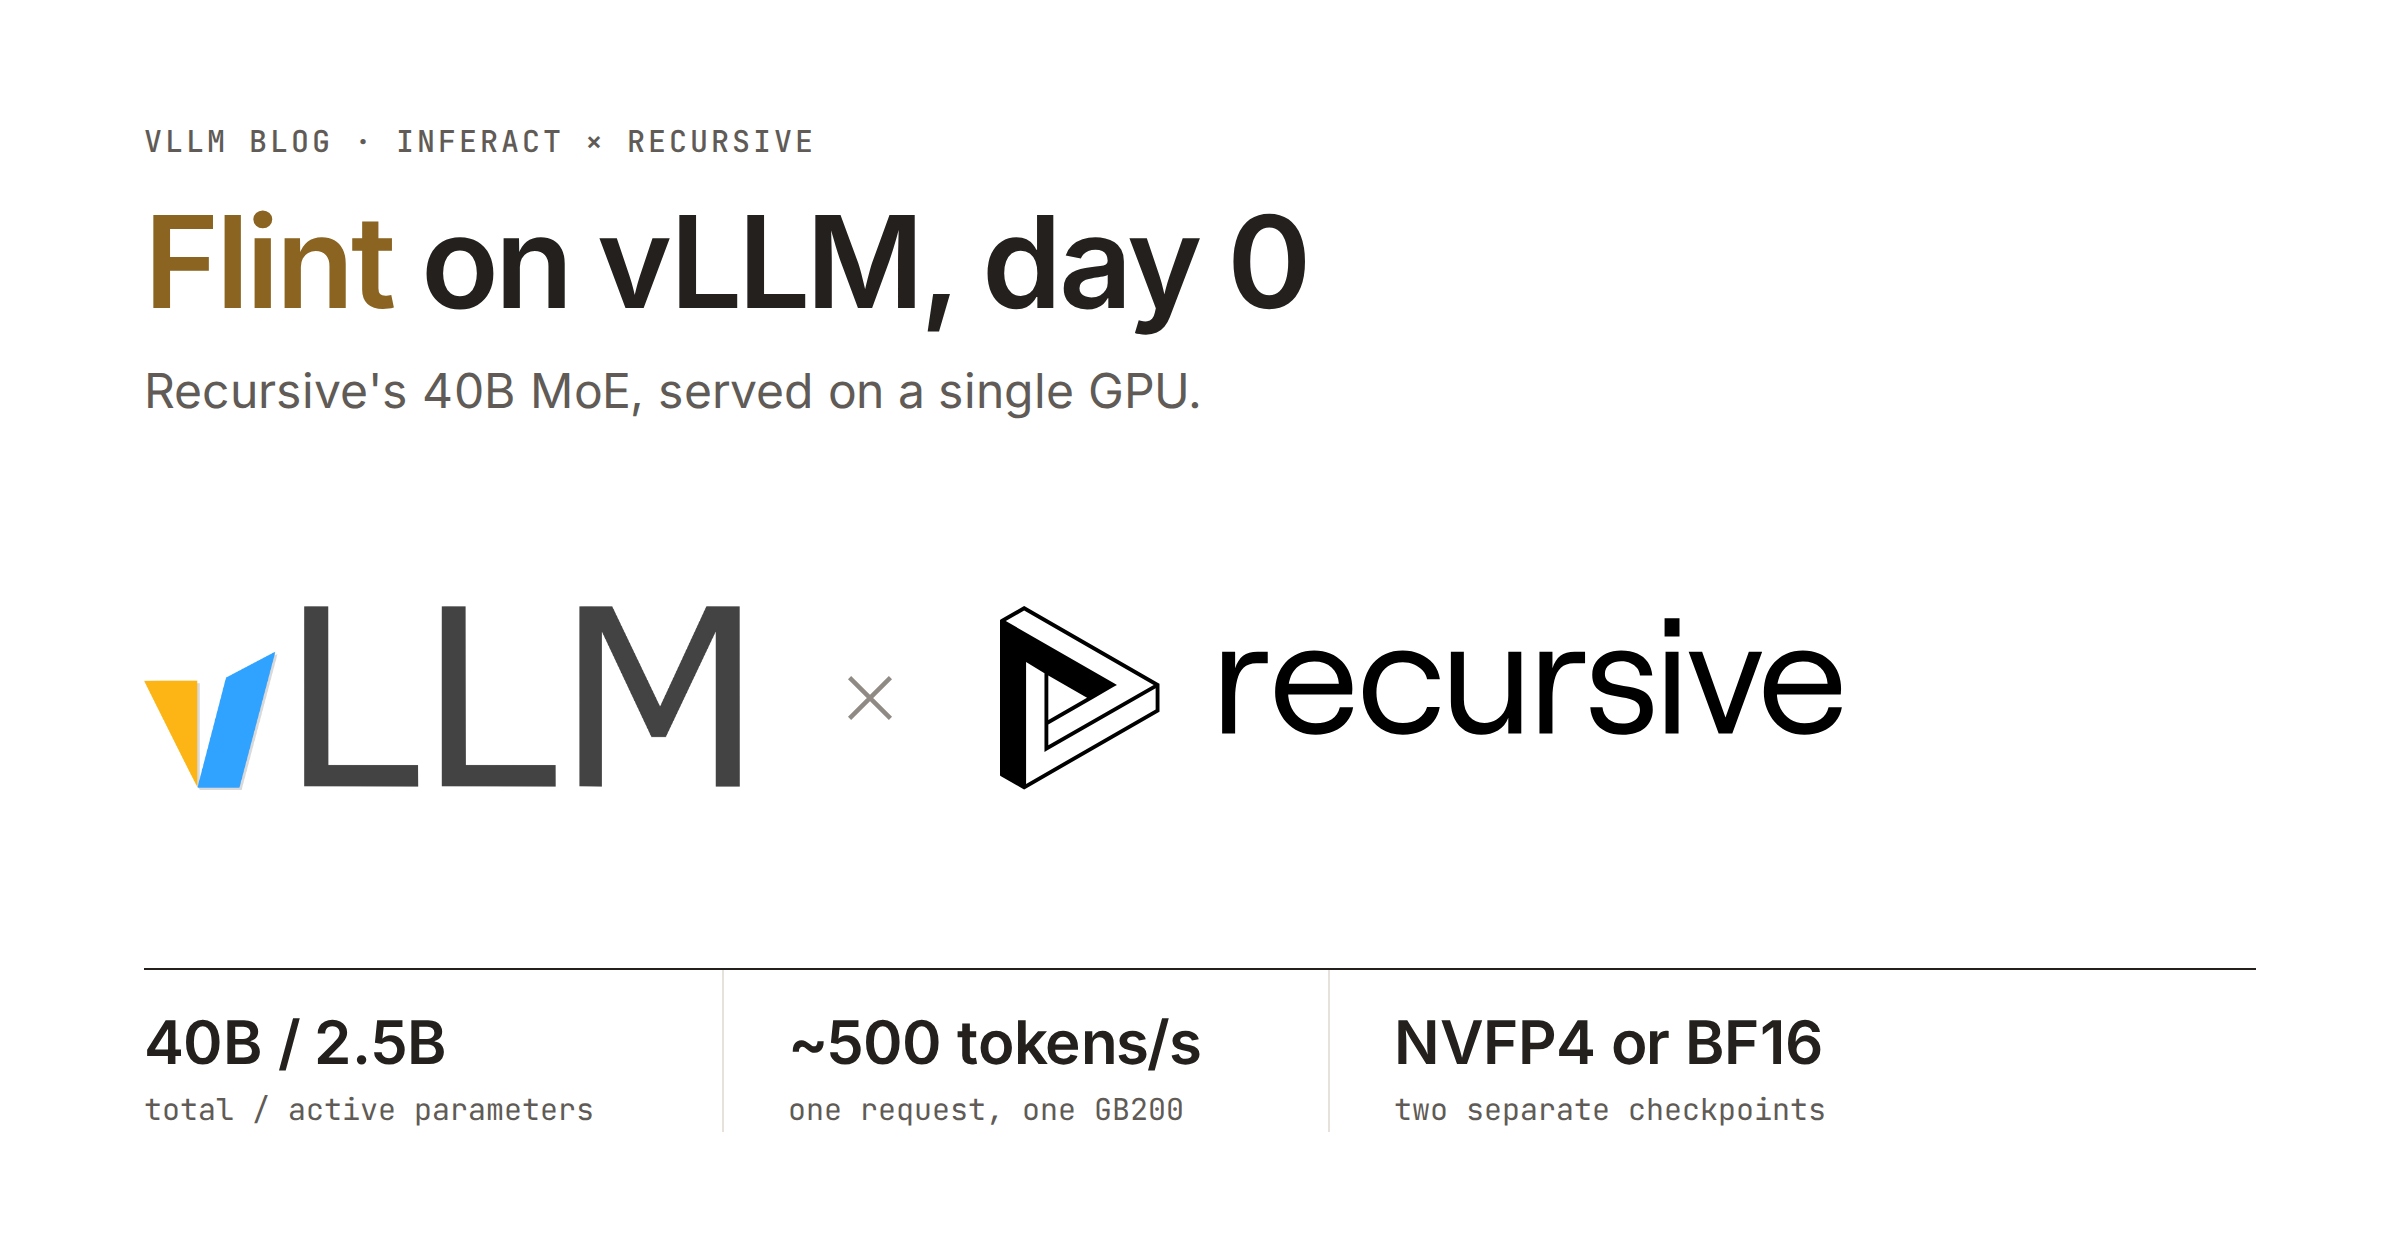
vLLM BlogToolsDay-0 Support for Flint on vLLM vLLM supports both Flint checkpoints (40B total, 2.5B active) from day 0, decoding a single request at about 500 tokens/s on one GPU.
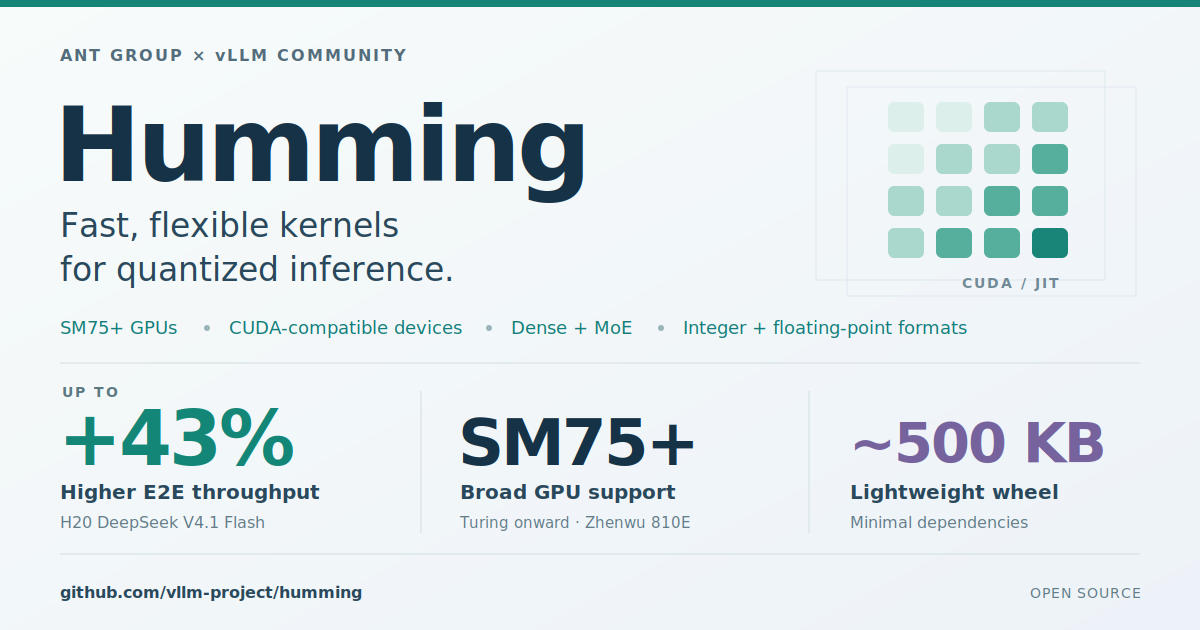
vLLM BlogToolsAnnouncing Humming: Fast, Flexible Kernels for Quantized Inference Introducing Humming, a quantized inference kernel library from Ant Group and the vLLM community, with broad GPU and quantization support, dense and MoE performance results, and vLLM integration.
vLLM BlogToolsIntroducing vLLM TorchTPU vllm-torchtpu is a new vLLM backend for Google Cloud TPUs built on TorchTPU, with Pallas kernels, multi-host parallelism, KV cache offloading, and disaggregated serving.
vLLM BlogToolsAchieving near-zero-downtime scaling in Elastic Expert Parallelism How asynchronous preparation and NIXL EP enabled near-zero-downtime Elastic EP scaling in vLLM.
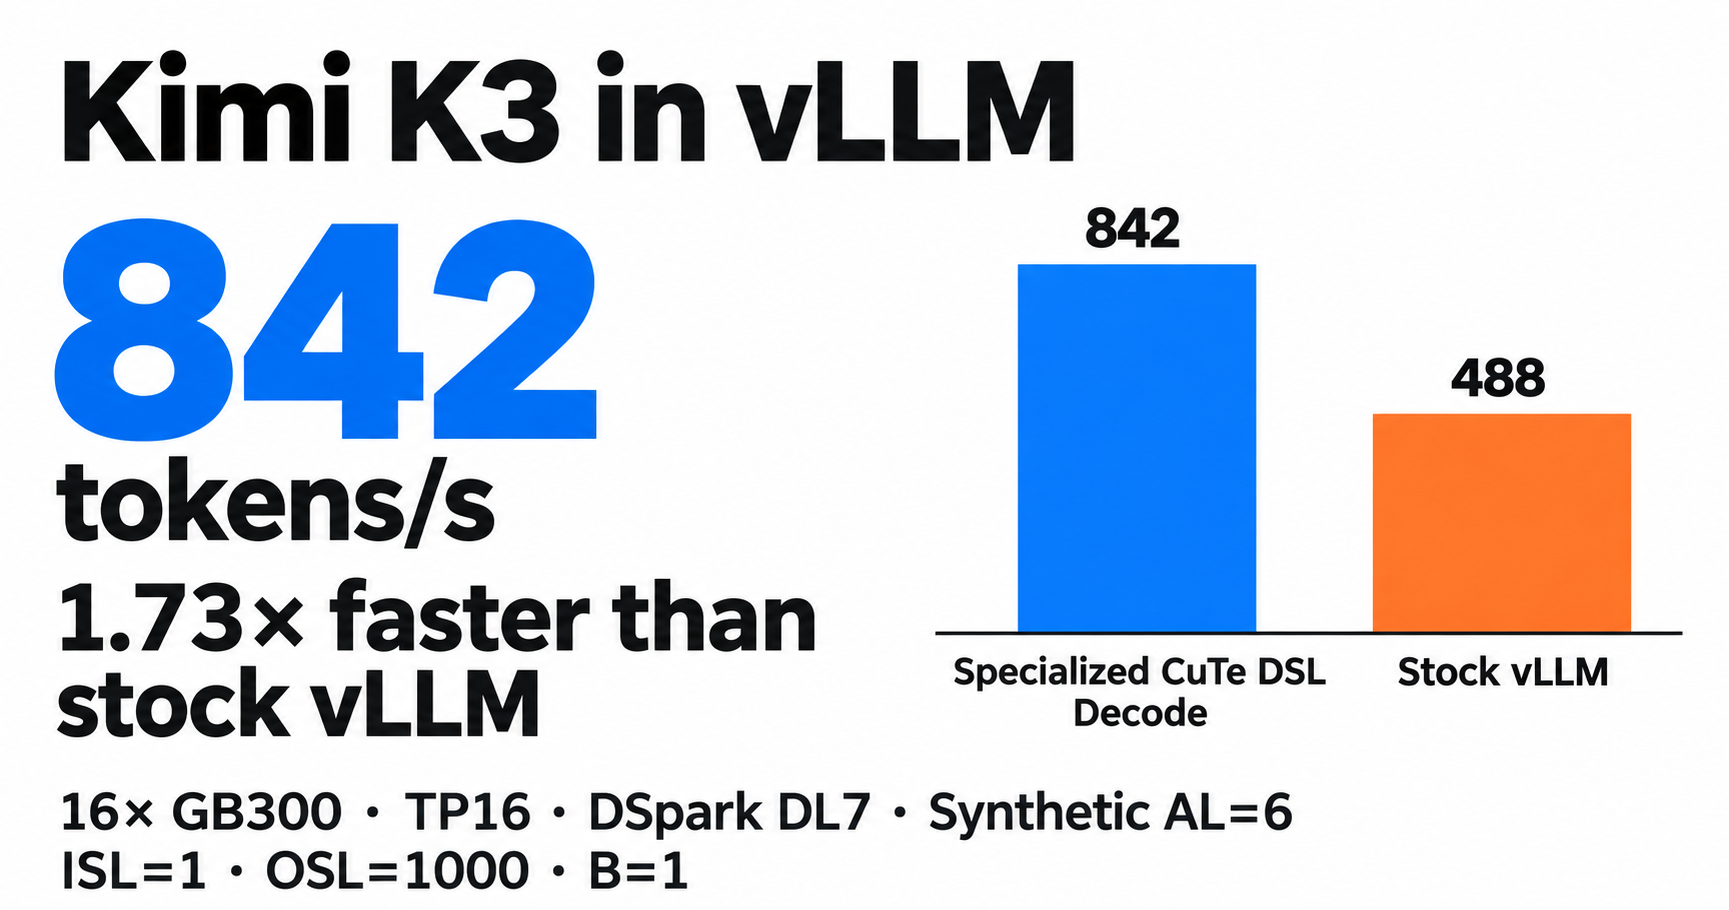
vLLM BlogToolsHyper Optimizing Kimi K3 in vLLM: Moving Fast and Responsibly How agent-assisted CuTe DSL optimizations accelerate Kimi K3 decode on NVIDIA GB300, and how scoped changes, correctness tests, and reproducible benchmarks help ship them responsibly.
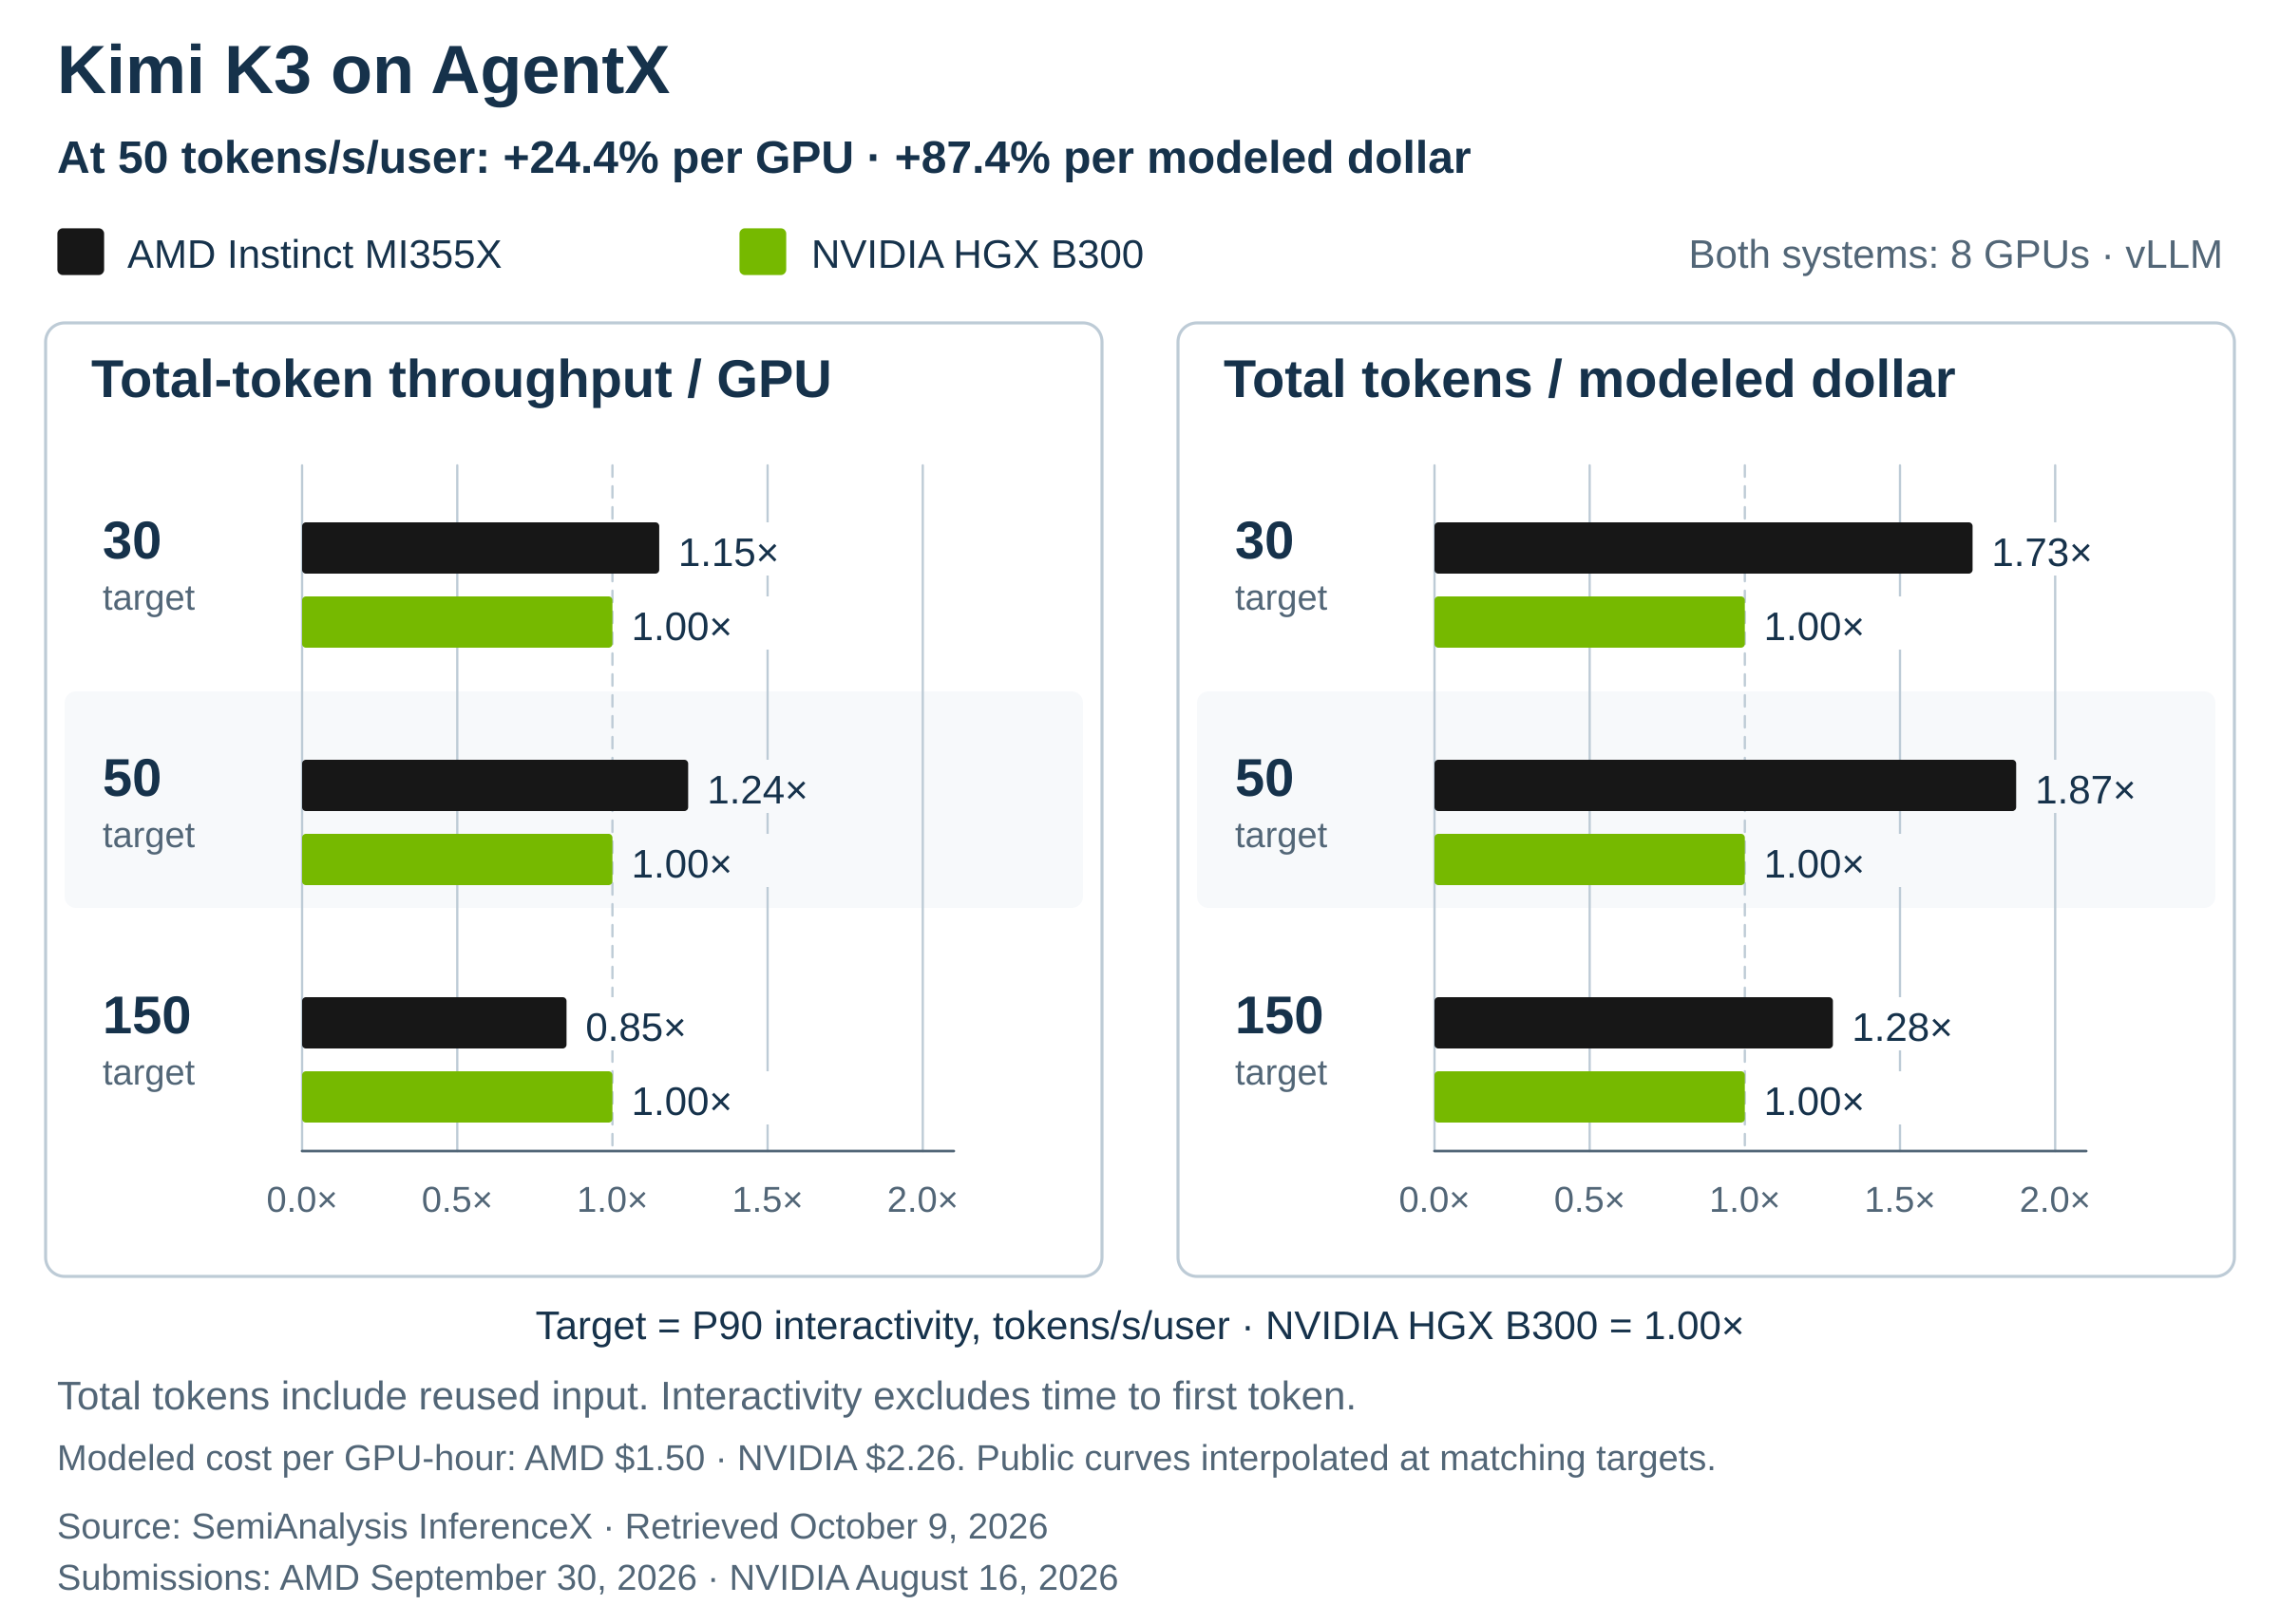
vLLM BlogToolsScaling Kimi K3 on AMD Instinct MI355X: Matching NVIDIA HGX B300 Throughput per GPU on AgentX Inside the Kimi K3 optimization effort: understanding the bottlenecks and the decisions that made inference faster
vLLM BlogToolsServing Reflection Beam on vLLM from Day 0 vLLM supports Reflection's Beam-1.0 (501B total, 23B active) from day 0, with agent-driven optimization that cut decode latency 2.71× and DFlash2 speculative decoding with adaptive verification.
vLLM BlogToolsDay 0 support for Muse Spark Open on vLLM Day-0 vLLM support for Muse Spark Open: 816B MoE, 1M context, multimodal inputs, DSpark speculative decoding, NVIDIA and AMD serving, initial TPU support, and LoRA RL.
vLLM BlogToolsAnnouncing Day 0 Support for NVIDIA Nemotron 3.5 Super VL on vLLM Run NVIDIA Nemotron 3.5 Super VL on vLLM for multimodal agent workflows with image, document, and video understanding, OpenAI-compatible serving, and multi-token prediction.
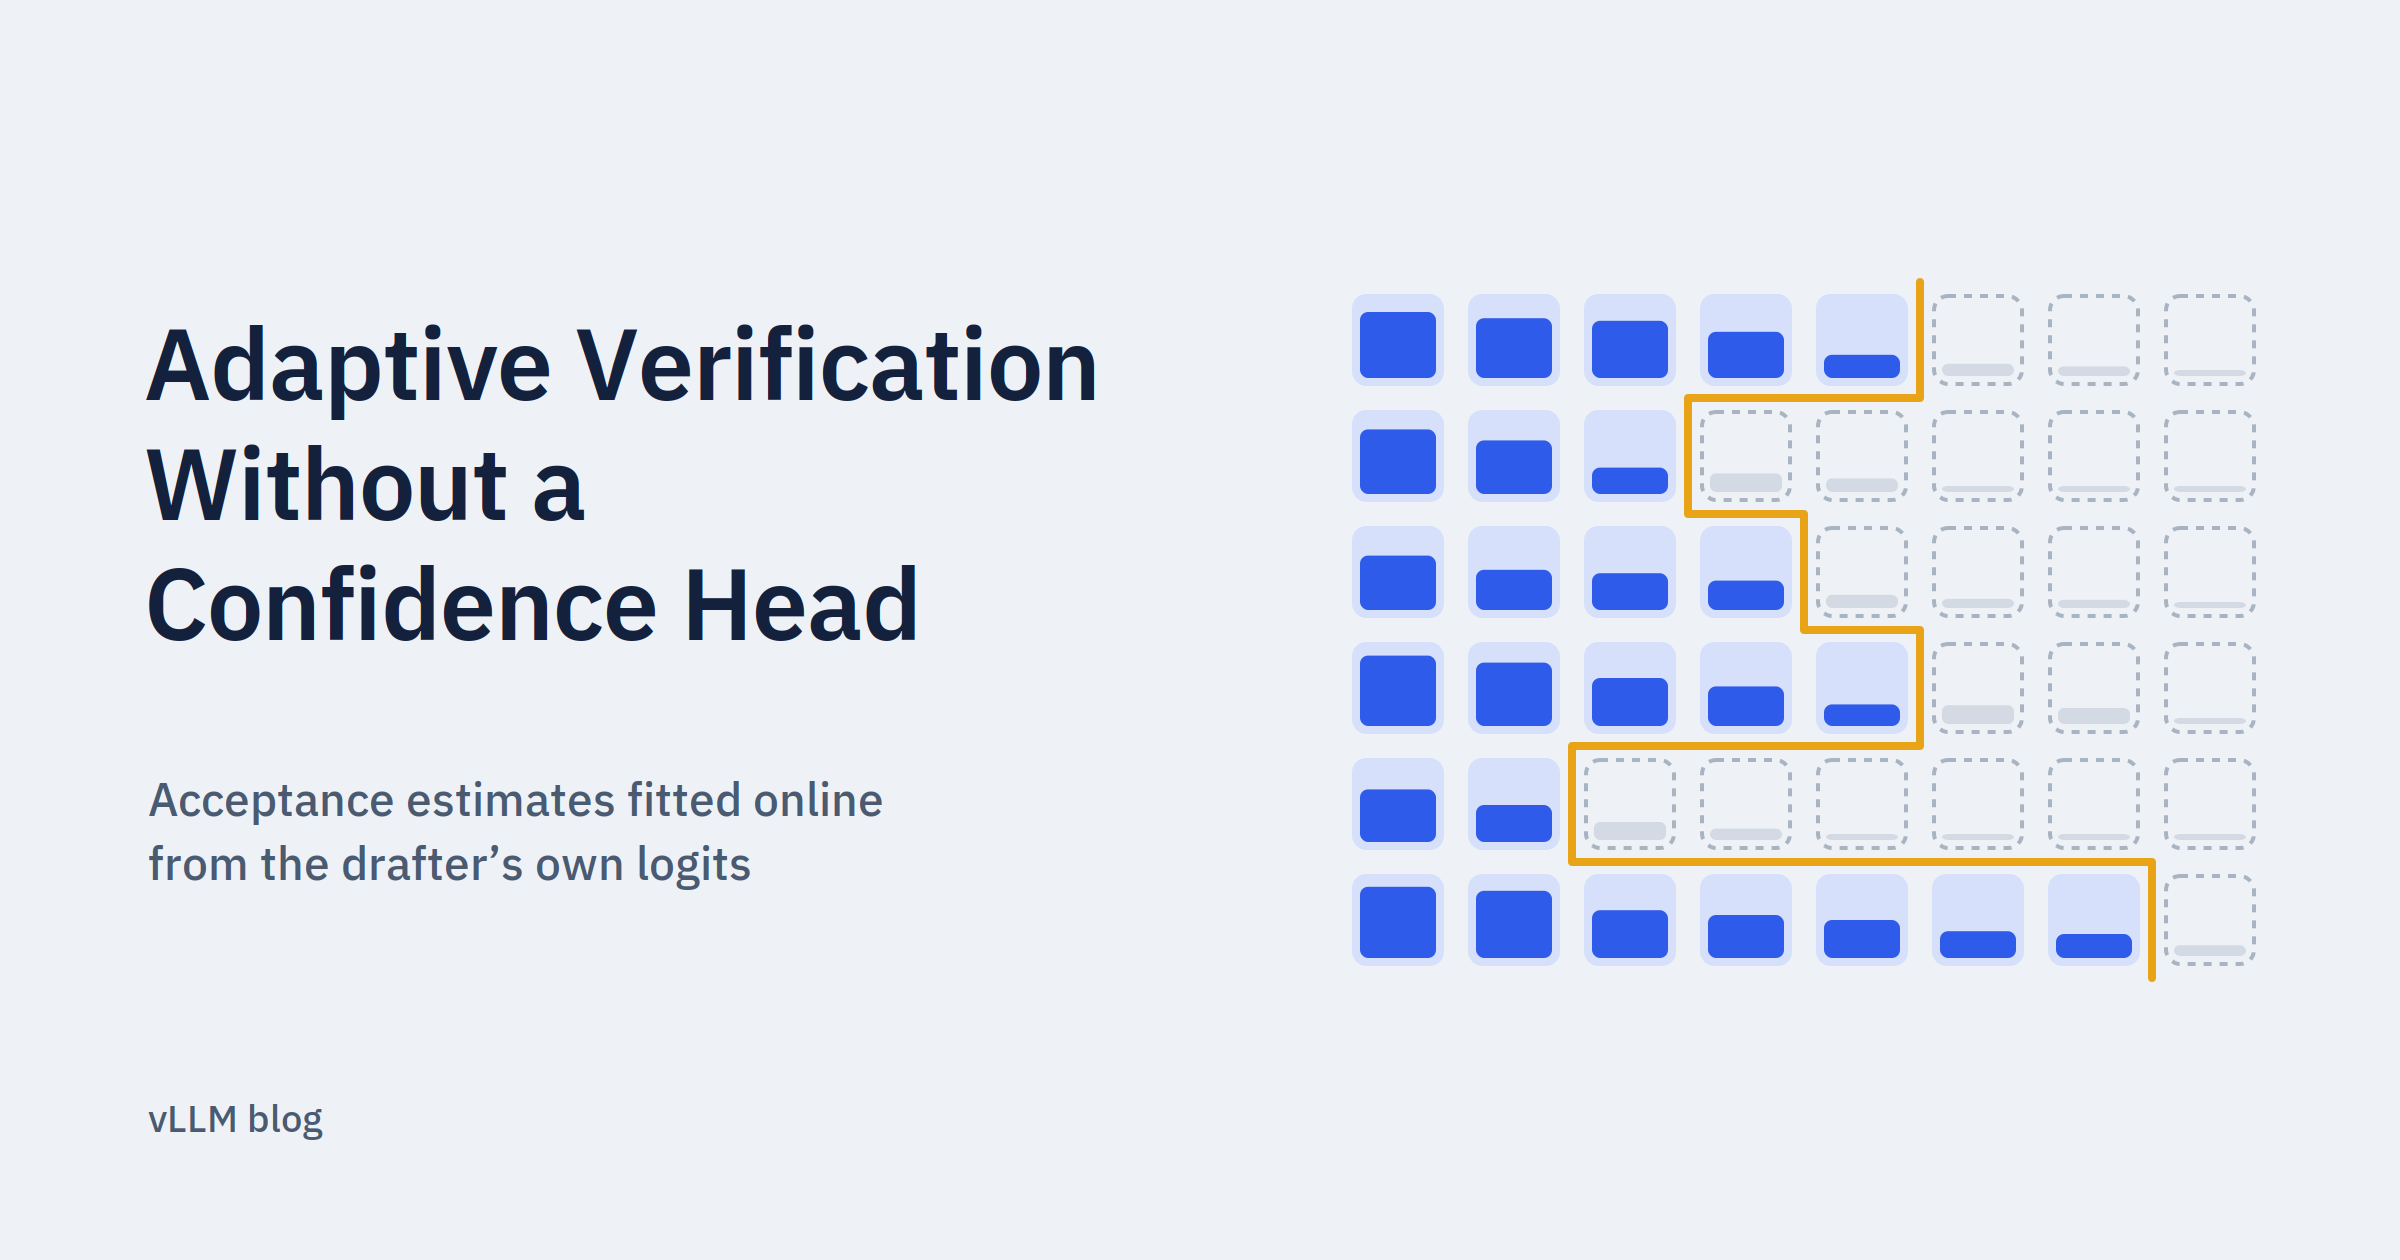
vLLM BlogToolsAdaptive Verification Without a Confidence Head An online-fitted acceptance estimator that lets every draft-model speculator use Adaptive Verification, by predicting the target's acceptance probability from the drafter's own logits and refitting…
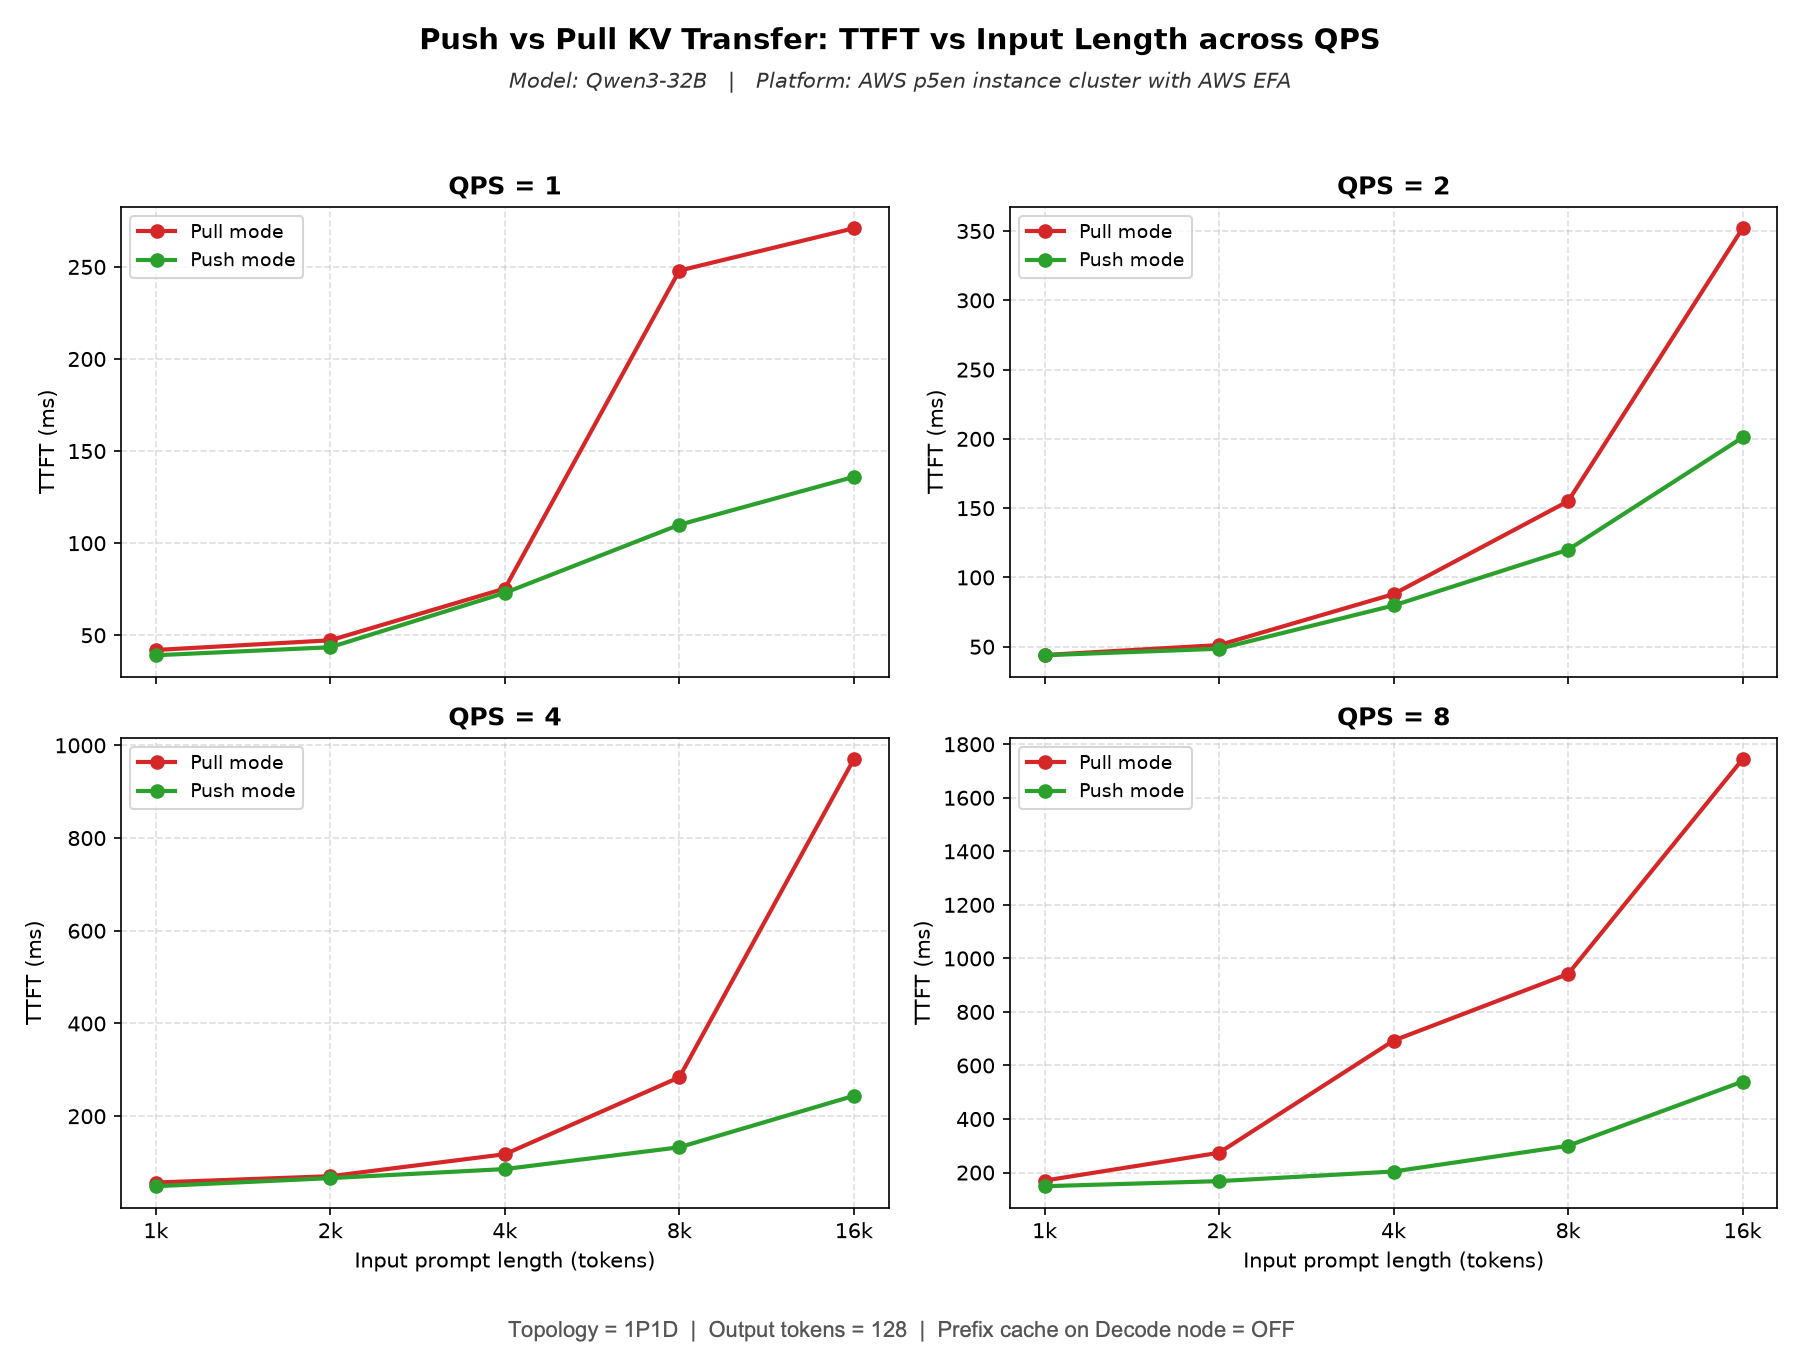
vLLM BlogToolsPush-Based KV Transfer to Improve TTFT and TPOT for Disaggregated Inference in vLLM A push-based NIXL connector for vLLM disaggregated serving: the prefill instance writes KV directly into decode memory over RDMA, taking the router relay, decode-side allocation, and transfer setup…
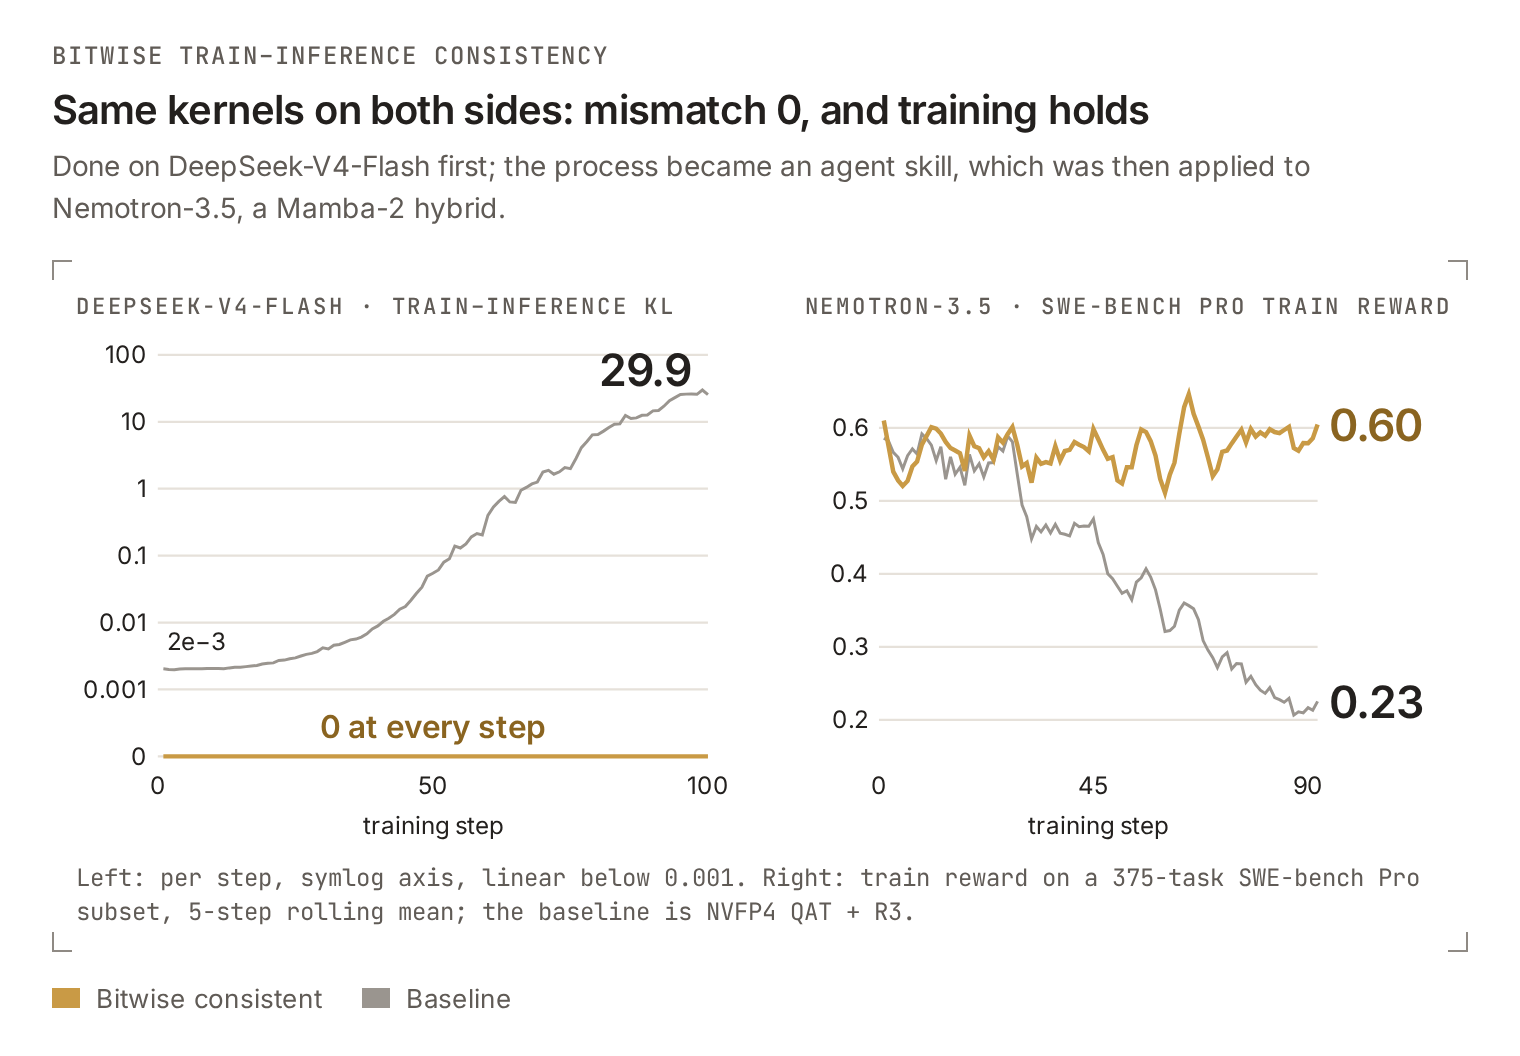
vLLM BlogToolsFinish RL Training Faster: Bitwise-Consistent, High-Performance, Agent-Driven We make vLLM rollout and the training forward give bitwise identical logprobs on DeepSeek-V4-Flash and Nemotron-3.5-Lightning-30B-A3B (NVFP4), keep 91% of rollout throughput on DeepSeek-V4-Flash, and…
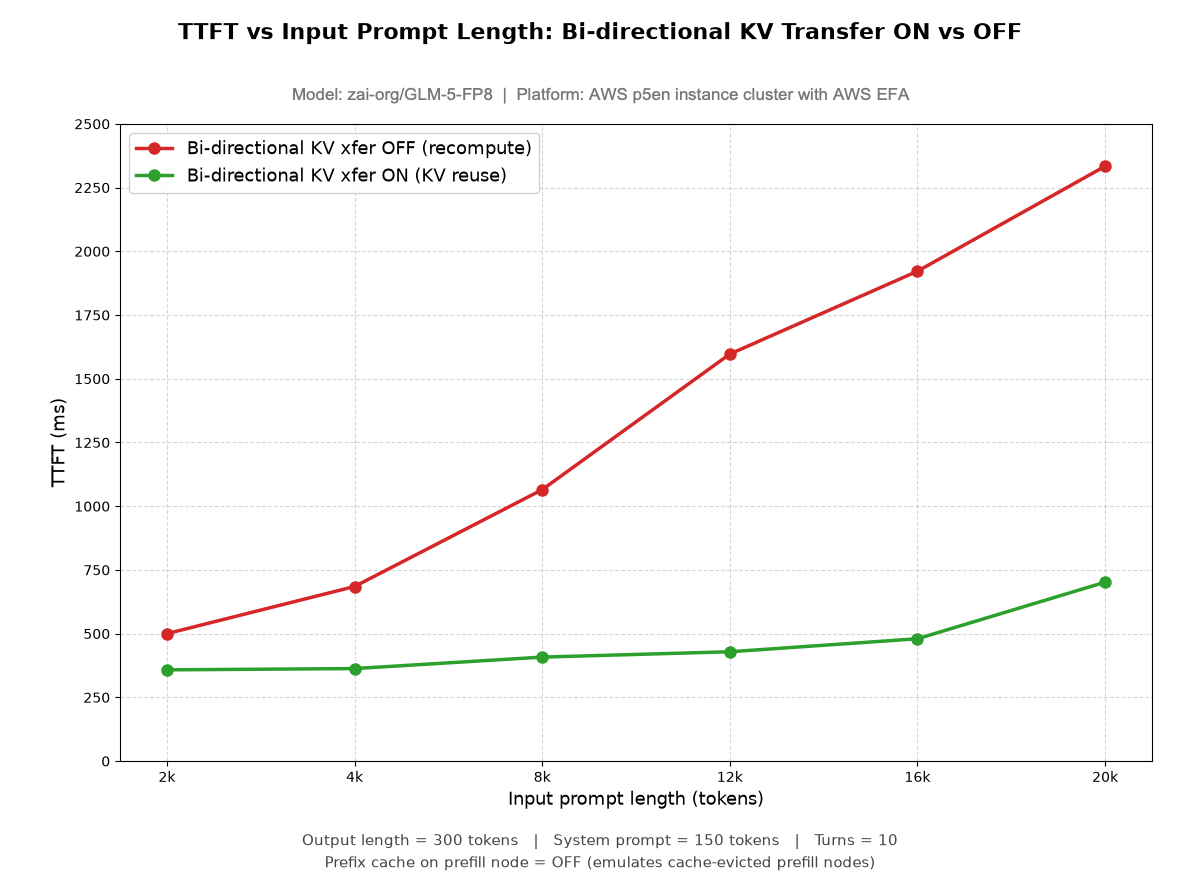
vLLM BlogToolsImprove TTFT for Multi-Turn Agentic Workloads with Bi-Directional KV Transfer in vLLM Bi-directional KV transfer lets vLLM prefill nodes reuse previously computed KV from decode nodes on later conversation turns, cutting redundant prefill recompute and reducing TTFT by up to 3.3x on…
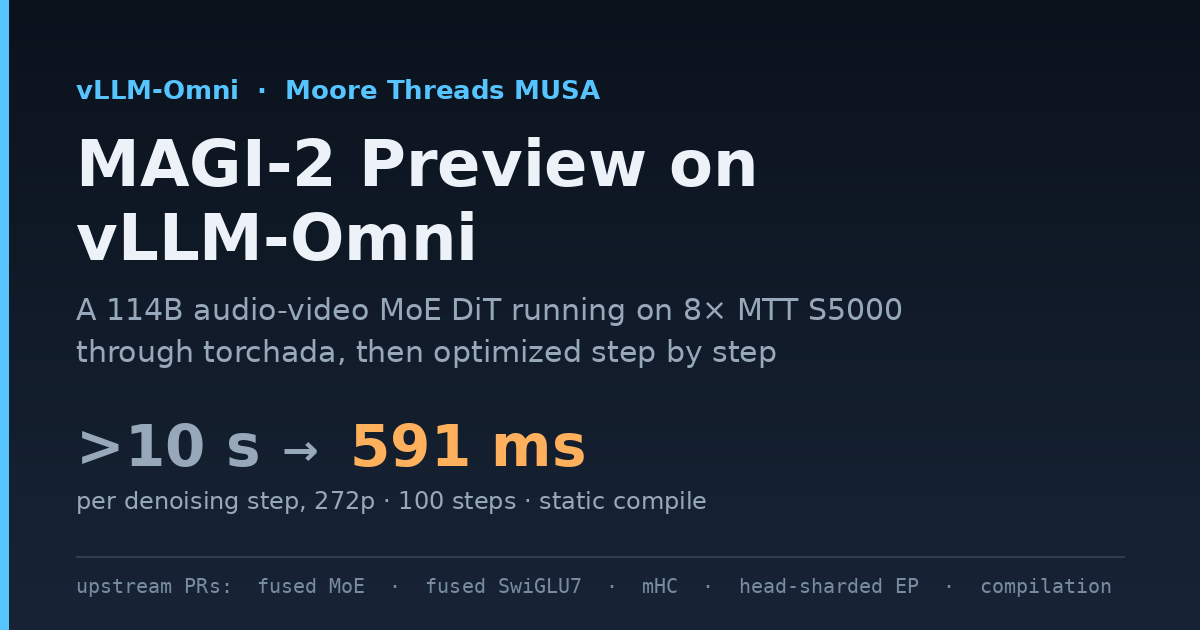
vLLM BlogToolsMAGI-2 Preview on vLLM-Omni: Bringing a 114B Audio-Video MoE DiT to Moore Threads MUSA with torchada vLLM-Omni runs Sand AI's MAGI-2 Preview audio-video generation model on eight Moore Threads MTT S5000 GPUs through torchada's CUDA compatibility layer, then optimizes MoE, mHC, attention…
vLLM BlogToolsvLLM Support for NVIDIA Vera Rubin NVL72: 7.8x Throughput over GB200 NVL72 vLLM now runs on NVIDIA Vera Rubin NVL72 with day-0 model support, Rubin-tuned FlashInfer kernels, and locality-aware MoE, delivering 7.8x the per-GPU throughput of GB200 NVL72 on AgentX.
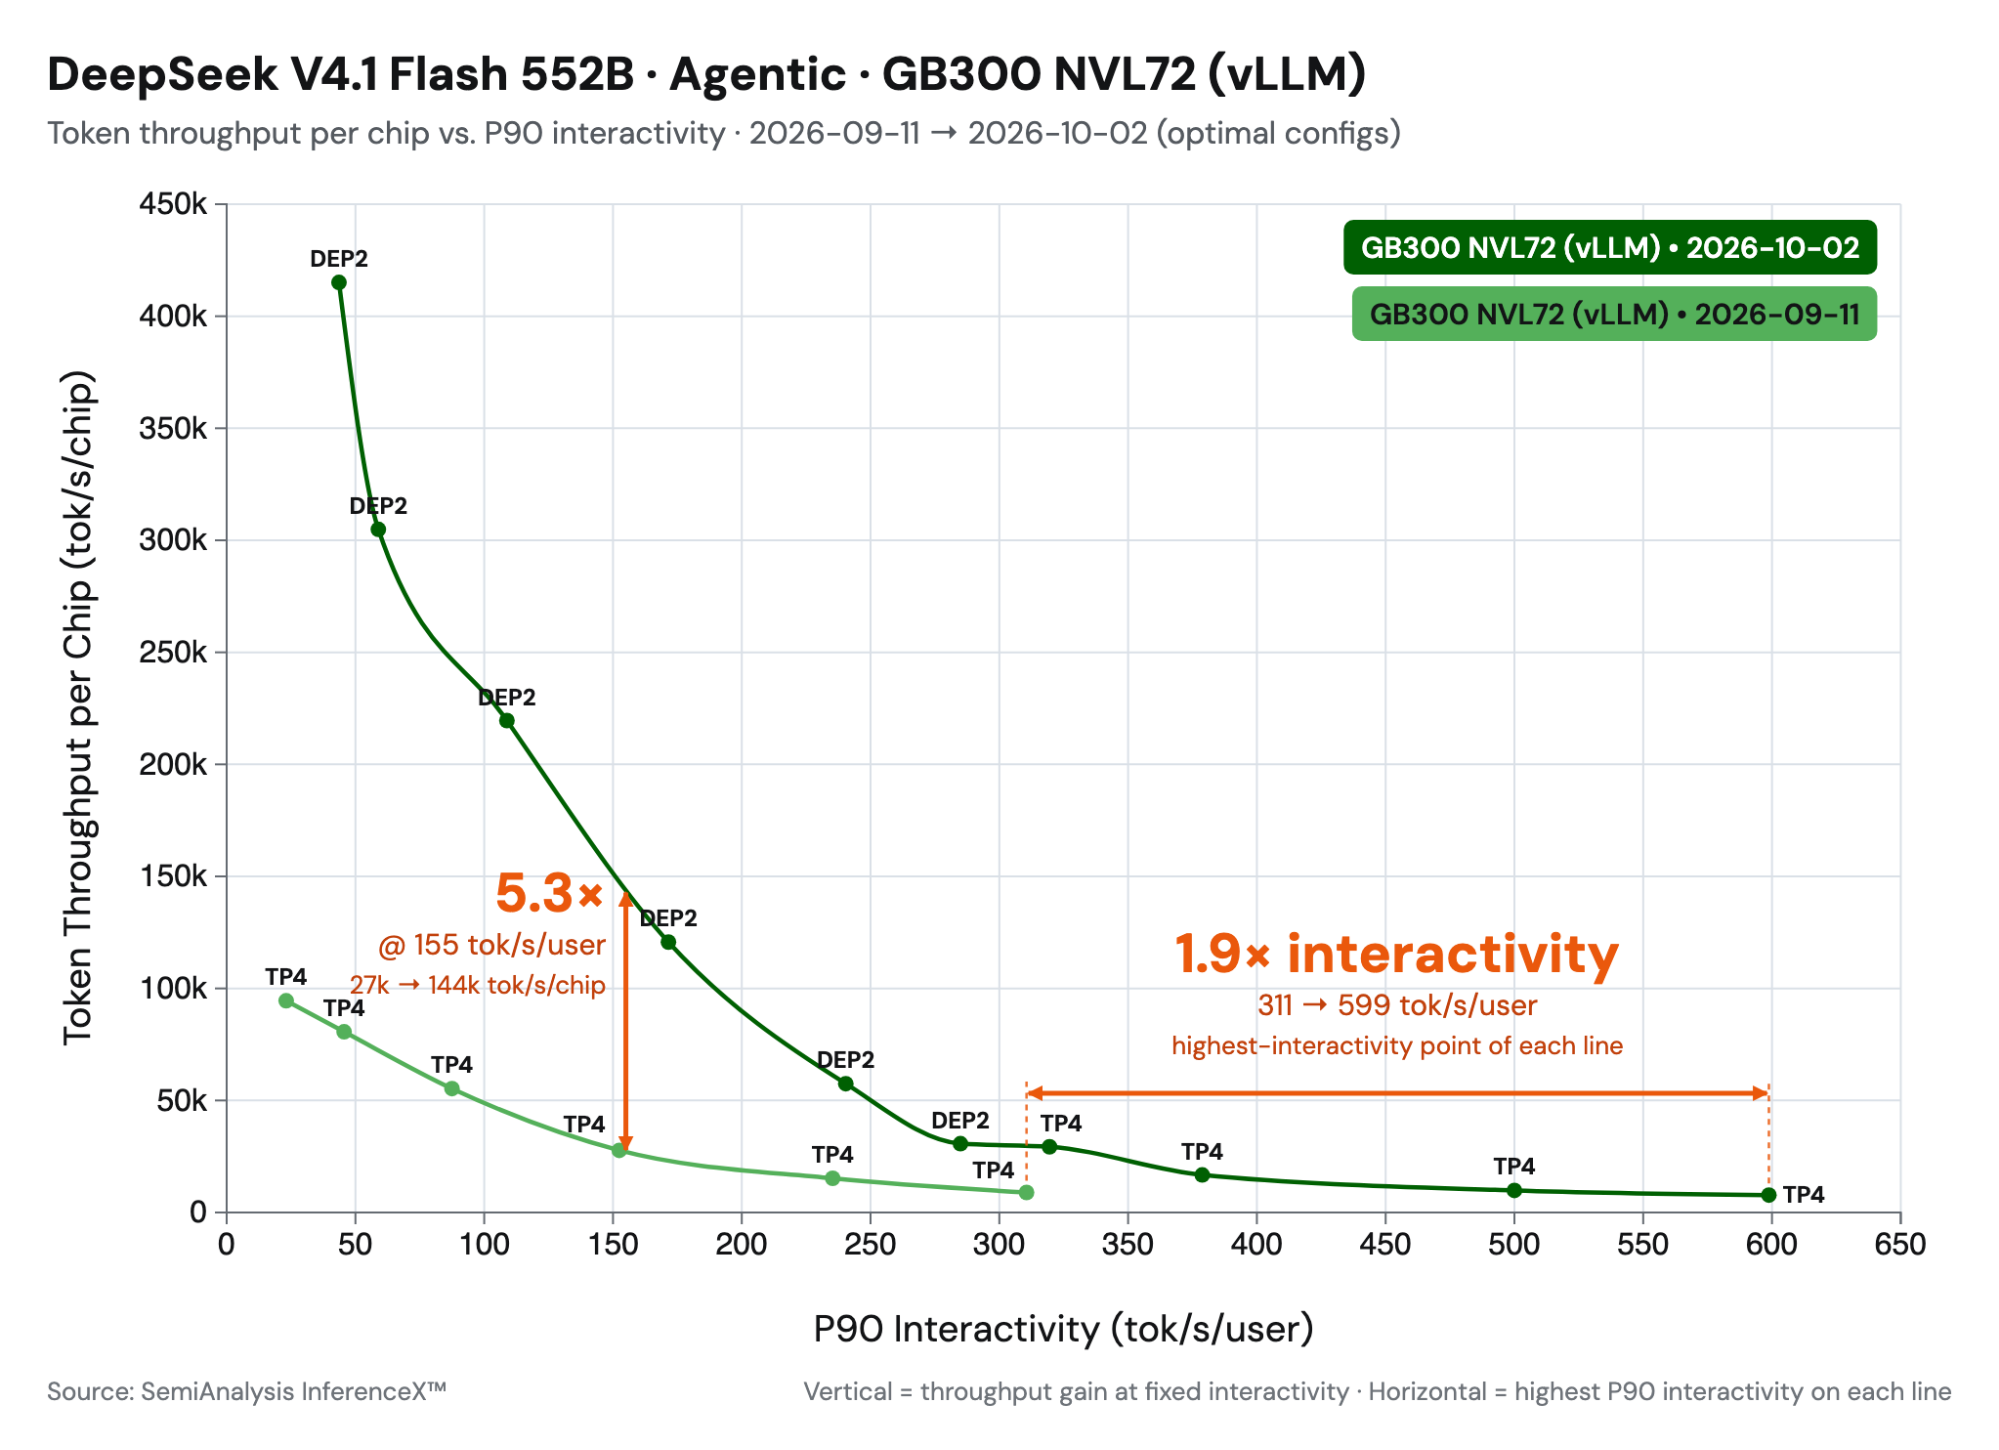
vLLM BlogToolsDeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 Within three weeks of release, vLLM made DeepSeek-V4.1-Flash 1.9x faster at low concurrency and lifted its throughput 5x on SemiAnalysis AgentX, with SWA bounded replay, CUDA graphs, DeepSeek's new…
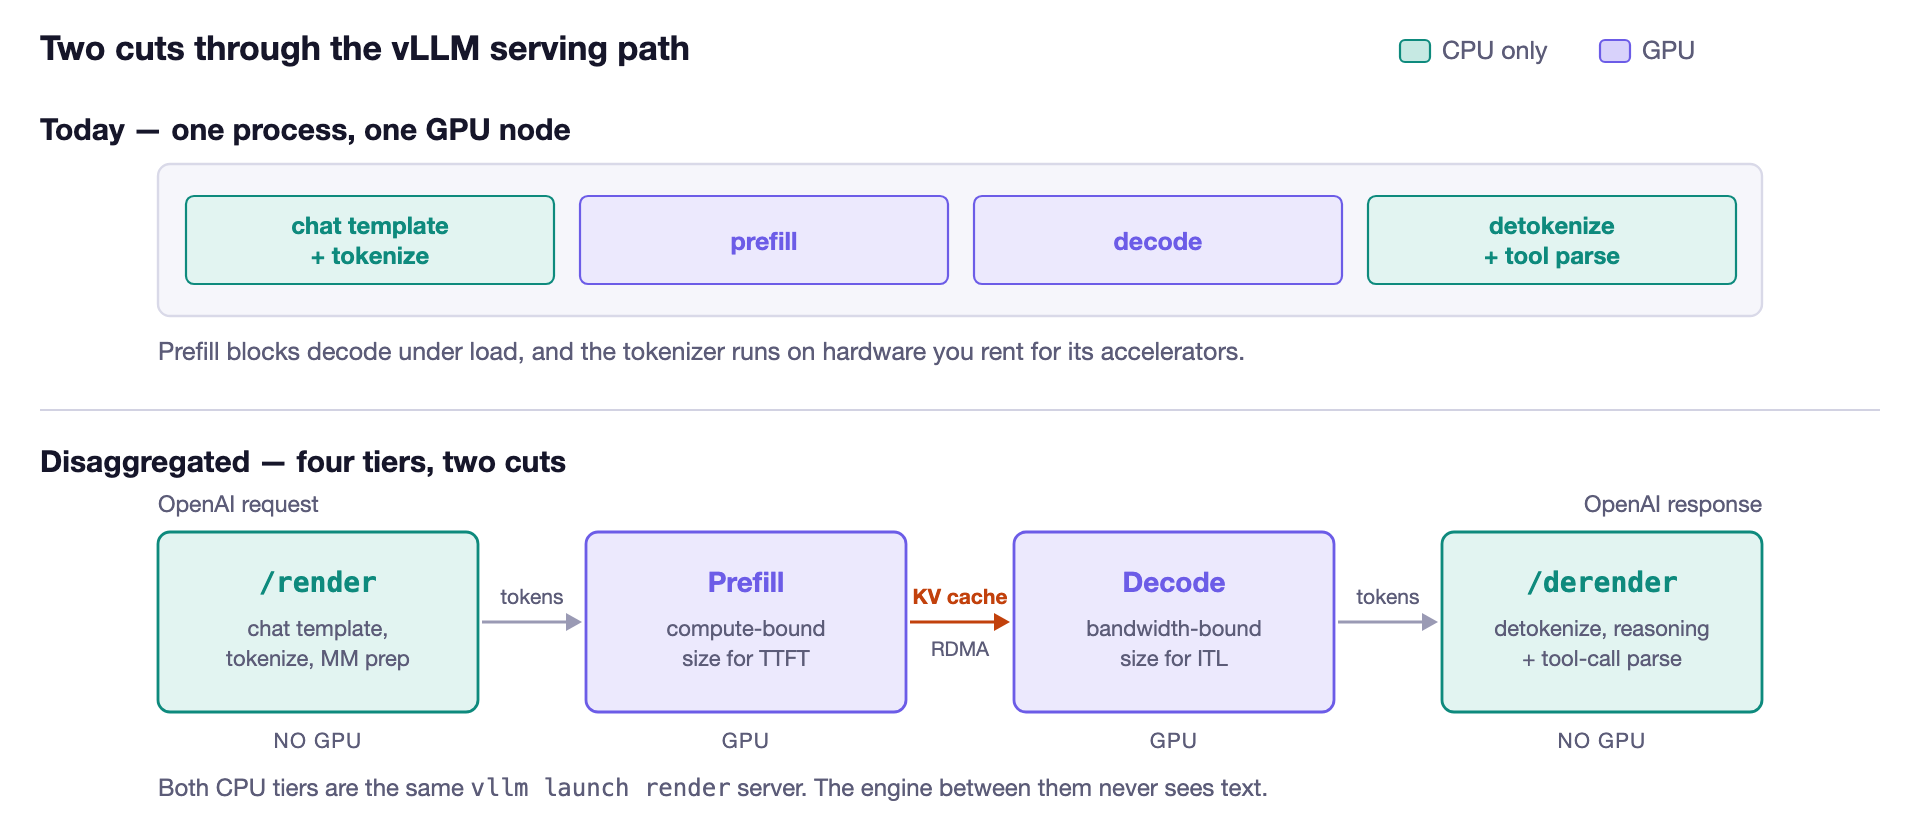
vLLM BlogToolsTaking vLLM Apart: A Practical Guide to Disaggregated Serving What disaggregated serving actually buys you, how to run it end to end in vLLM today with prefill/decode plus the new GPU-less frontend and the things we're still working on.
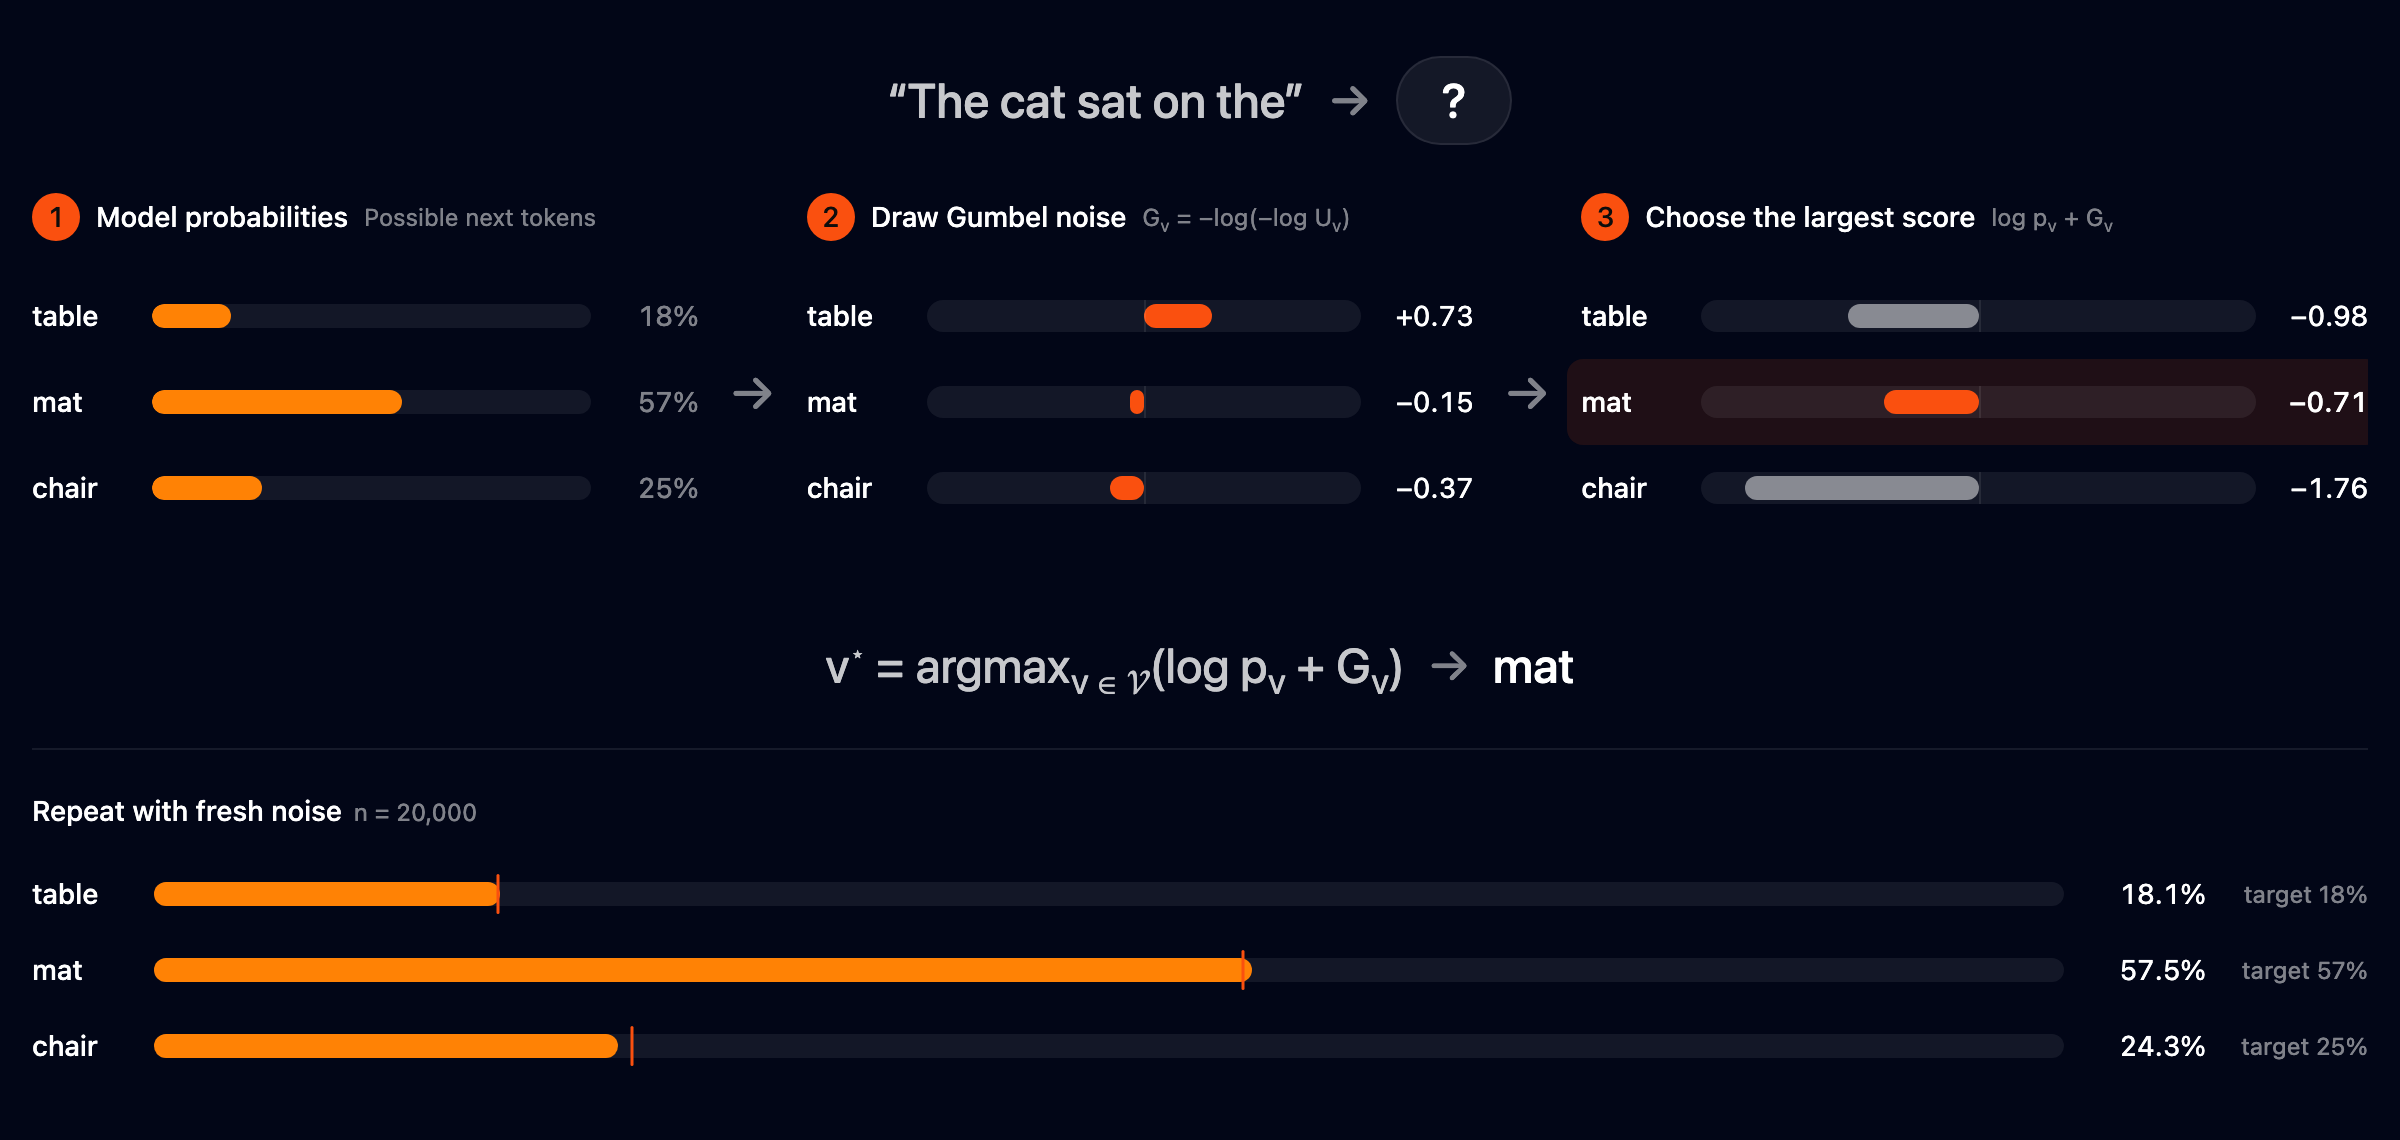
vLLM BlogToolsWatermarking in vLLM How vLLM implements distribution-preserving Gumbel-max text watermarking with efficient GPU kernels, statistical detection, speculative decoding, and repeated-context safeguards.
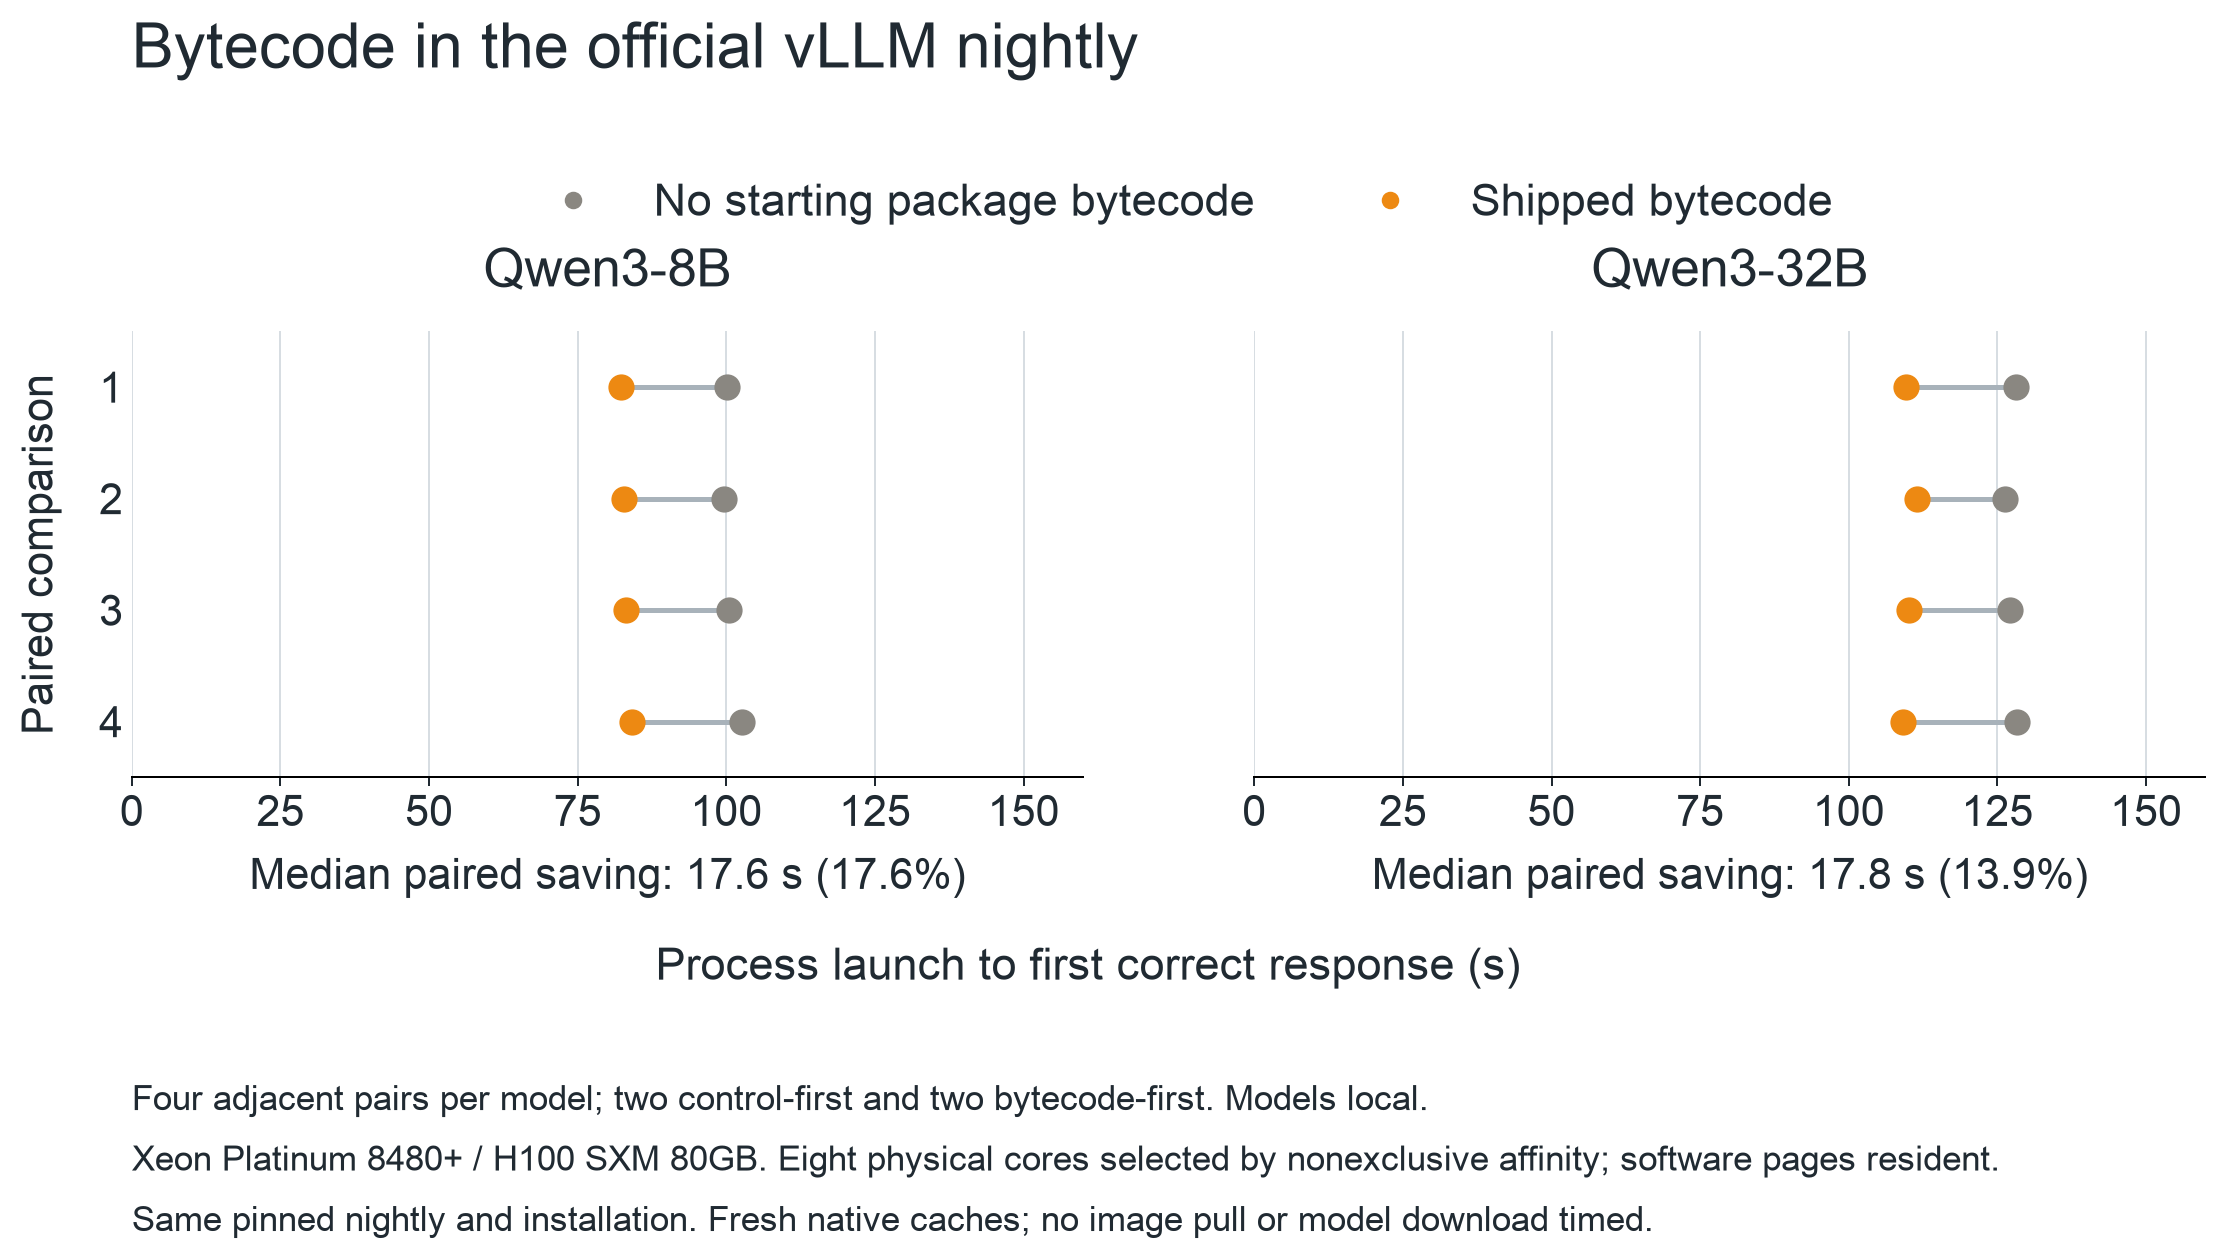
vLLM BlogToolsReducing vLLM startup time with one uv flag Shipping Python bytecode saved about 18 seconds per startup in H100 server benchmarks, with images and models already local.
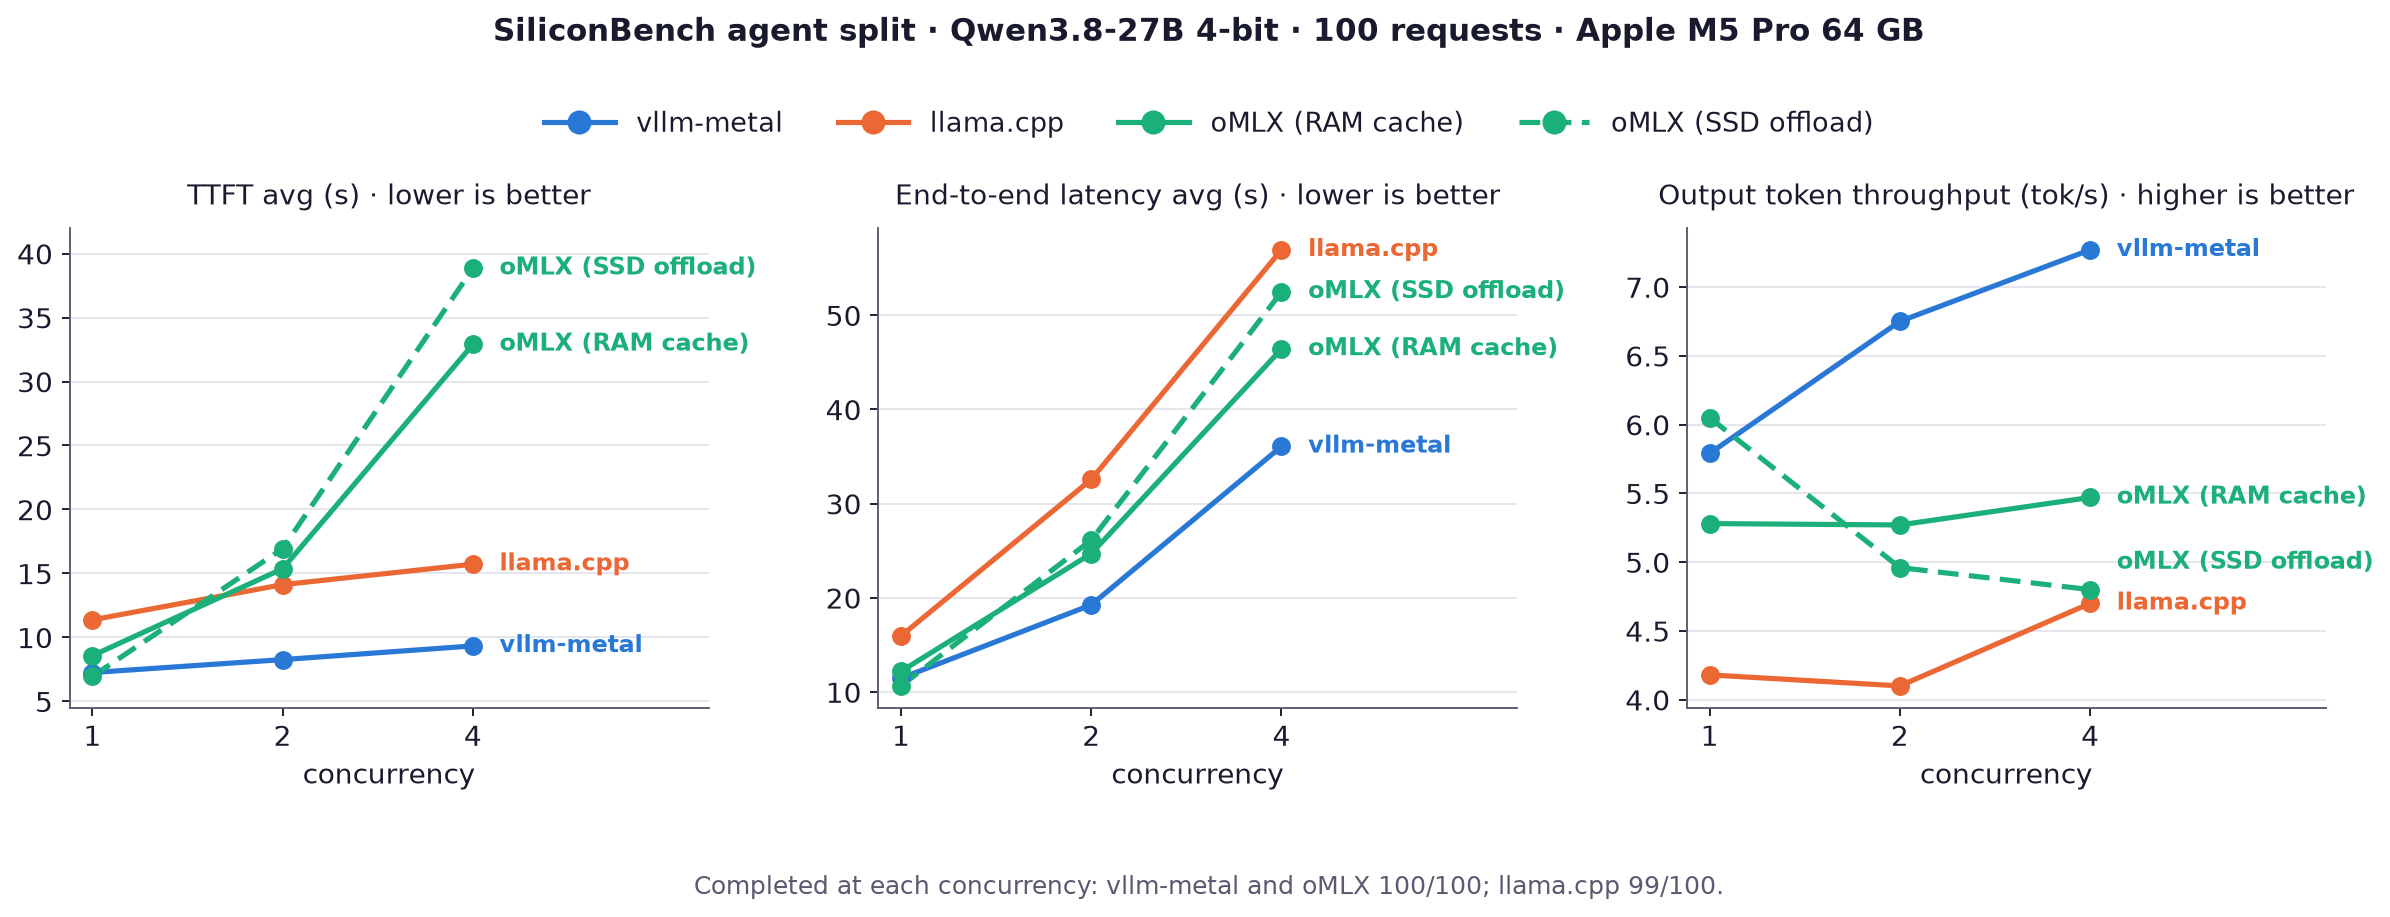
vLLM BlogToolsAnnouncing vllm-metal: Concurrent Serving on Apple Silicon vllm-metal brings vLLM's paged, continuously batched serving stack to Apple Silicon, with flatter TTFT under concurrent agent load, batched MTP, and automatic M5 prefill acceleration.
Nothing matches this filter yet.