vLLM BlogTools
Achieving near-zero-downtime scaling in Elastic Expert Parallelism
How asynchronous preparation and NIXL EP enabled near-zero-downtime Elastic EP scaling in vLLM.
Read at vLLM Blog ↗Related
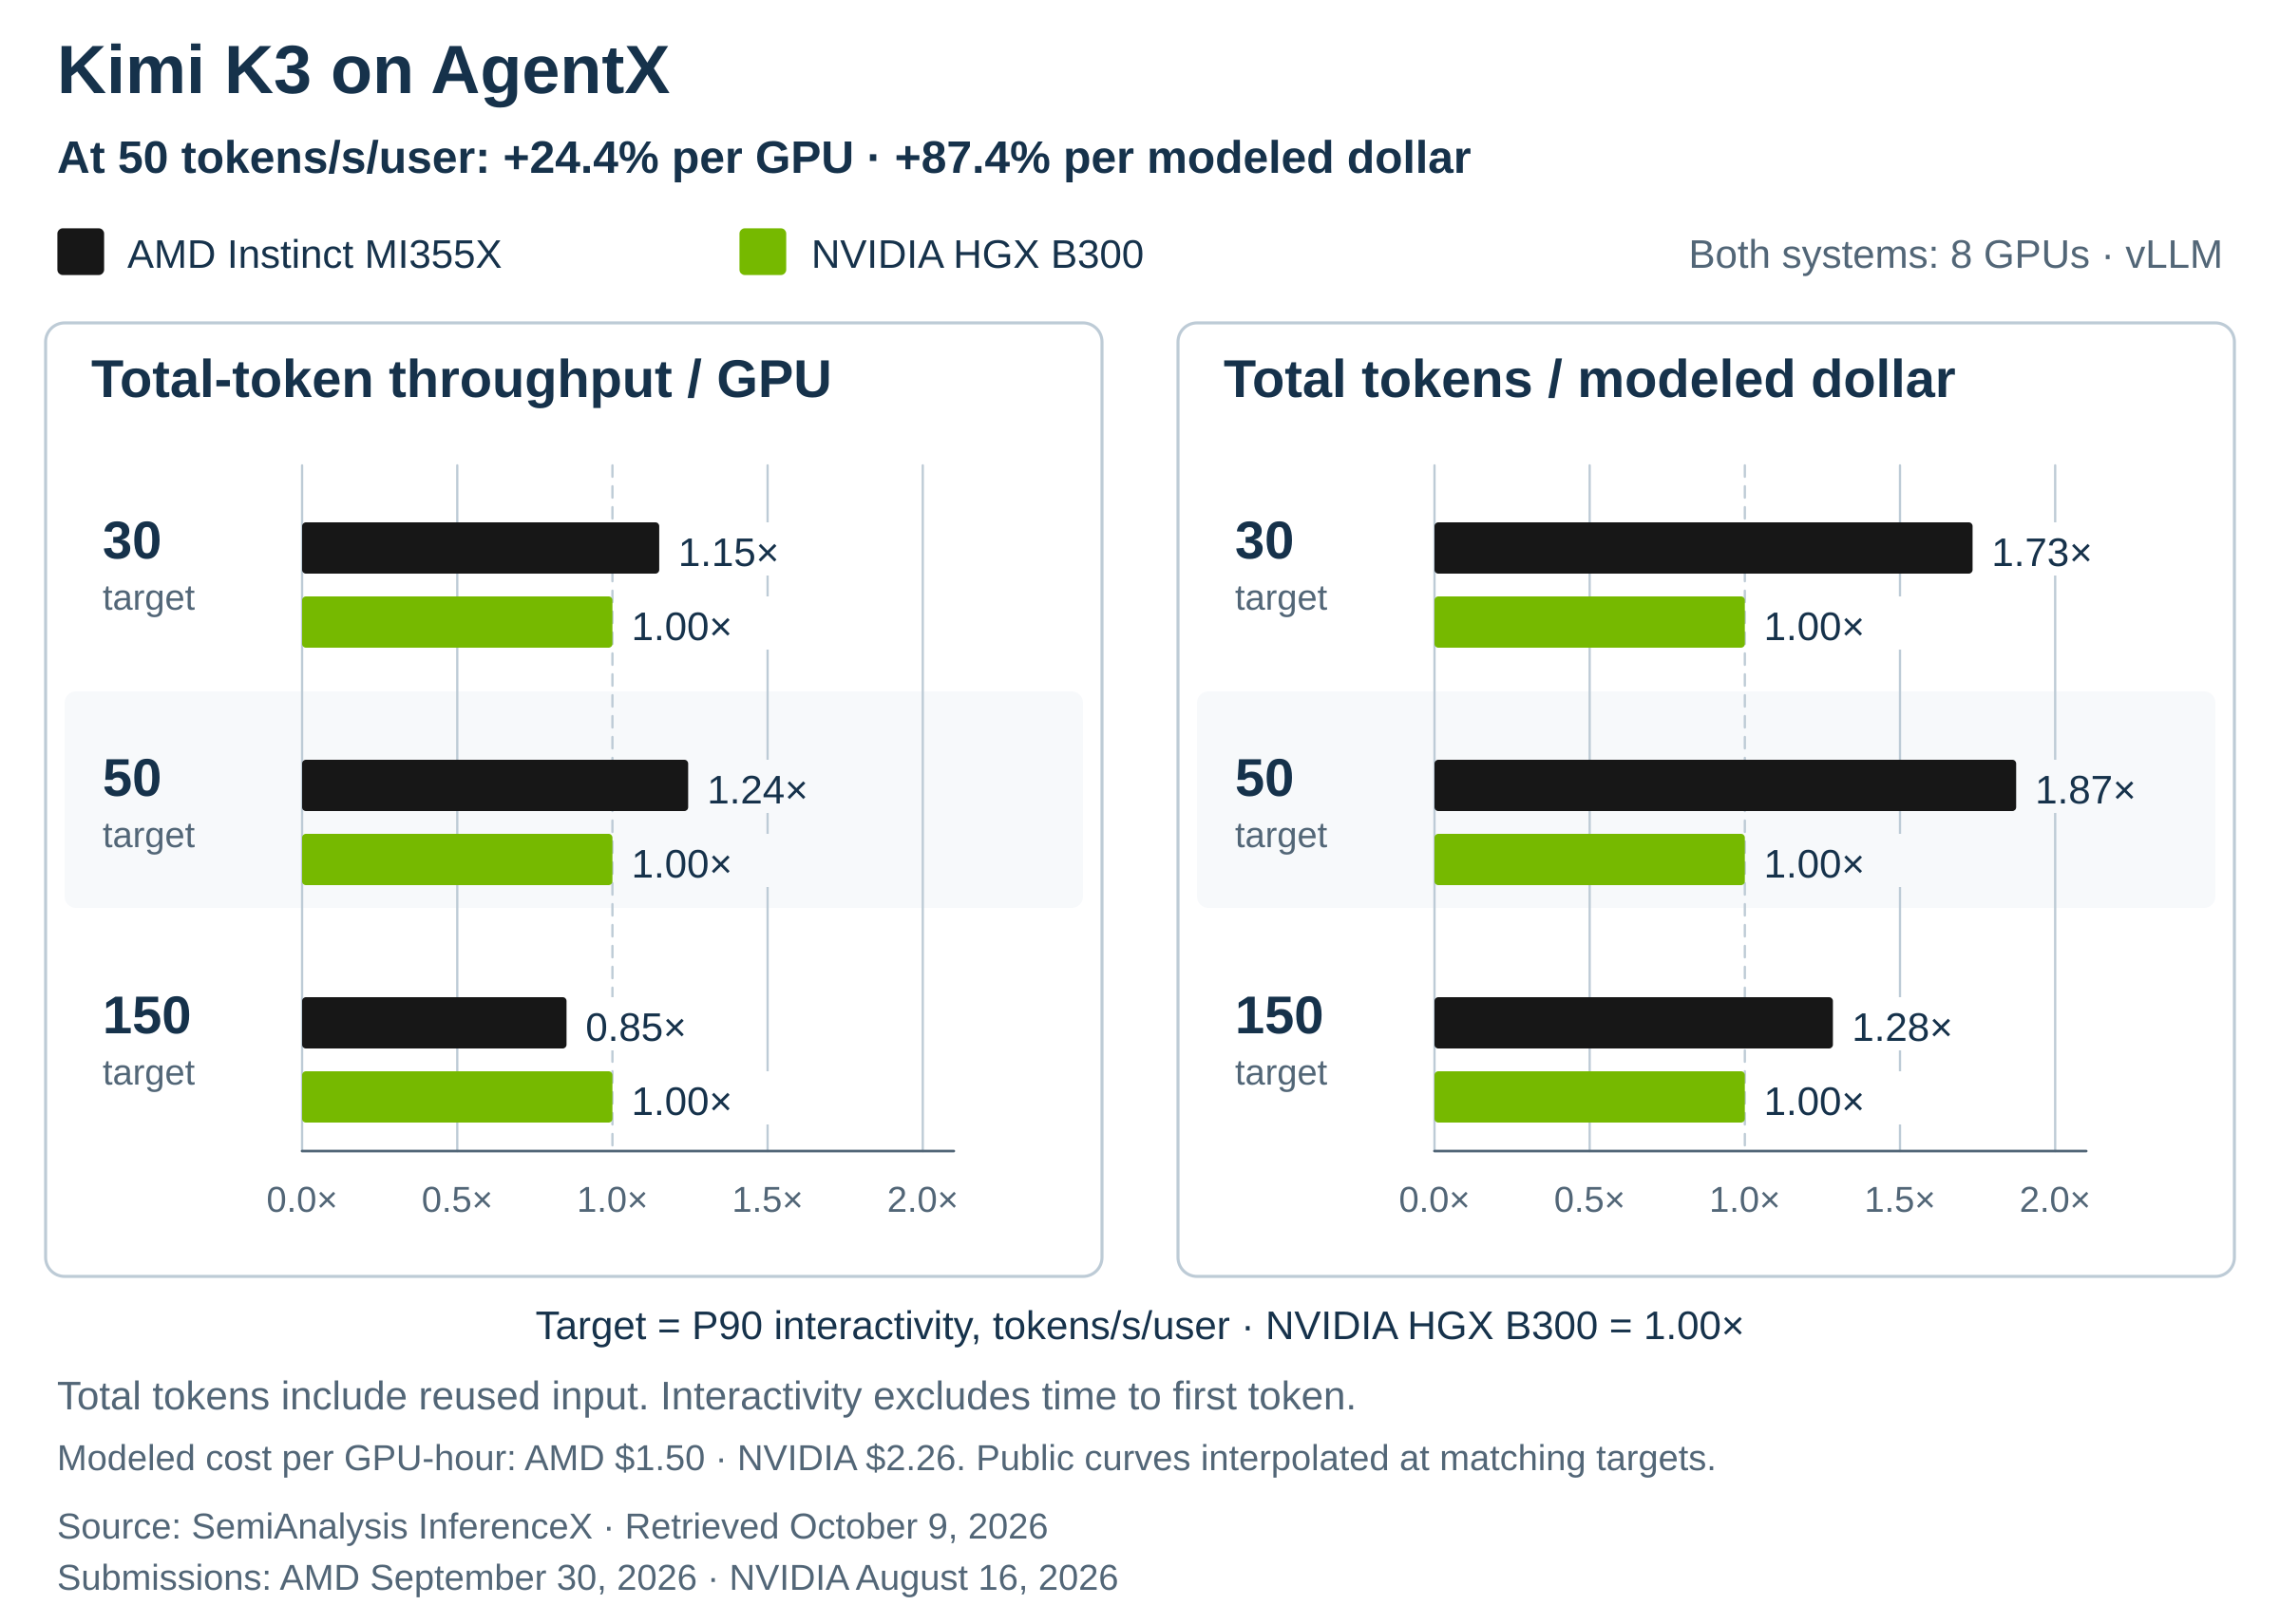
ToolsScaling Kimi K3 on AMD Instinct MI355X: Matching NVIDIA HGX B300 Throughput per GPU on AgentX vLLM Blog
ToolsHow Legora runs 2,000 parallel agent evals on Modal Sandboxes Modal
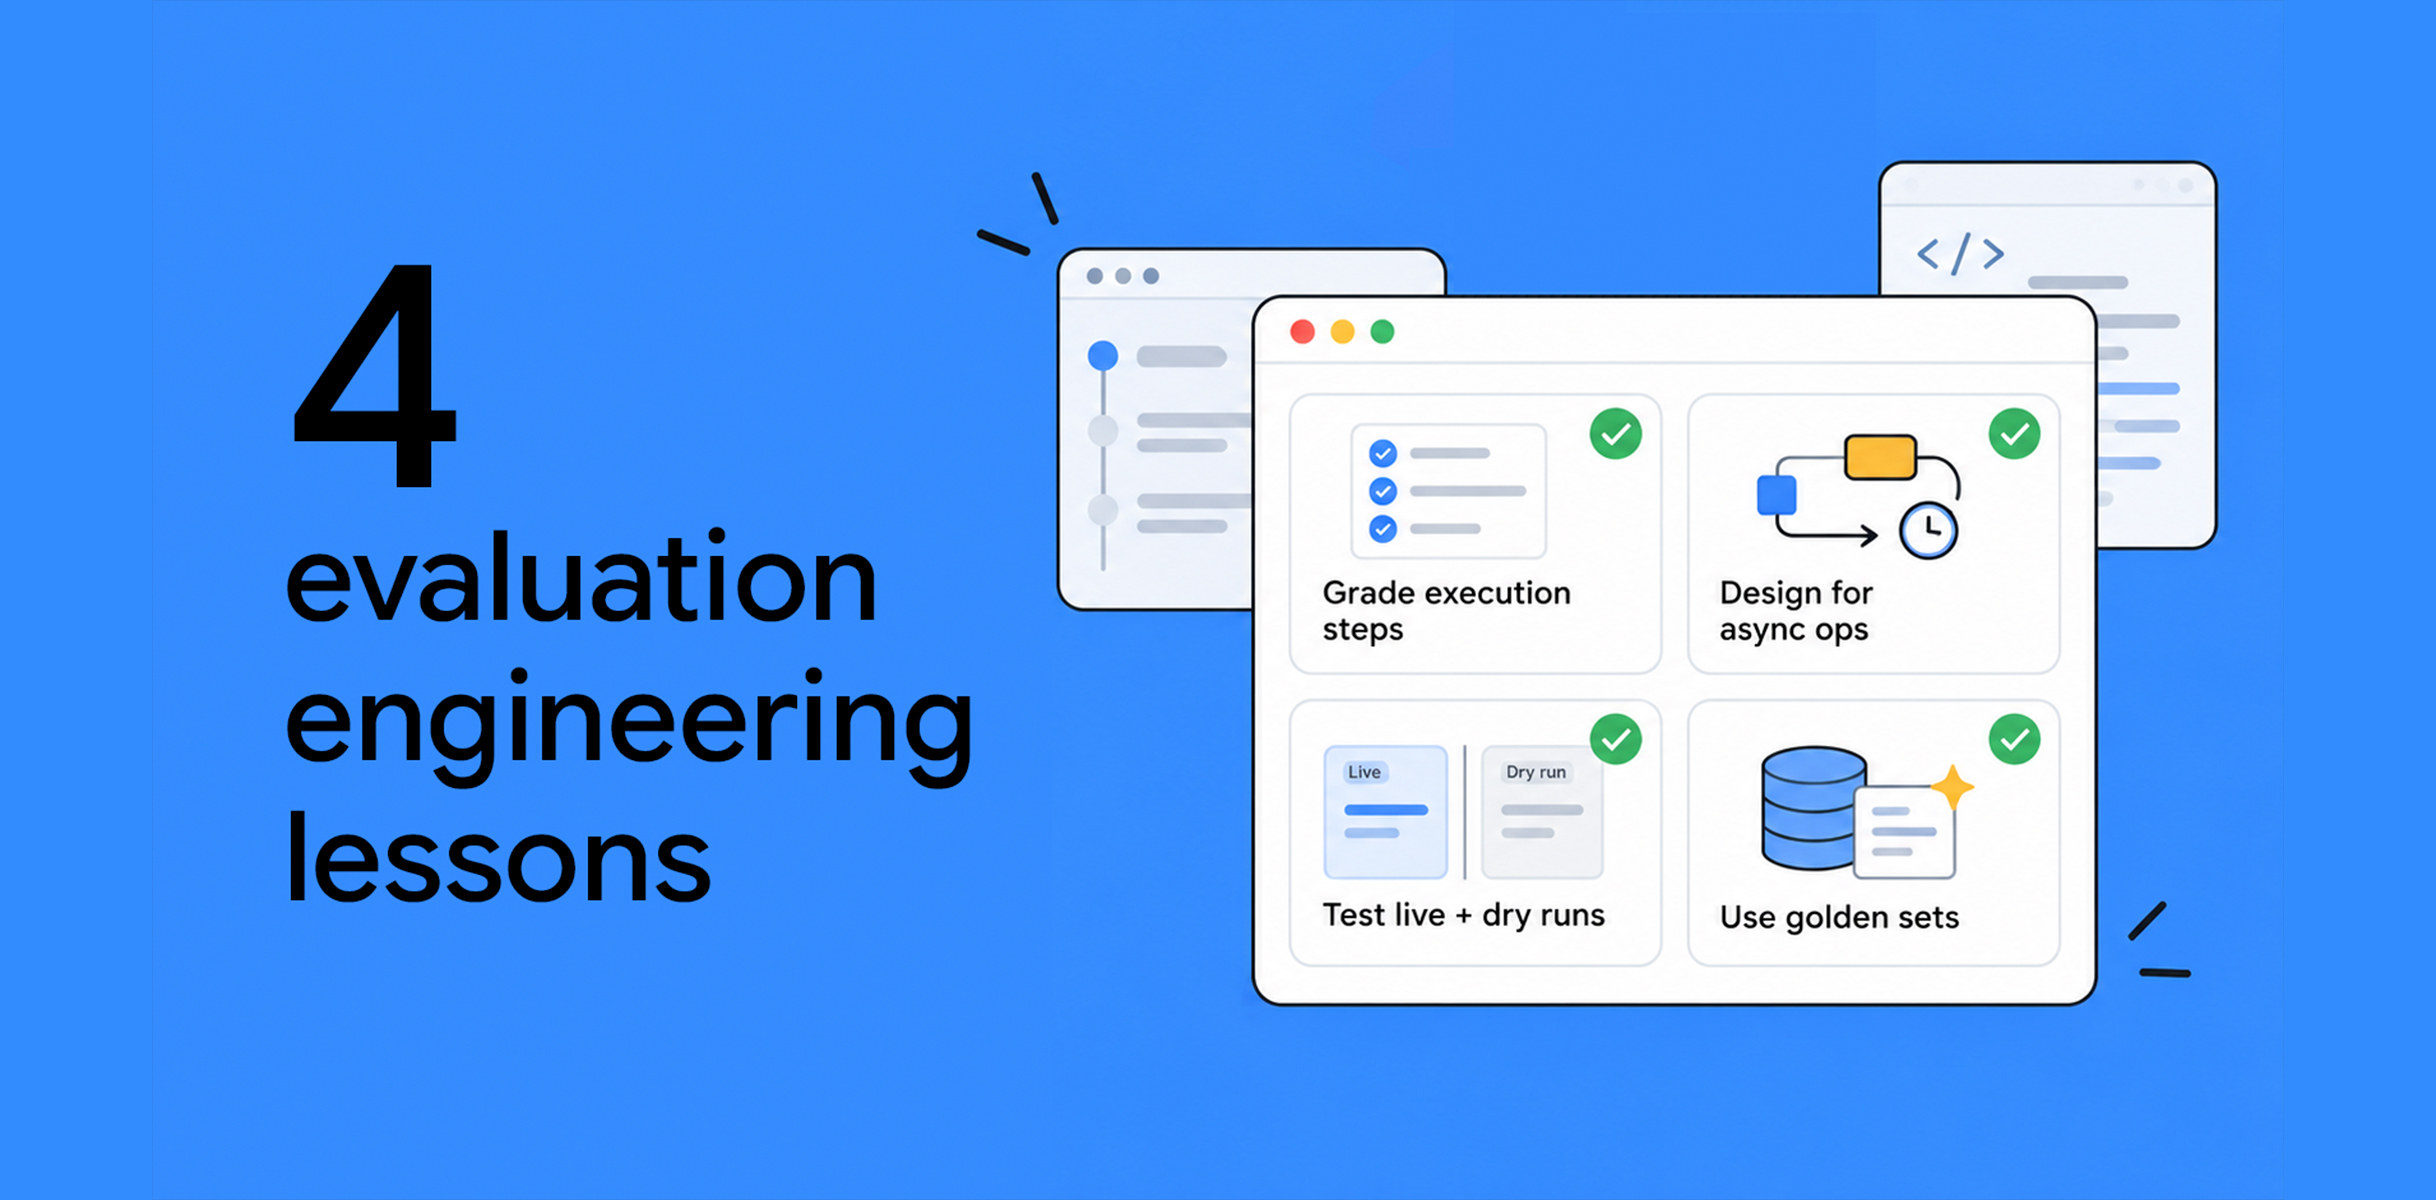
LabsFour evaluation engineering lessons learned from building agent plugins Google Cloud AI

JapanElasticsearch の Autoscaling を改善する: scale-out の高速化と HPA tolerance の調整 Mercari Engineering
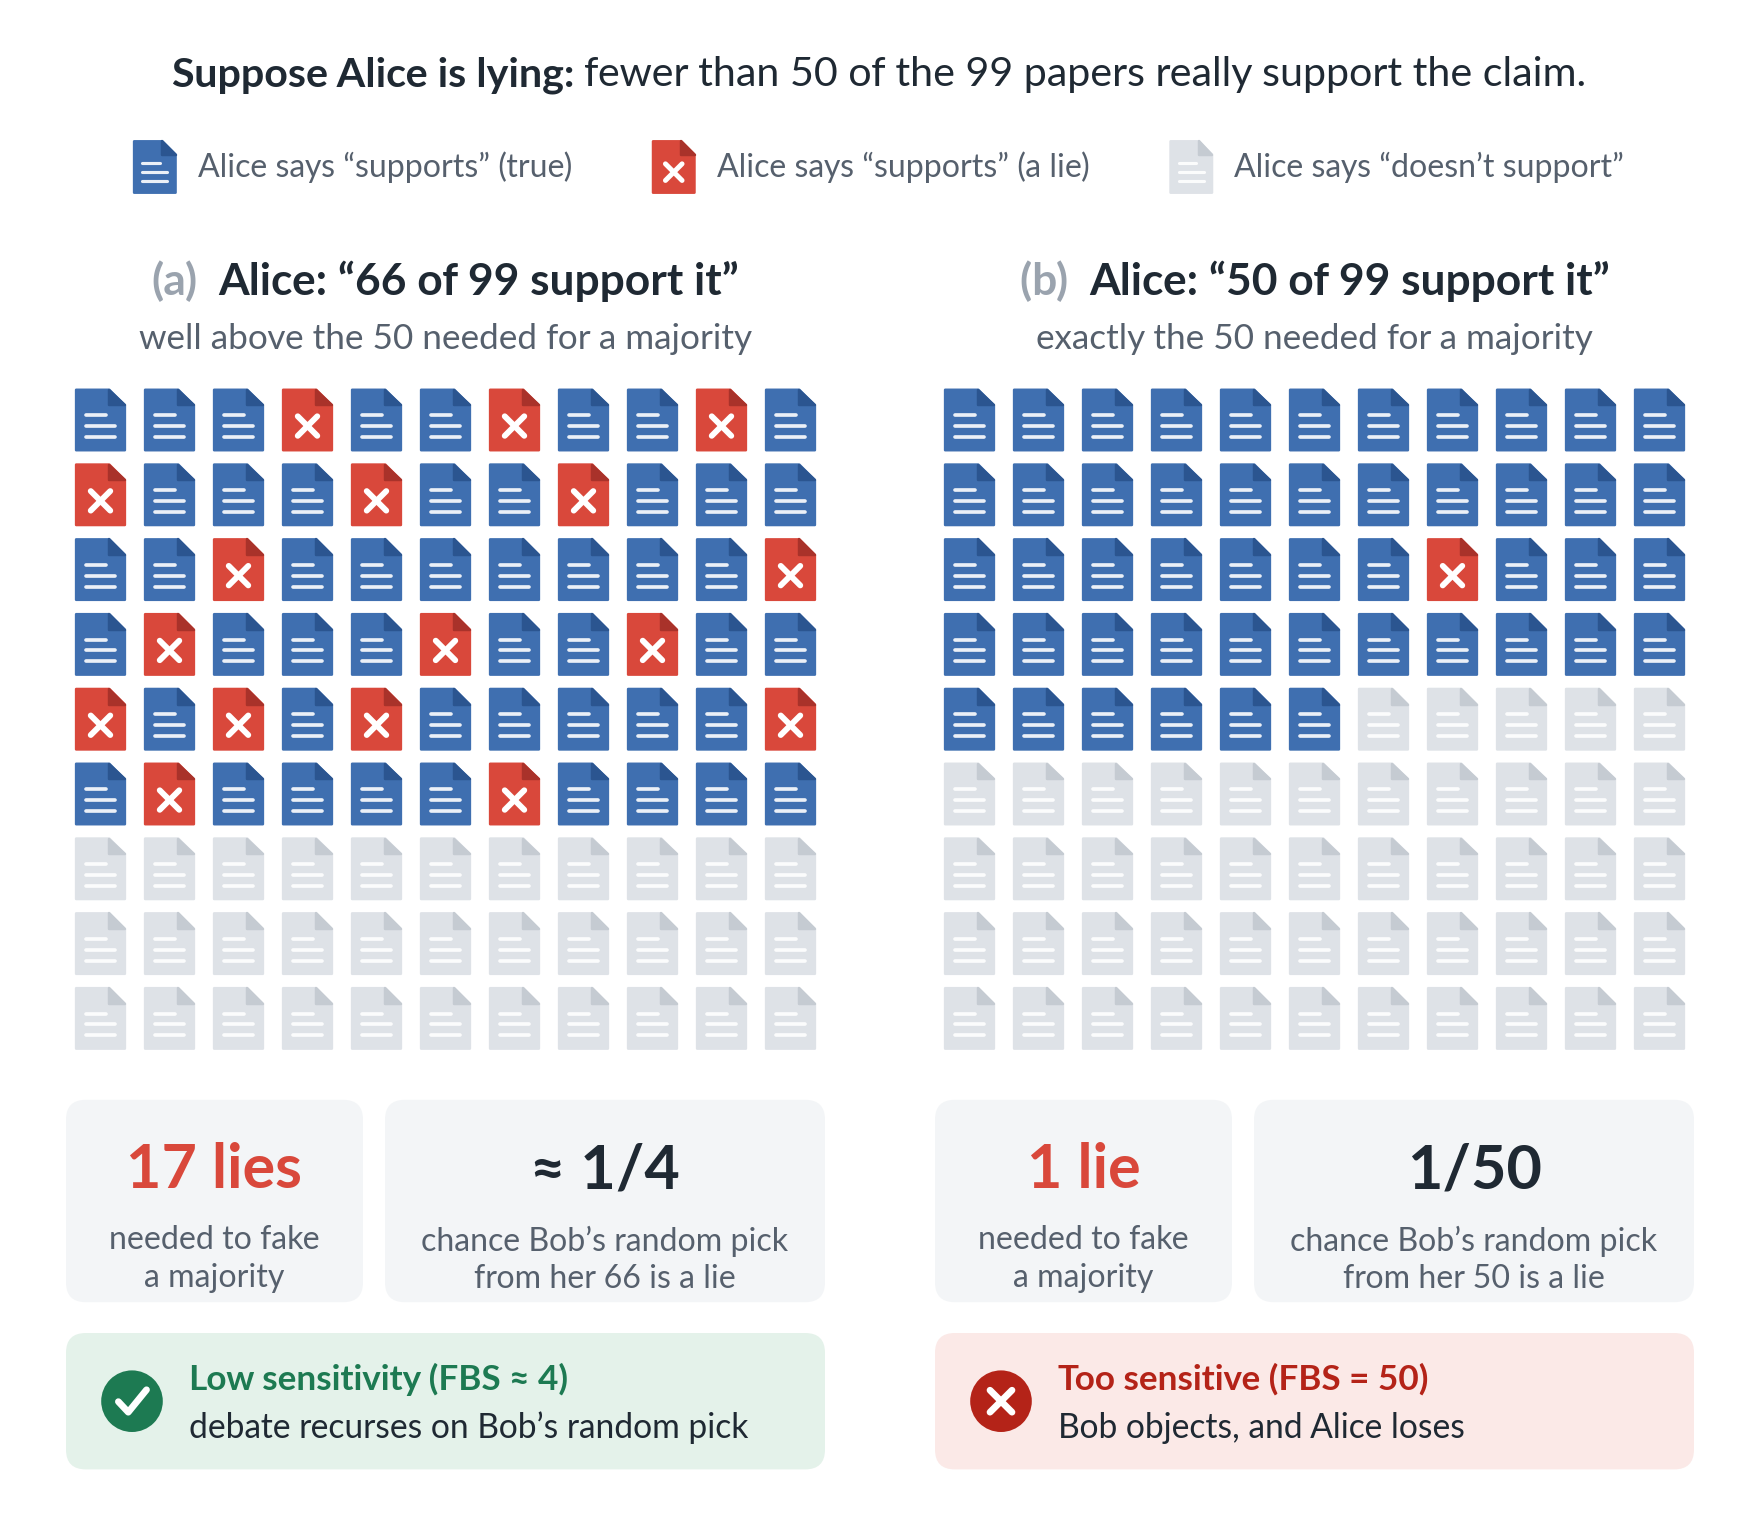
ResearchA Simpler and Better Debate Protocol for Scalable Oversight AI Alignment Forum
