vLLM BlogTools
Reducing vLLM startup time with one uv flag
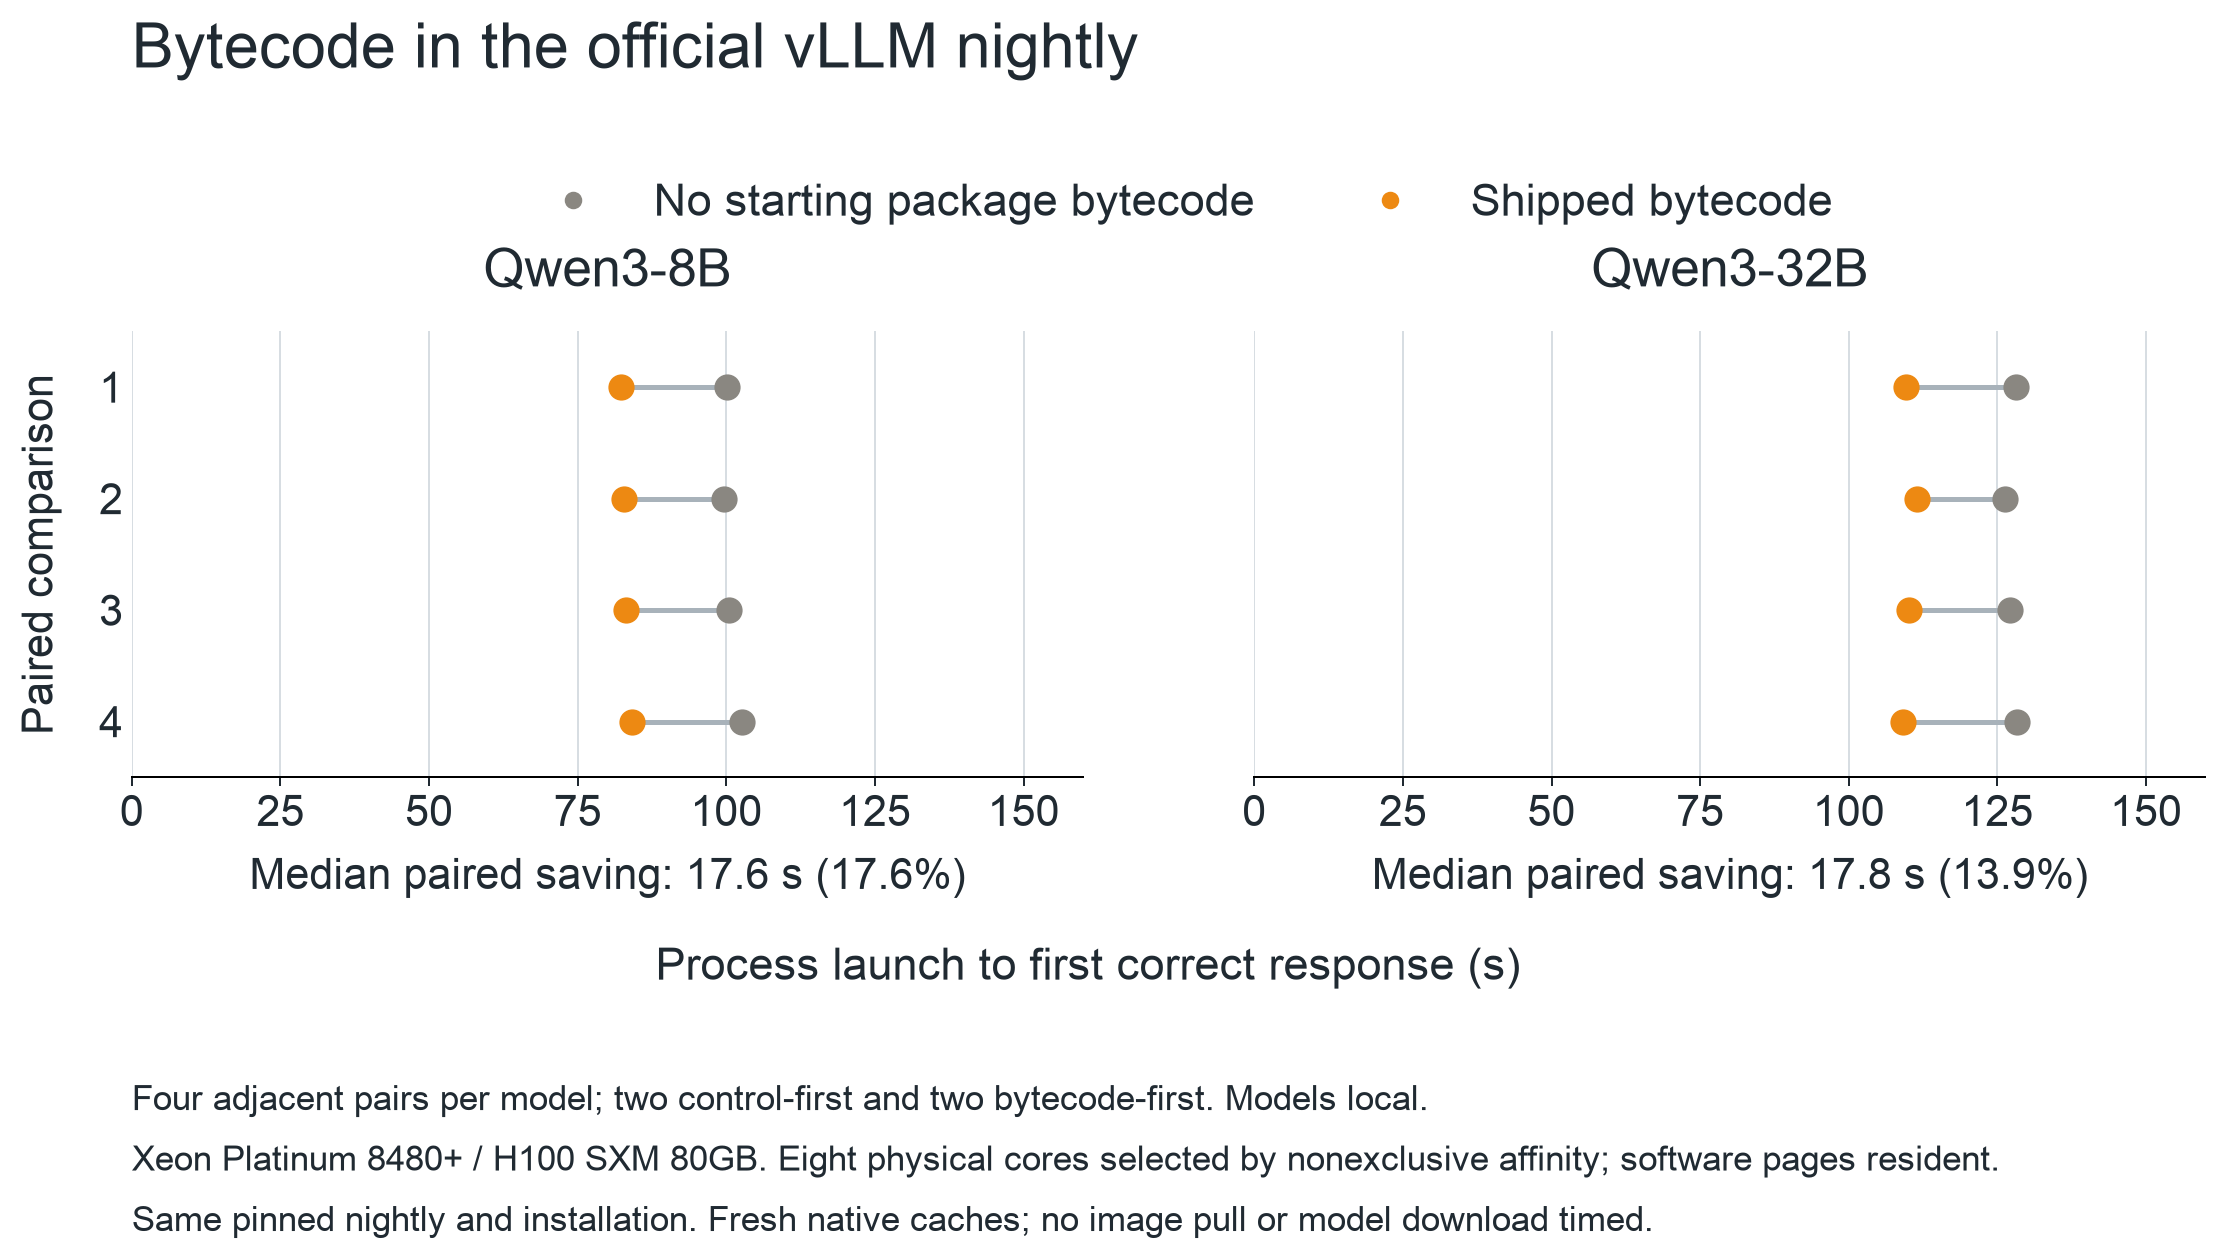
Shipping Python bytecode saved about 18 seconds per startup in H100 server benchmarks, with images and models already local.
Read at vLLM Blog ↗Related
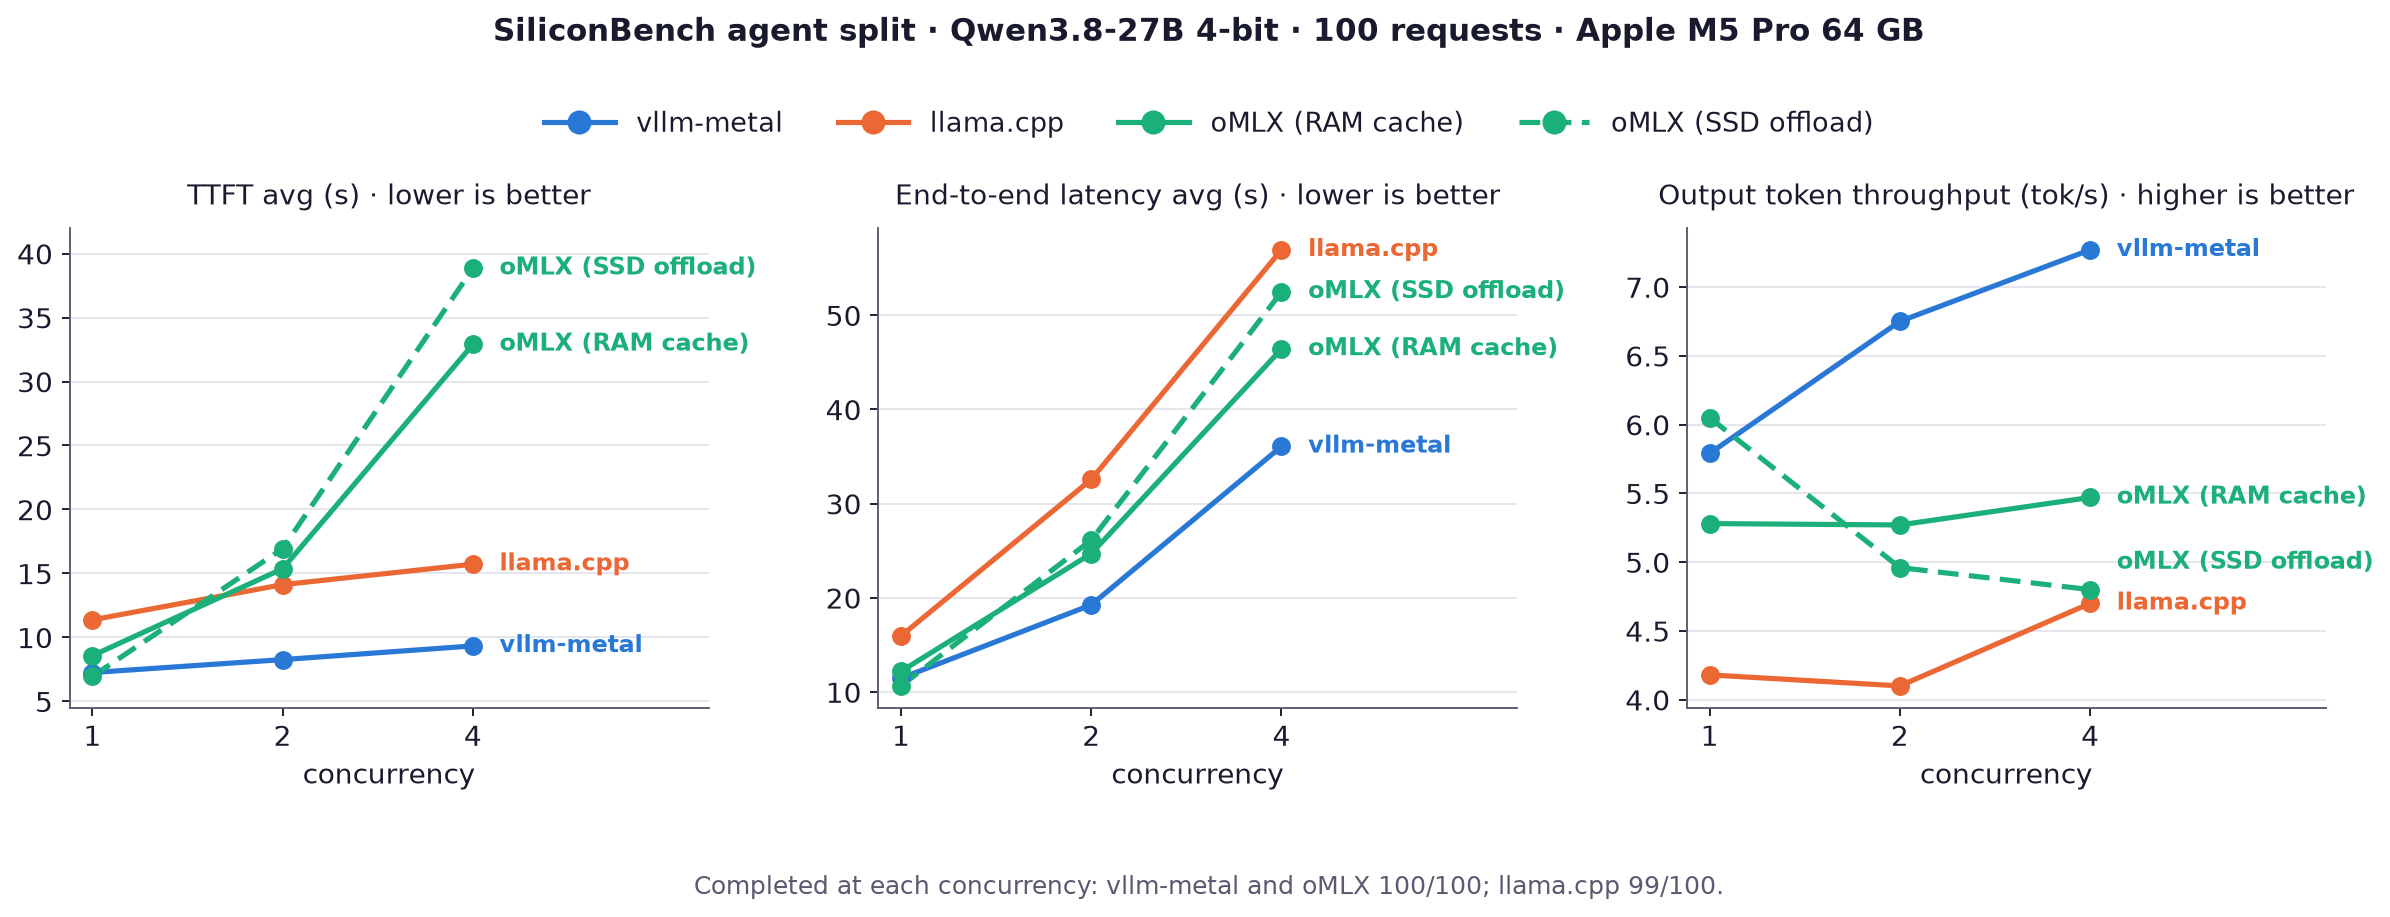
ToolsAnnouncing vllm-metal: Concurrent Serving on Apple Silicon vLLM Blog

GitHubReconnecting with the heart of open source: Highlights from our 2026 GSoC India tour Google Open Source Blog
ToolsMigrating from closed to open source models, Together Together AI
SiliconA Brain Too Big to Carry — On-Device vs Datacenter Inference SemiAnalysis
ToolsCline Desktop: An open-source app for open-weight models Cline Blog
