vLLM BlogTools
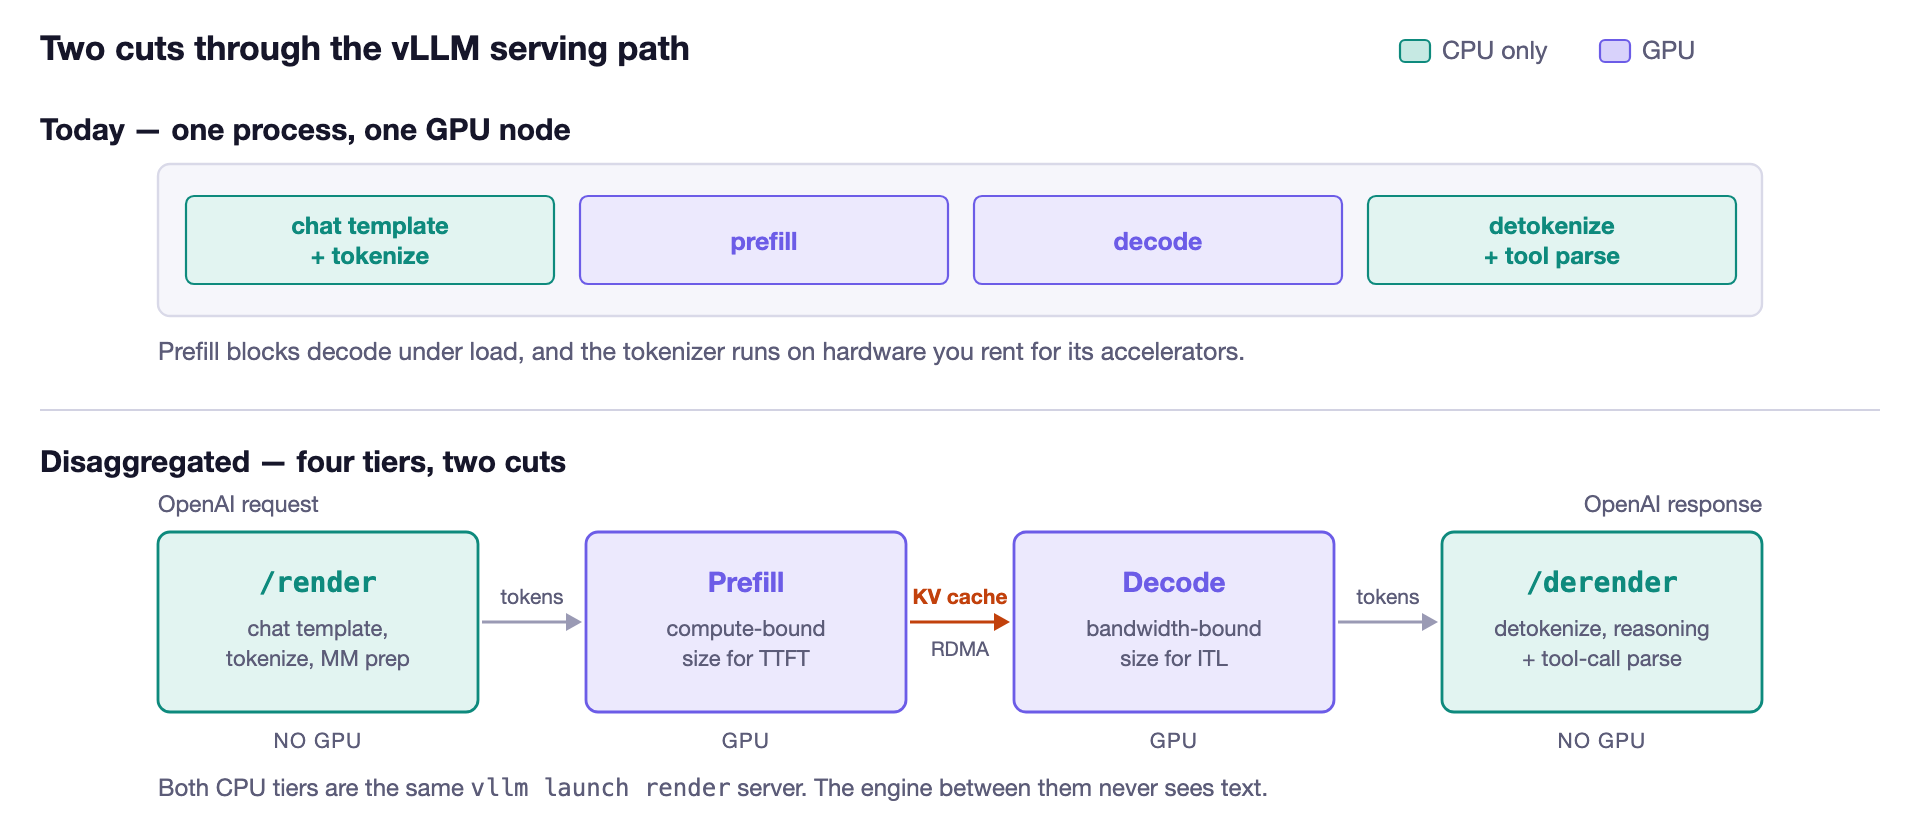
vLLM Support for NVIDIA Vera Rubin NVL72: 7.8x Throughput over GB200 NVL72
vLLM now runs on NVIDIA Vera Rubin NVL72 with day-0 model support, Rubin-tuned FlashInfer kernels, and locality-aware MoE, delivering 7.8x the per-GPU throughput of GB200 NVL72 on AgentX.
Read at vLLM Blog ↗Related
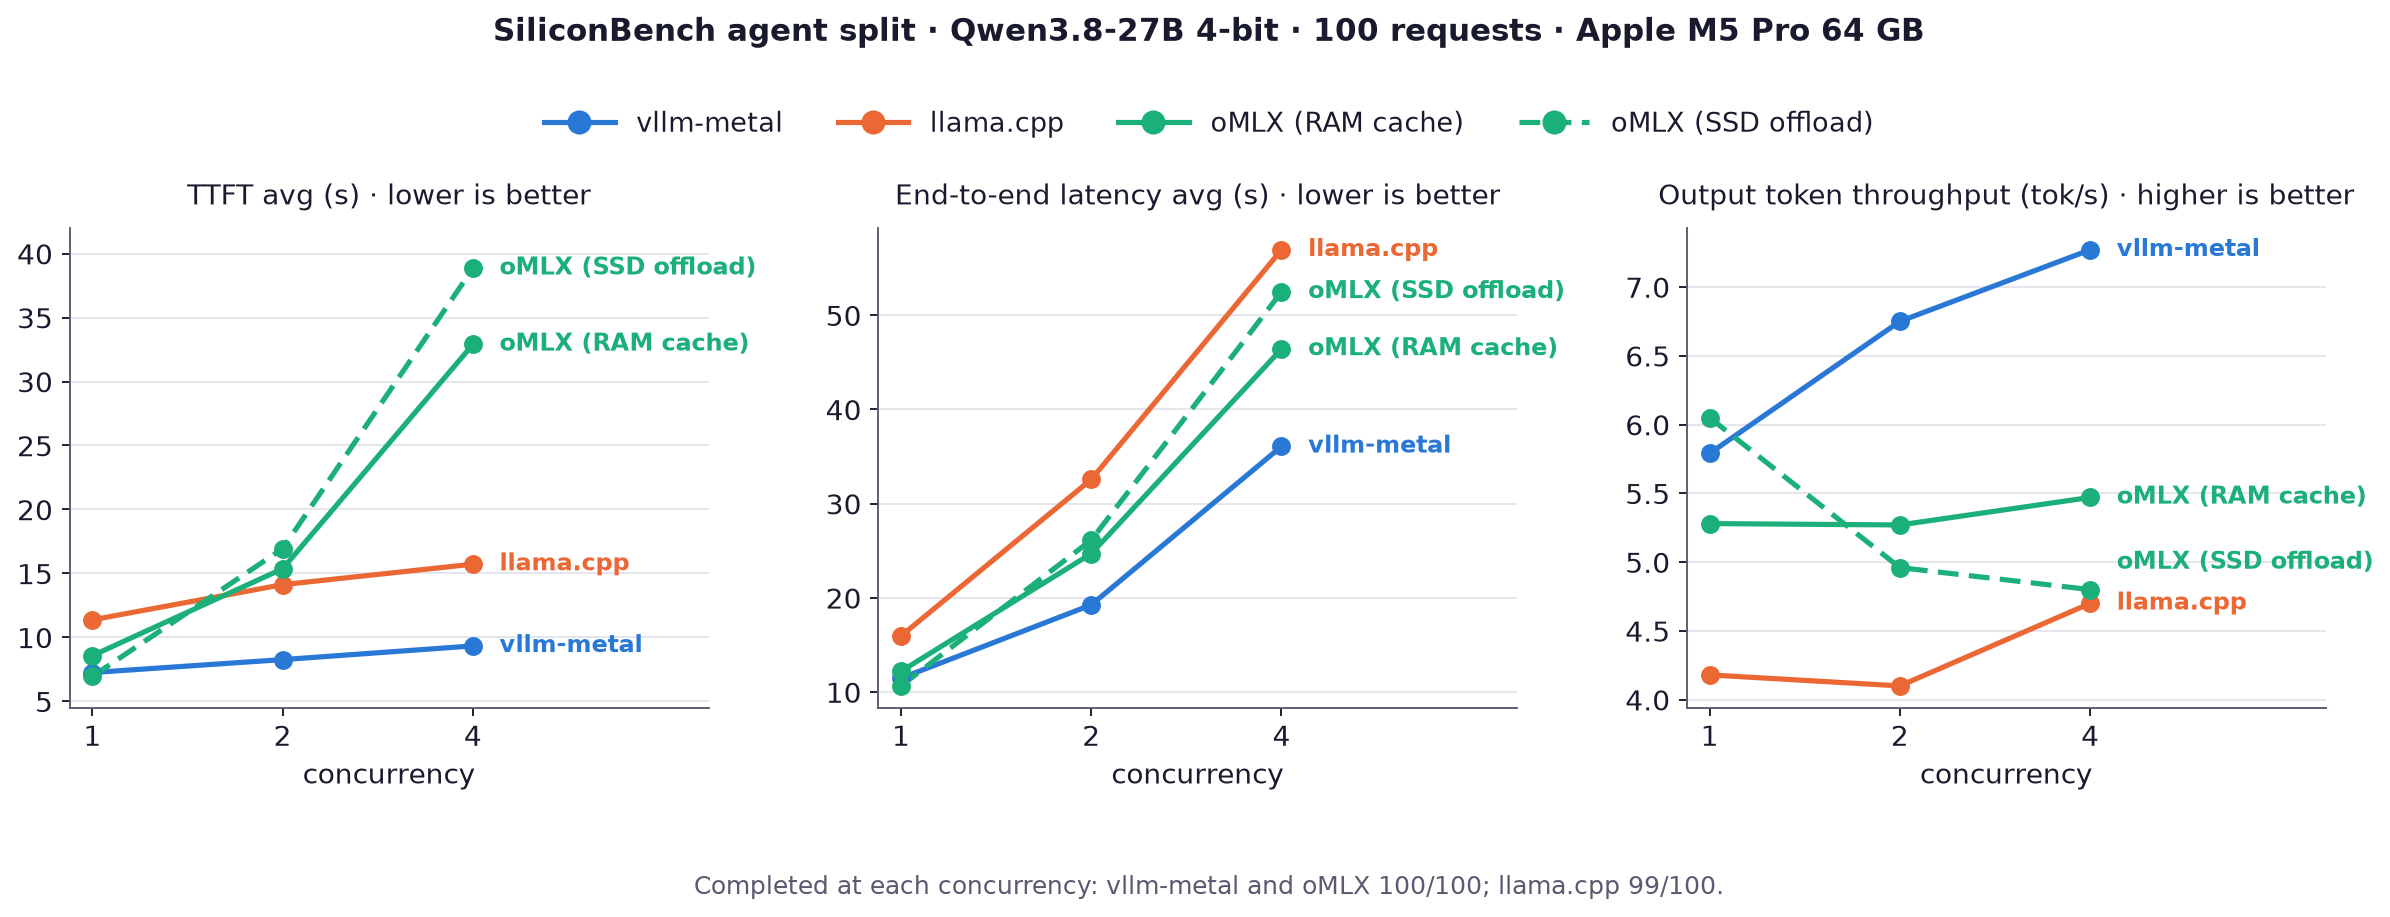
ToolsAnnouncing vllm-metal: Concurrent Serving on Apple Silicon vLLM Blog
SiliconA Brain Too Big to Carry — On-Device vs Datacenter Inference SemiAnalysis
VoicesSED News: The NVIDIA-Hugging Face Deal, China’s Proxy Economy, the Open Weight Surge Software Engineering Daily

ToolsNvidia reportedly agrees to purchase Hugging Face for $13B Weights & Biases
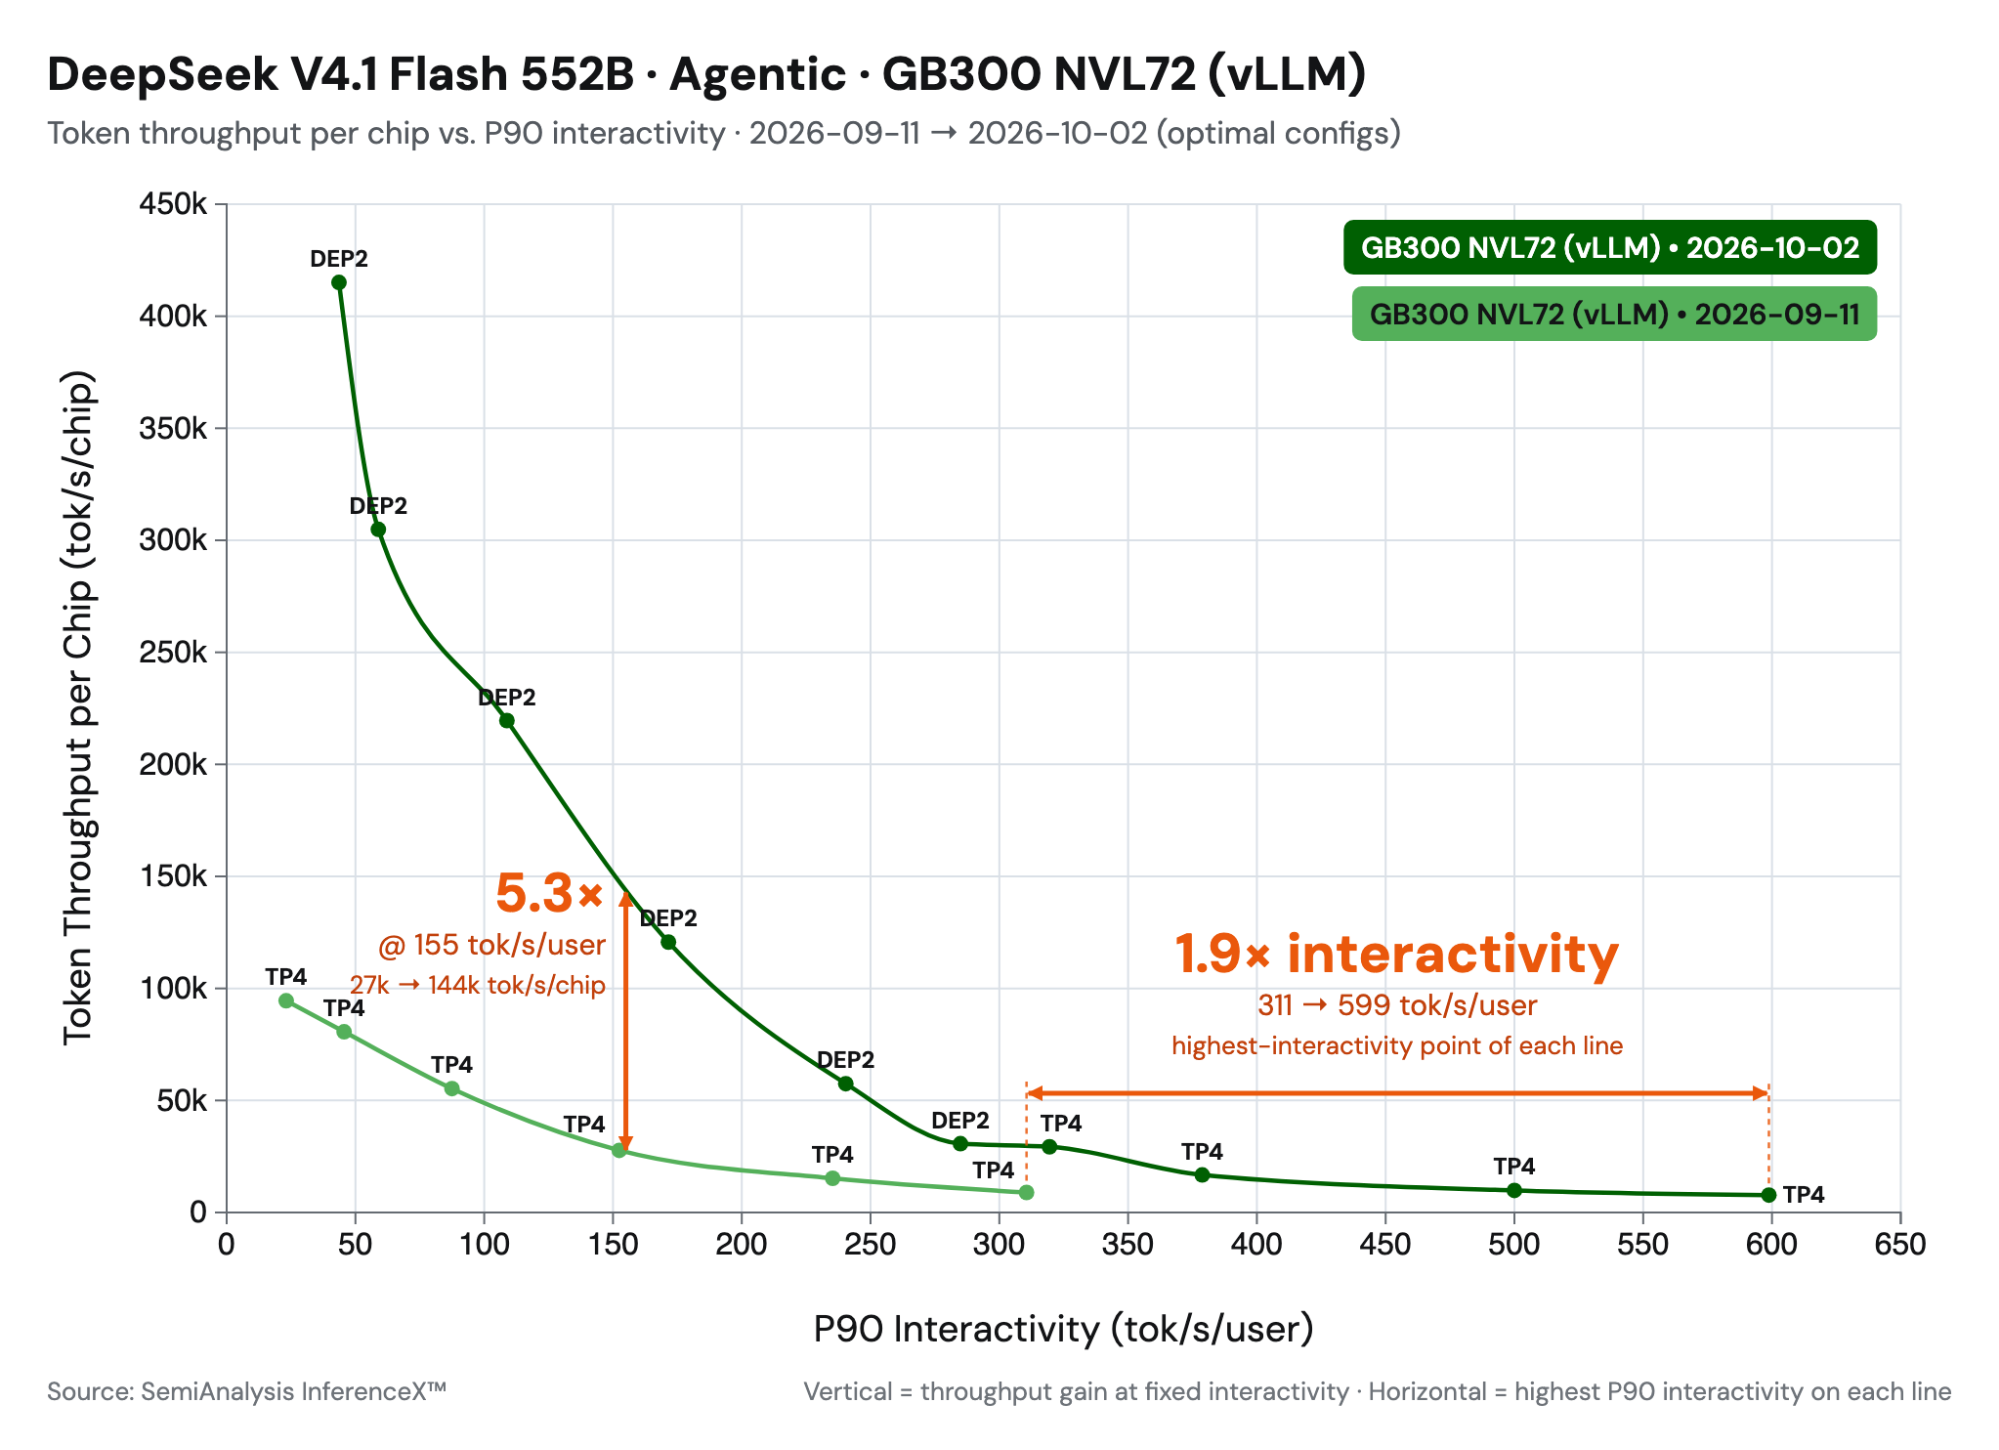
ToolsDeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 vLLM Blog