vLLM BlogTools
GLM-5.3 Optimizations, Part 2: PCP, DCP, and Hybrid HiSparse on 16 H200s
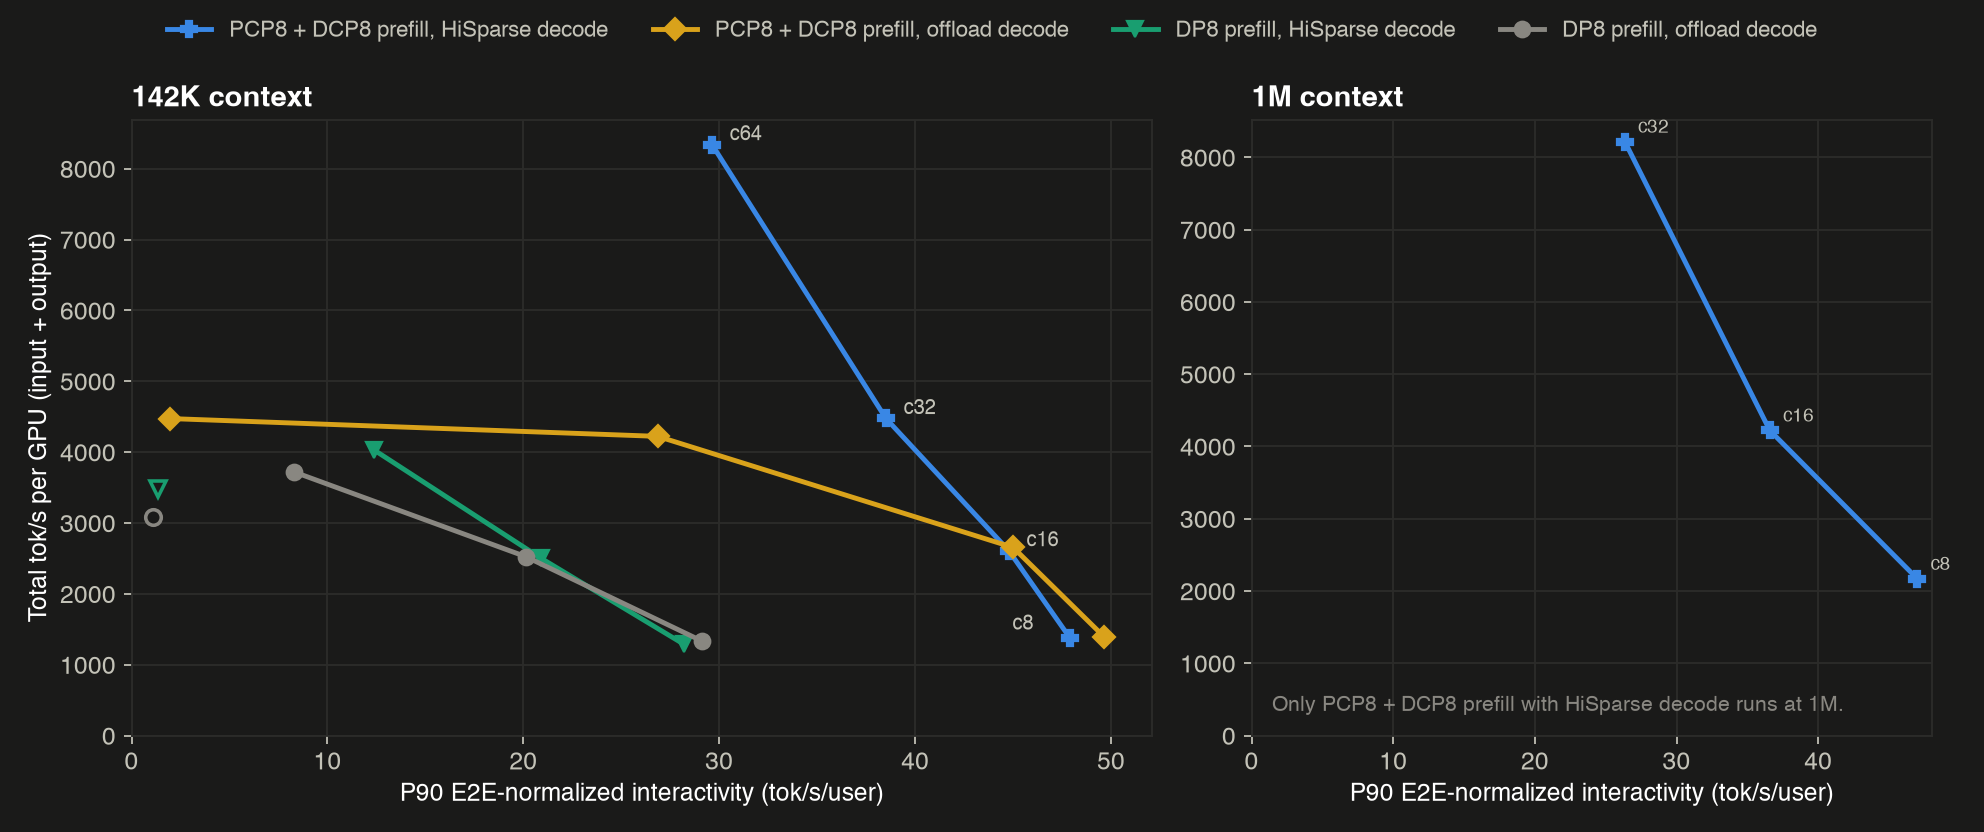
vLLM serves GLM-5.3 on 16 H200s with PCP and DCP prefill and Hybrid HiSparse decode, reaching 1M-token contexts and 1.7–3.2× the per-user speed of data-parallel P/D on the AgentX agentic benchmark.
Read at vLLM Blog ↗Related
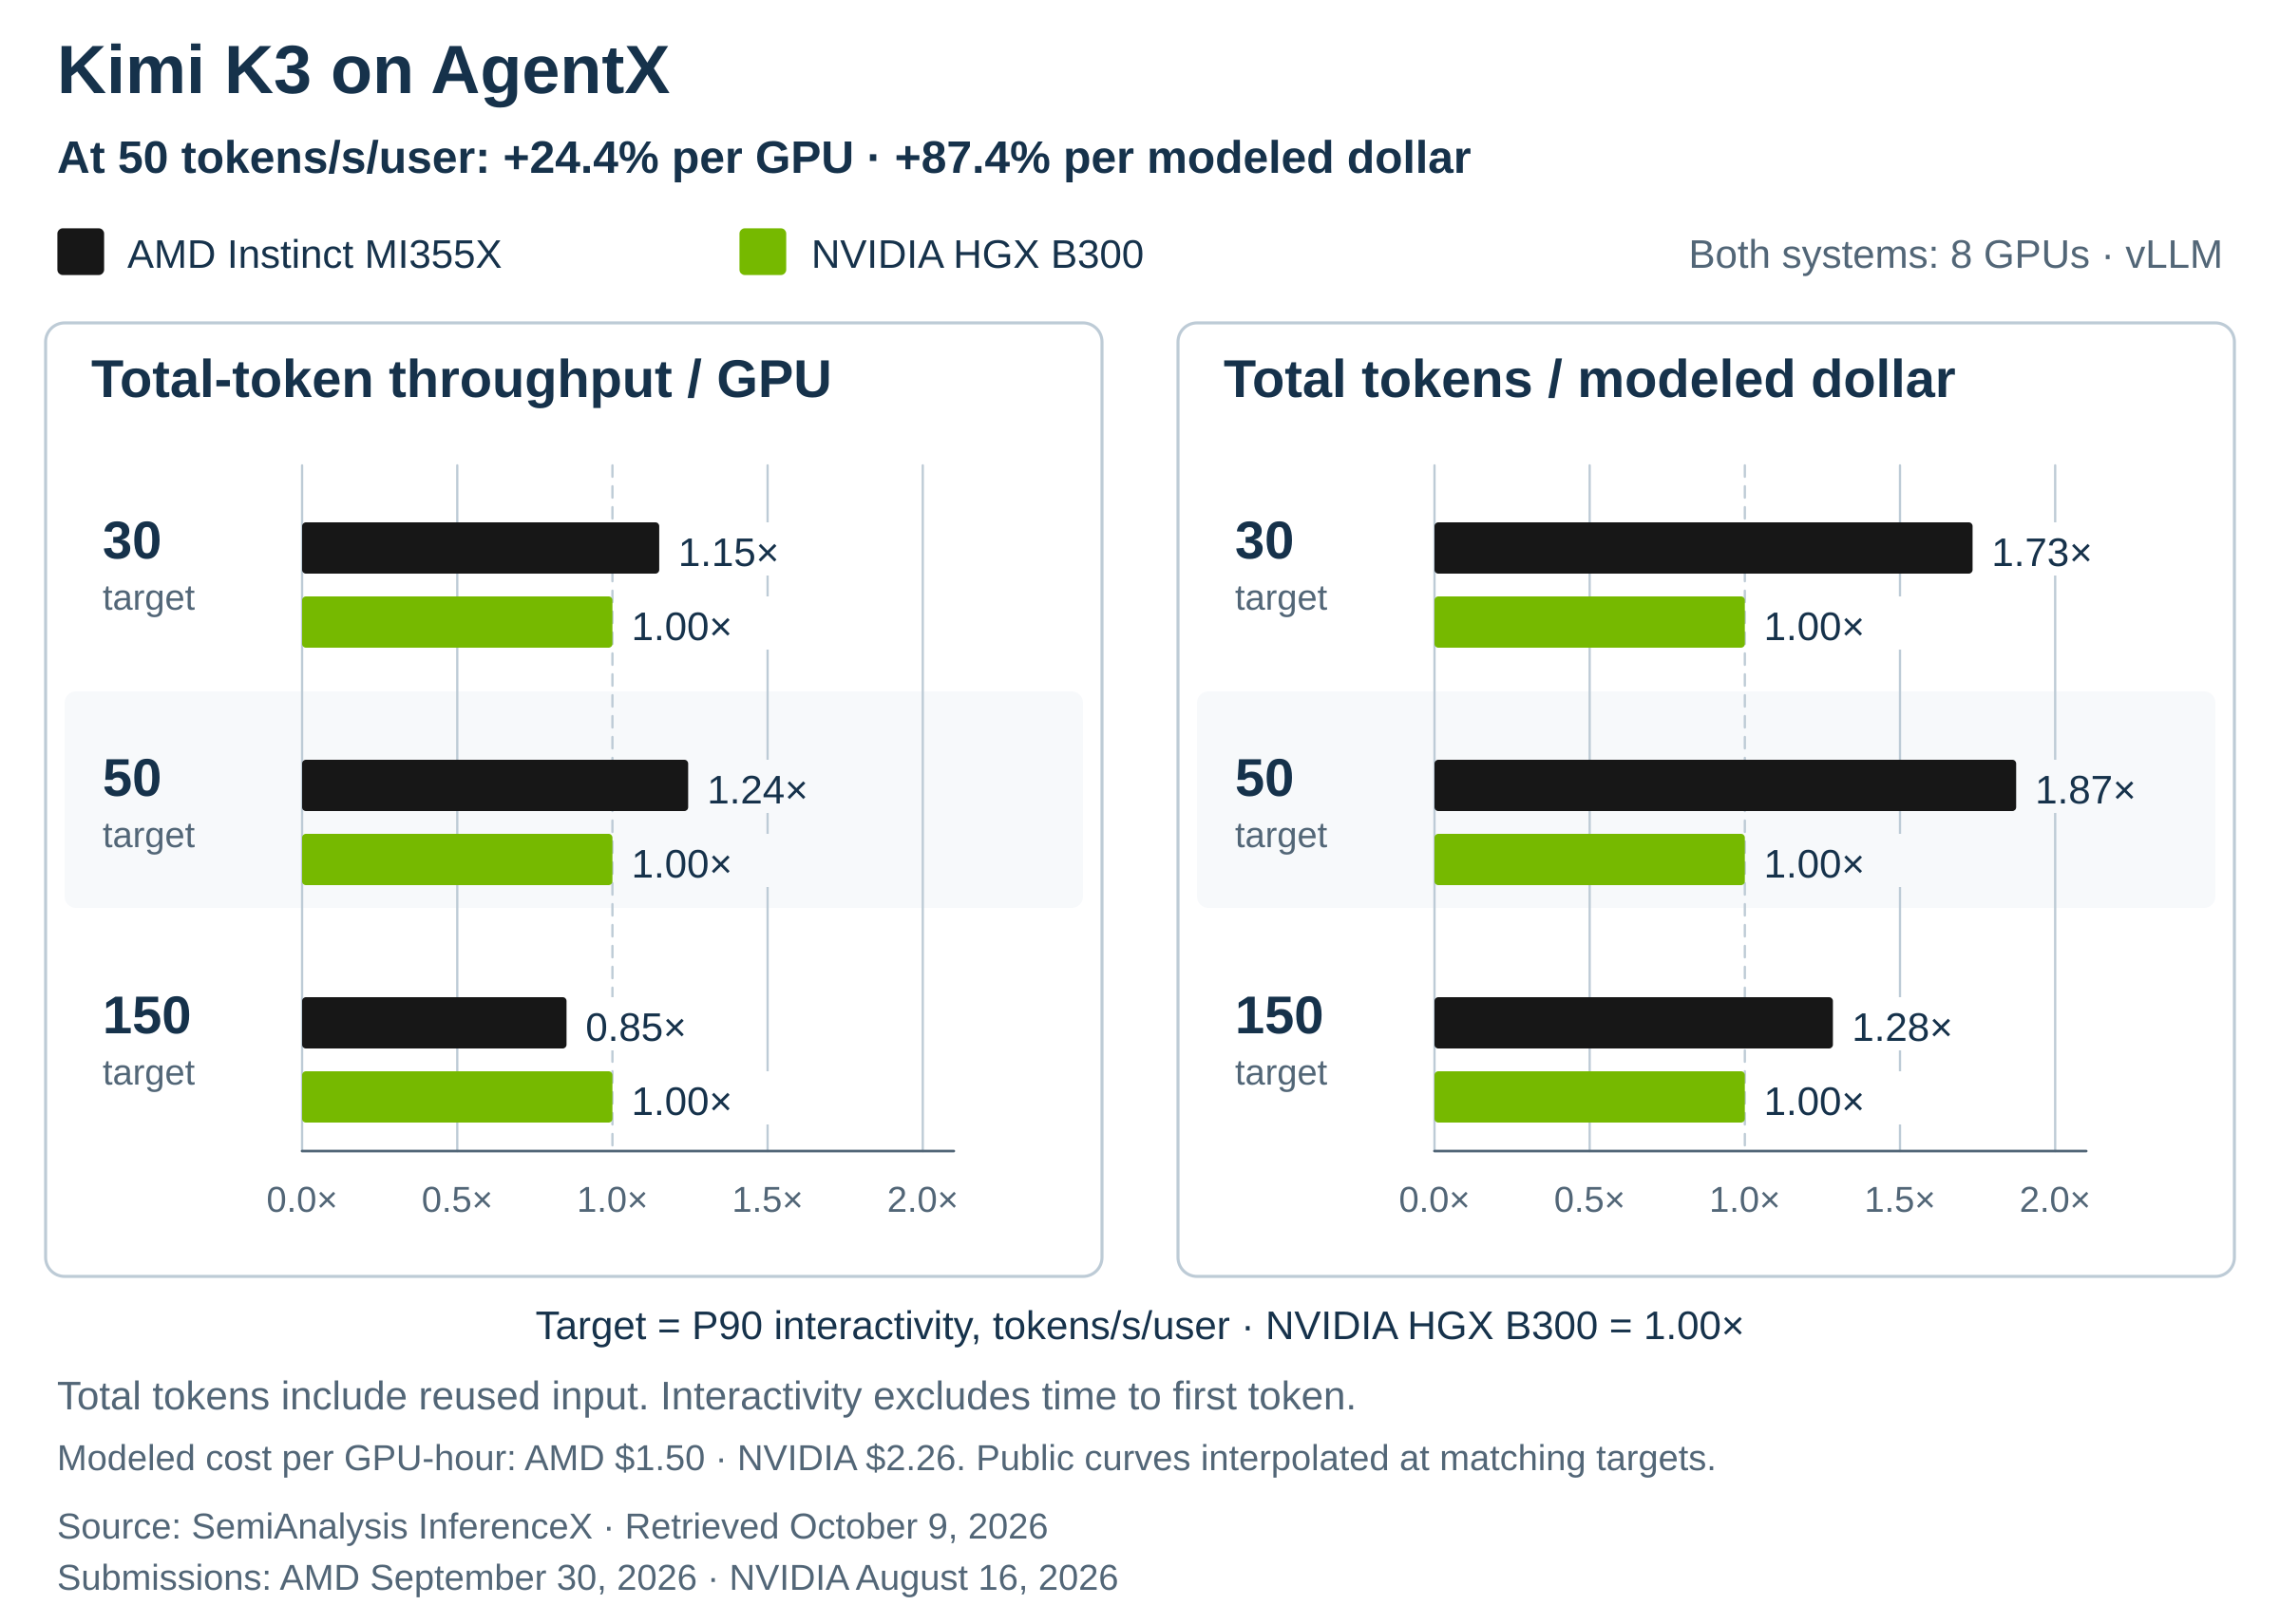
ToolsScaling Kimi K3 on AMD Instinct MI355X: Matching NVIDIA HGX B300 Throughput per GPU on AgentX vLLM Blog
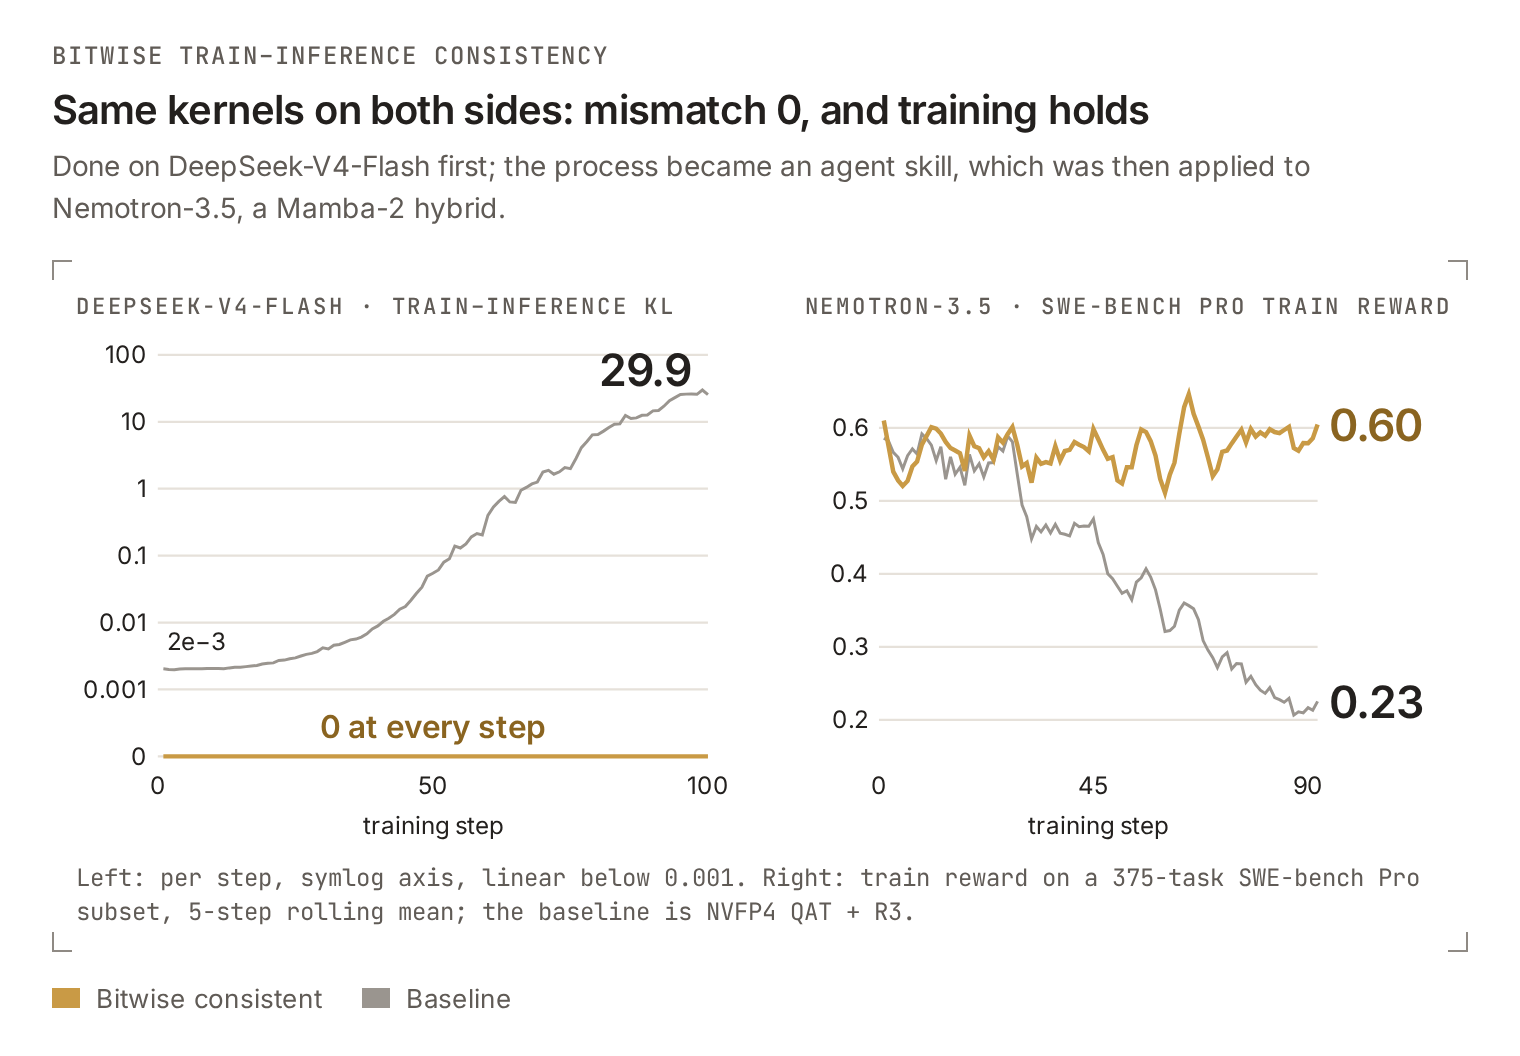
ToolsFinish RL Training Faster: Bitwise-Consistent, High-Performance, Agent-Driven vLLM Blog
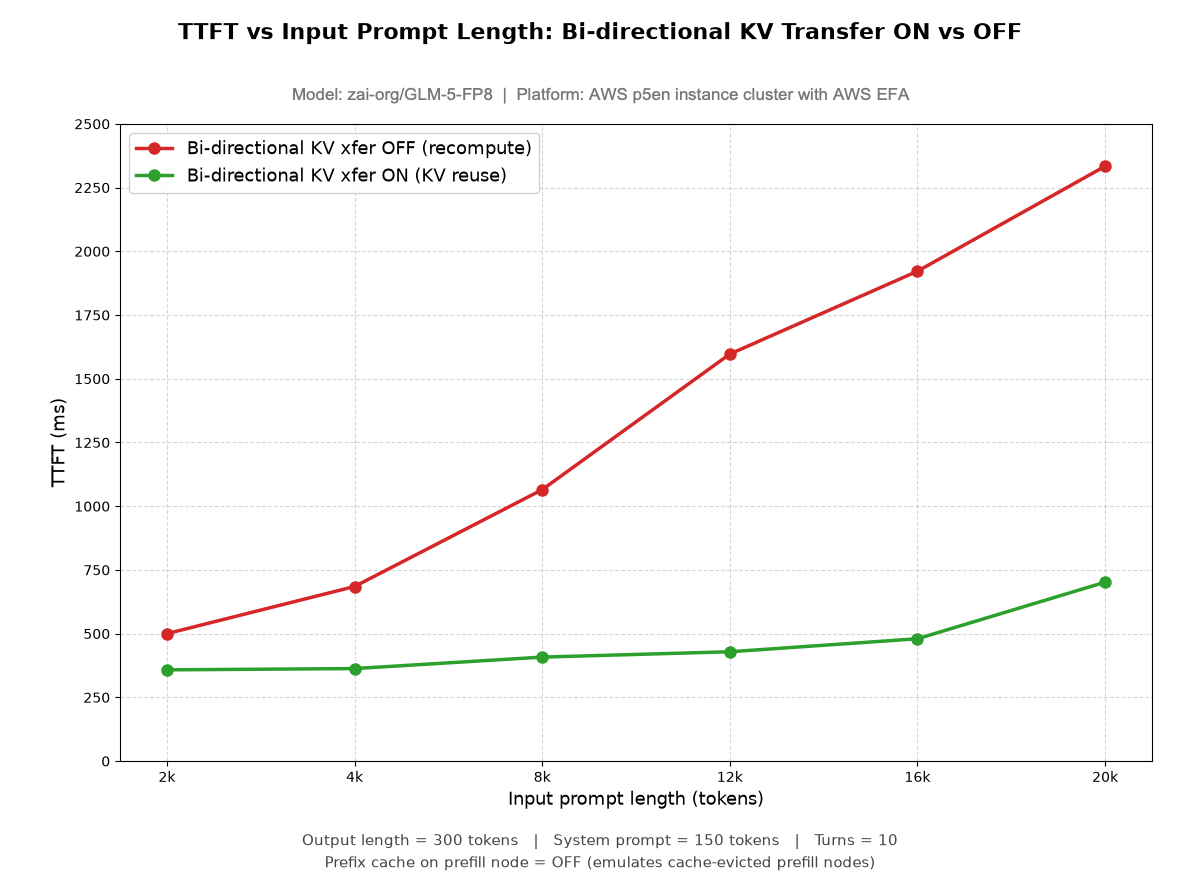
ToolsImprove TTFT for Multi-Turn Agentic Workloads with Bi-Directional KV Transfer in vLLM vLLM Blog
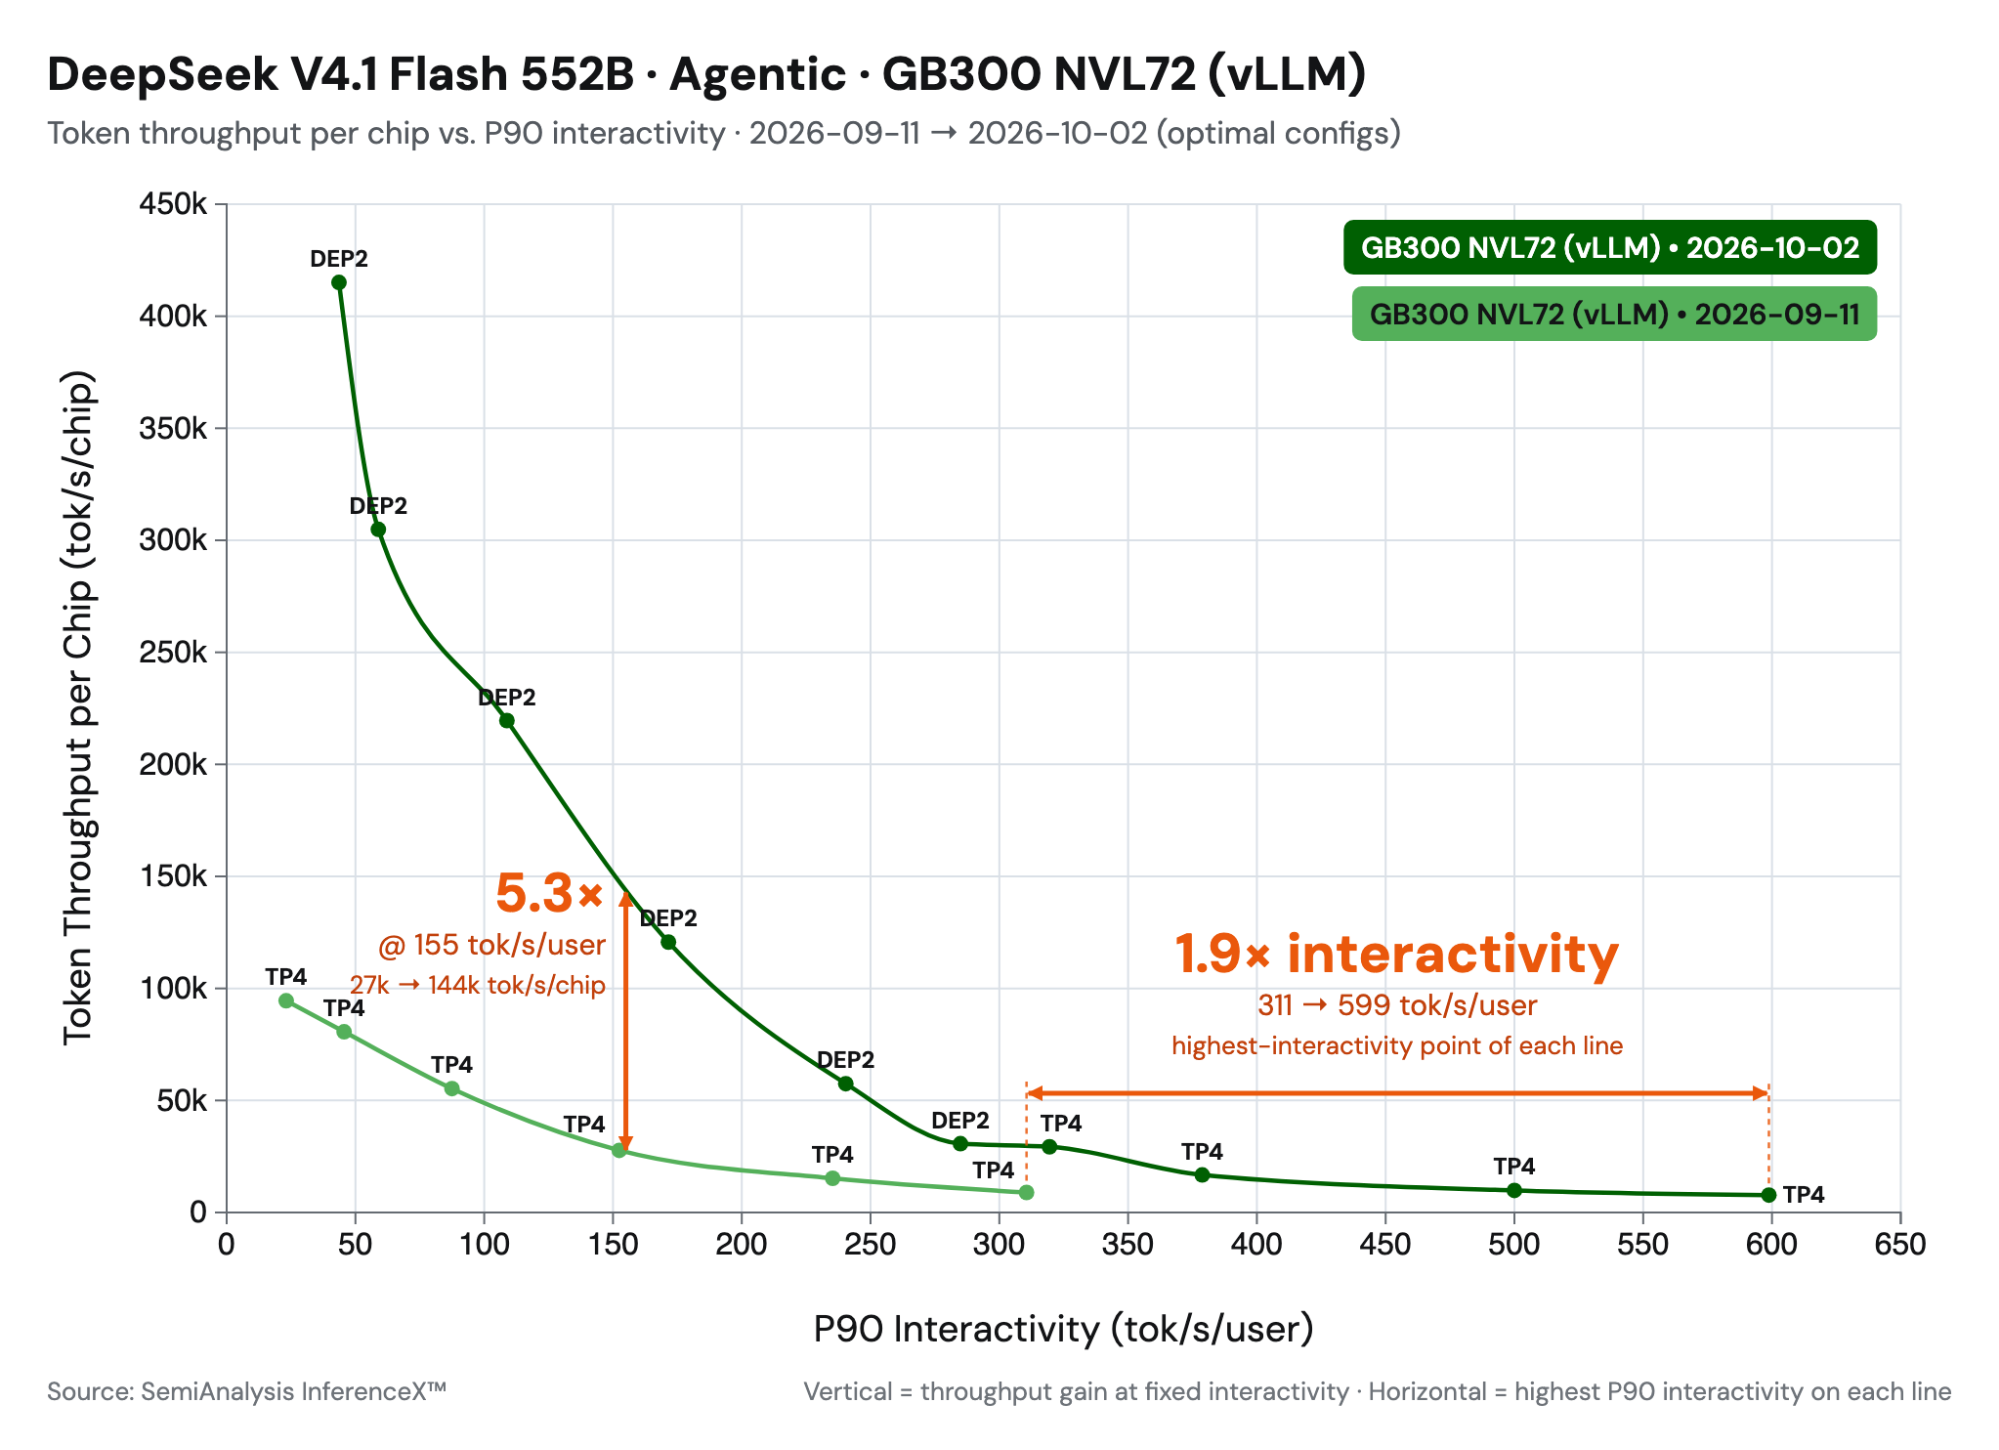
ToolsDeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 vLLM Blog

LabsTurning Database Grading into RL Rewards: Post-Training Agents with ThinkingBox Hugging Face Blog