vLLM BlogTools
Hyper Optimizing Kimi K3 in vLLM: Moving Fast and Responsibly
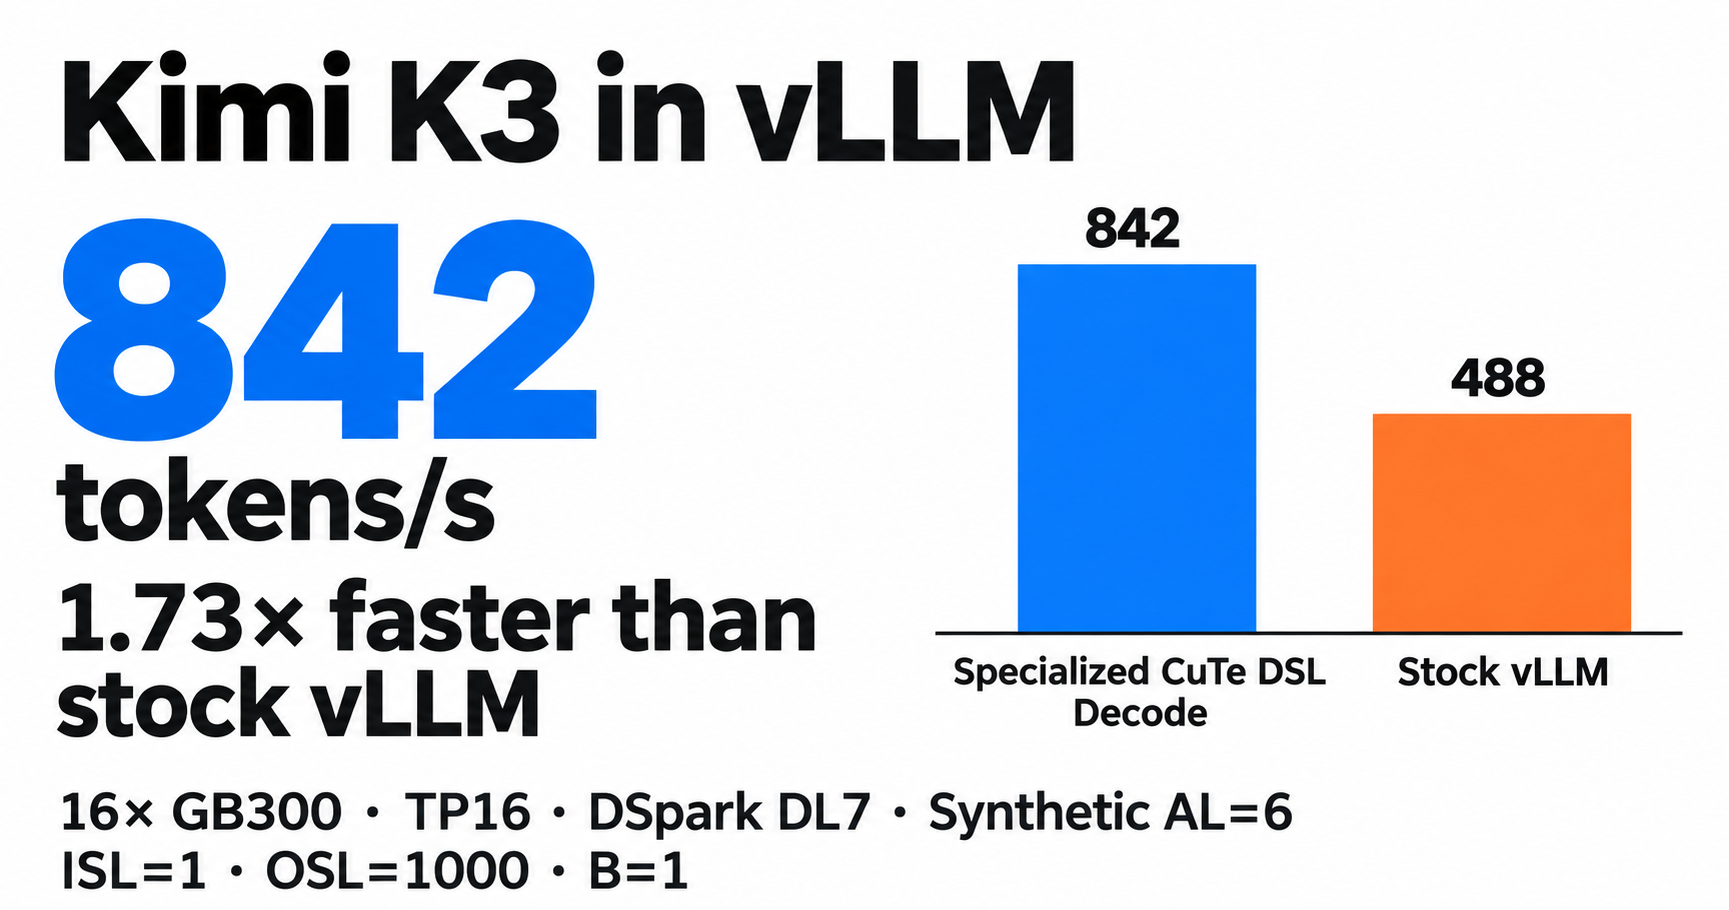
How agent-assisted CuTe DSL optimizations accelerate Kimi K3 decode on NVIDIA GB300, and how scoped changes, correctness tests, and reproducible benchmarks help ship them responsibly.
Read at vLLM Blog ↗Related
ToolsDay 0 support for Muse Spark Open on vLLM vLLM Blog
ToolsAnnouncing Day 0 Support for NVIDIA Nemotron 3.5 Super VL on vLLM vLLM Blog
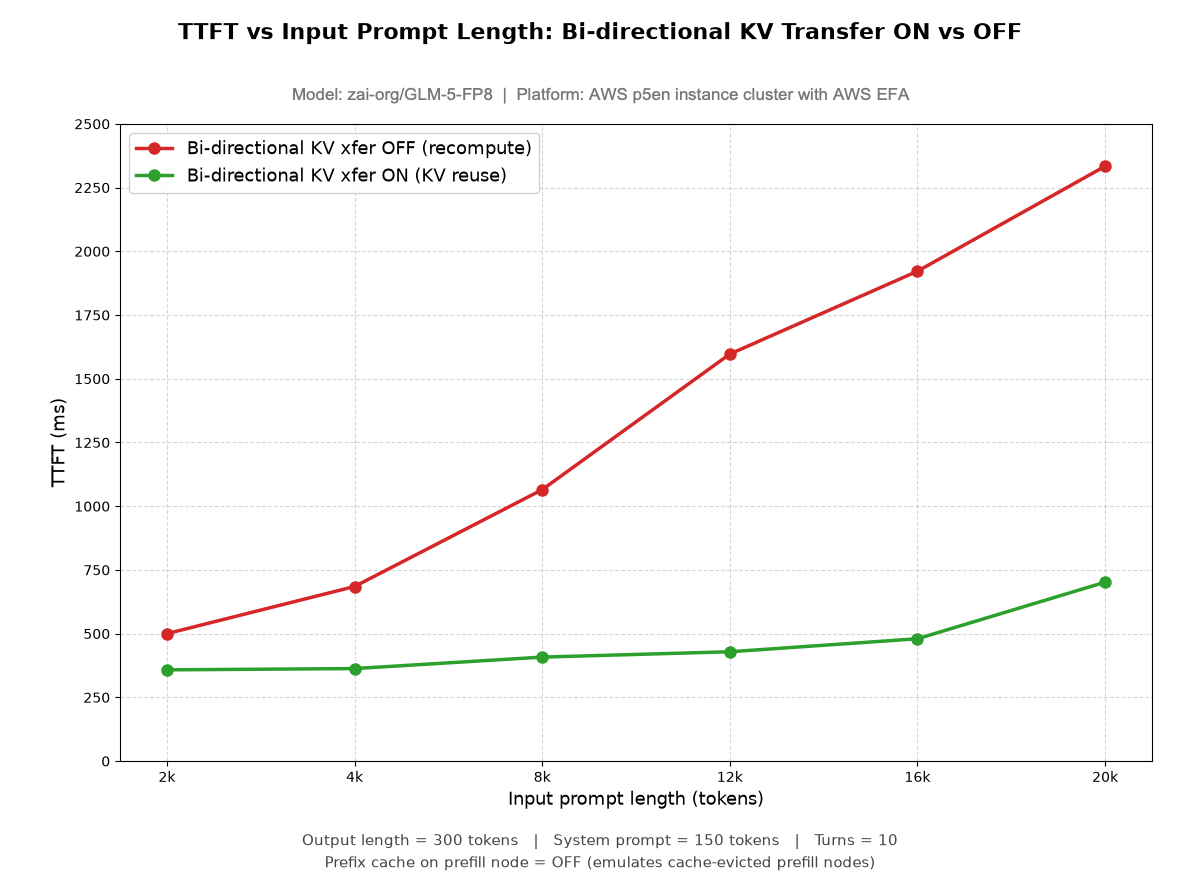
ToolsImprove TTFT for Multi-Turn Agentic Workloads with Bi-Directional KV Transfer in vLLM vLLM Blog
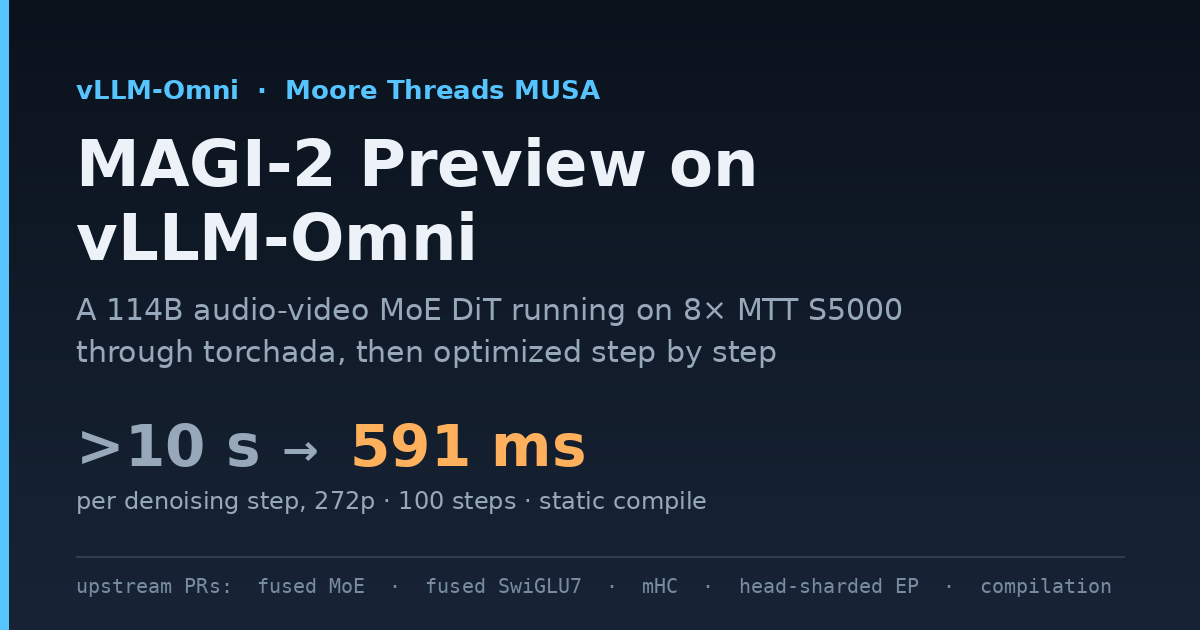
ToolsMAGI-2 Preview on vLLM-Omni: Bringing a 114B Audio-Video MoE DiT to Moore Threads MUSA with torchada vLLM Blog
ToolsvLLM Support for NVIDIA Vera Rubin NVL72: 7.8x Throughput over GB200 NVL72 vLLM Blog