vLLM BlogTools
Serving Reflection Beam on vLLM from Day 0
vLLM supports Reflection's Beam-1.0 (501B total, 23B active) from day 0, with agent-driven optimization that cut decode latency 2.71× and DFlash2 speculative decoding with adaptive verification.
Read at vLLM Blog ↗Related
ToolsDay 0 support for Muse Spark Open on vLLM vLLM Blog
ToolsMAGI-2 Preview on vLLM-Omni: Bringing a 114B Audio-Video MoE DiT to Moore Threads MUSA with torchada vLLM Blog
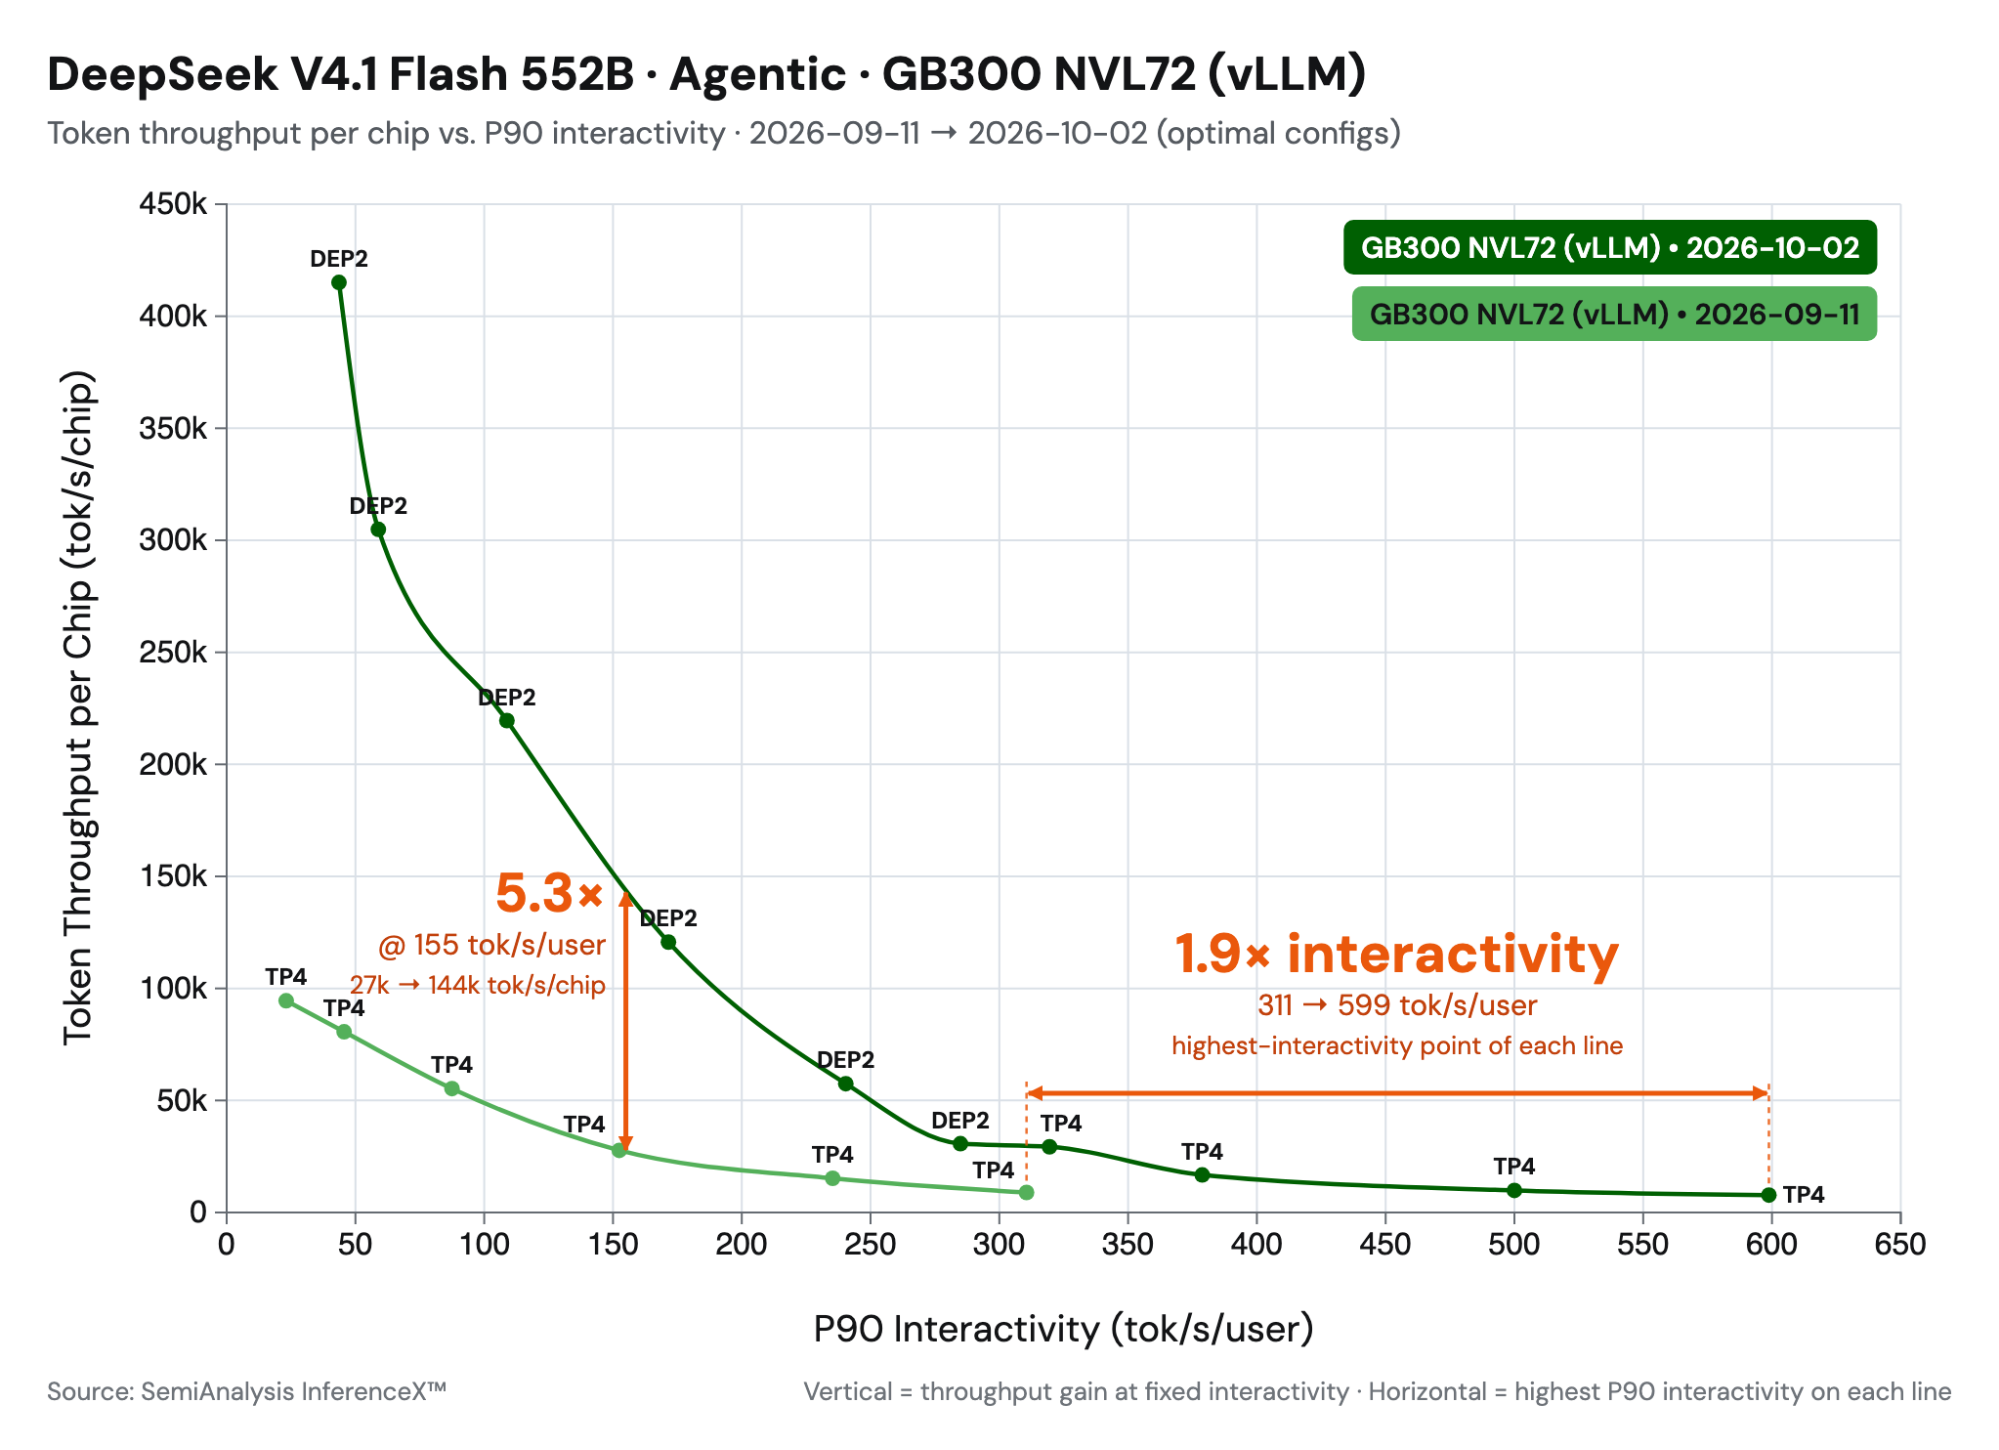
ToolsDeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 vLLM Blog

LabsWelcome Muse Spark Open: open-weight frontier multimodal mixture-of-experts model from Meta Hugging Face Blog

LabsRun fast, private agents on-device with LFM2.5-24B-A2B Hugging Face Blog