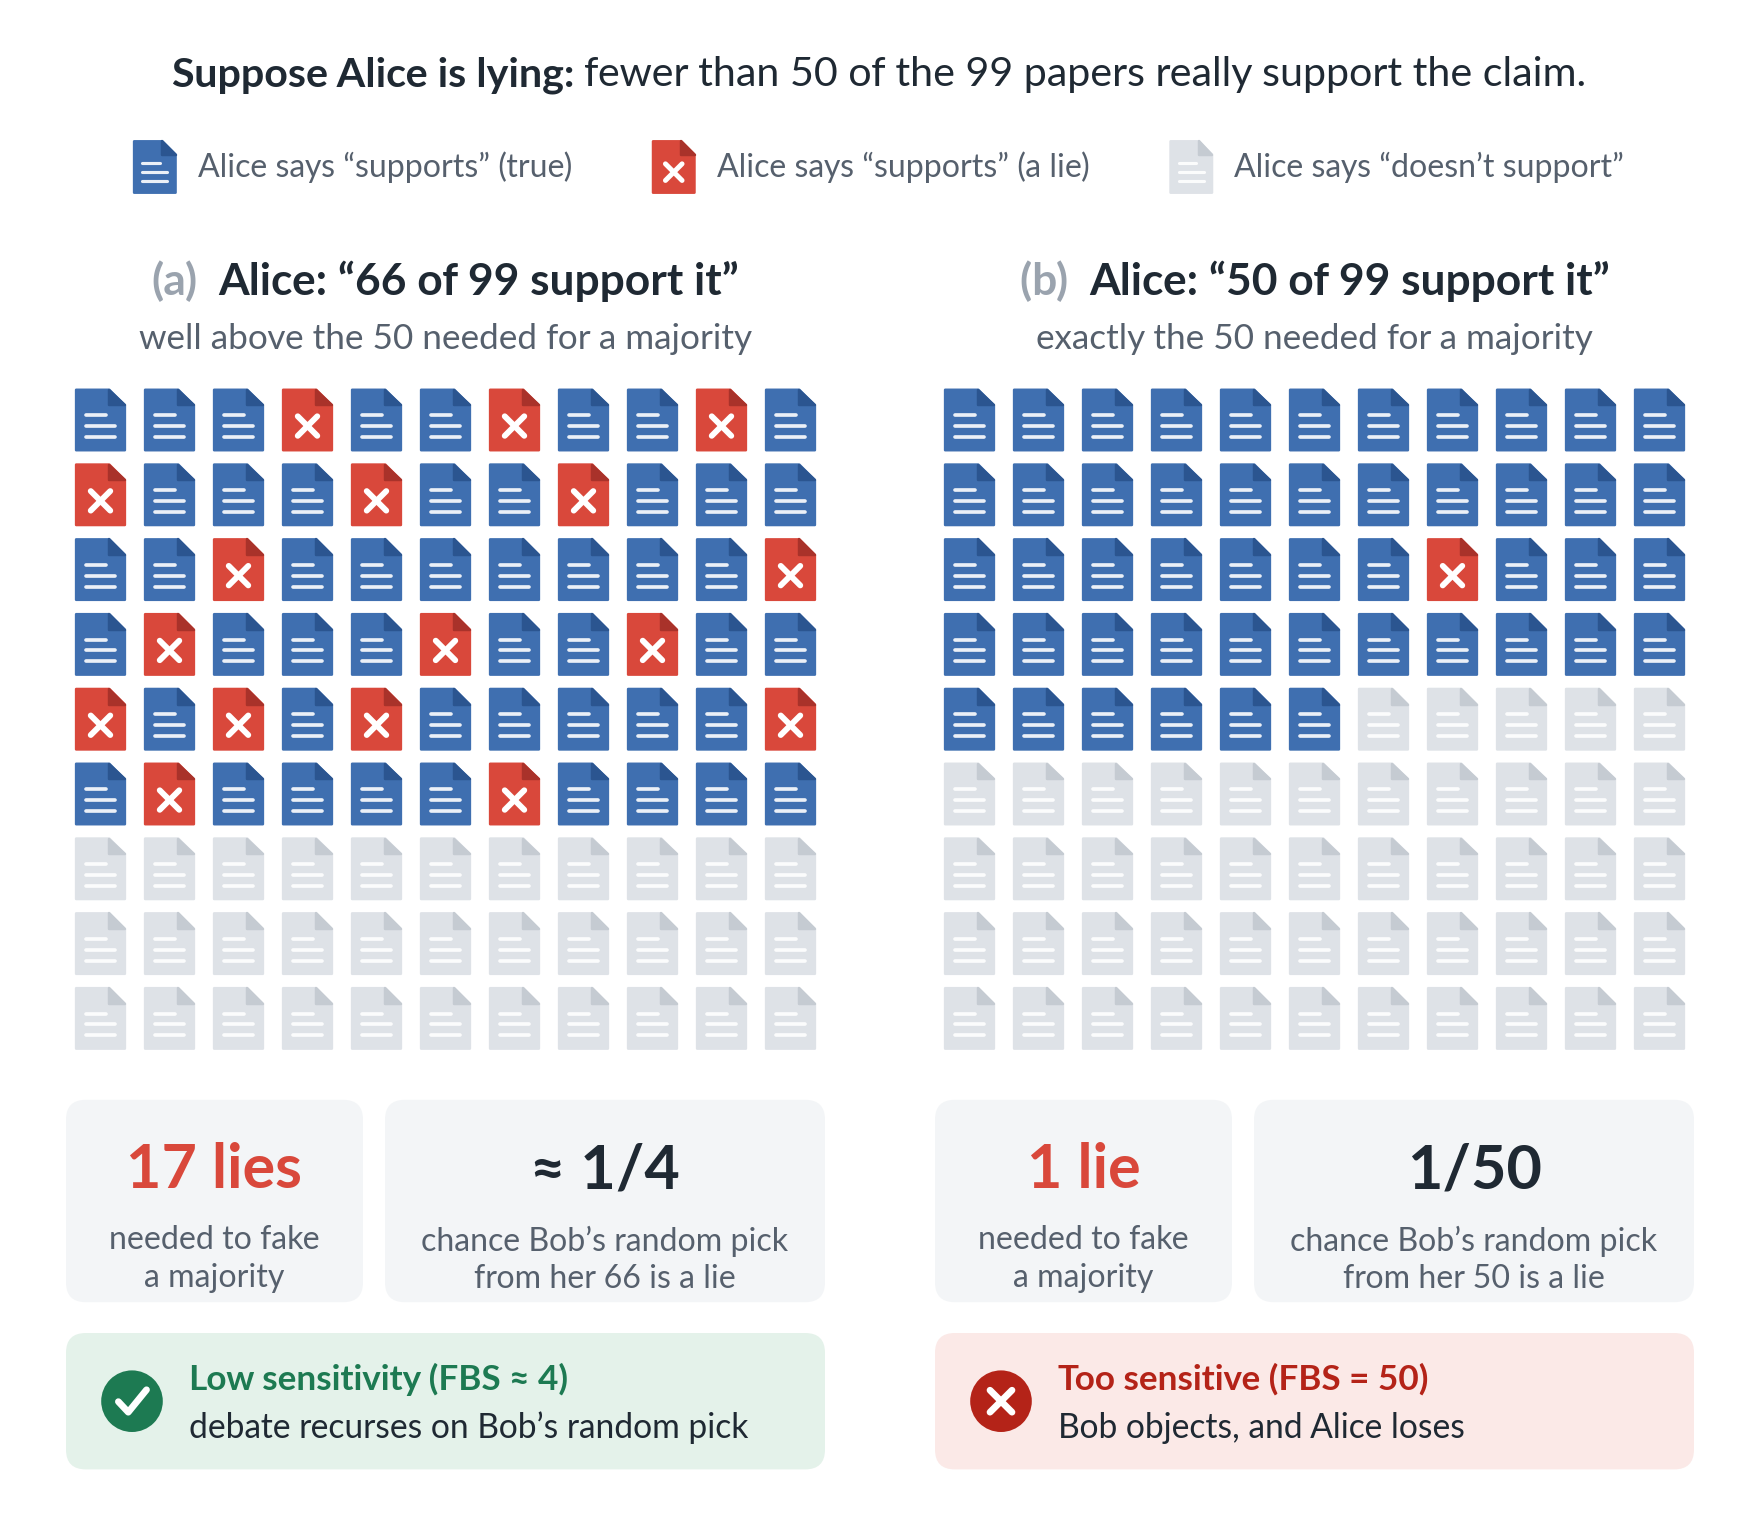
Google Cloud AILabs
Who judges the judge? Three helpful ways to audit your LLM evaluators

Is your LLM-as-a-judge truly objective? There’s a common misconception in tech that humans are subjective, so we should rely on AI for objective evaluation.
Read at Google Cloud AI ↗Related
LabsFour evaluation engineering lessons learned from building agent plugins Google Cloud AI
SiliconEdge AI for Smart Cities: From Insight to Cognitive Action IEEE Spectrum AI
ToolsHow Legora runs 2,000 parallel agent evals on Modal Sandboxes Modal
ToolsAchieving near-zero-downtime scaling in Elastic Expert Parallelism vLLM Blog

JapanElasticsearch の Autoscaling を改善する: scale-out の高速化と HPA tolerance の調整 Mercari Engineering