NVIDIA Technical BlogSilicon
Scaling NVIDIA TensorRT Performance Optimization Beyond a Single Build Route with the Global Performance Tuner, Part 1

Deploying a trained neural network involves more than translating each operator into a GPU kernel. It is a compilation problem with many legitimate answers. For...
Read at NVIDIA Technical Blog ↗Related

SiliconHow NVIDIA OpenShell Reference Architecture Secures and Governs AI Agent Workloads at Scale NVIDIA Technical Blog

SiliconNVIDIA Nemotron 3.5 Super VL Powers Specialized Agents with Multimodal Reasoning NVIDIA Technical Blog
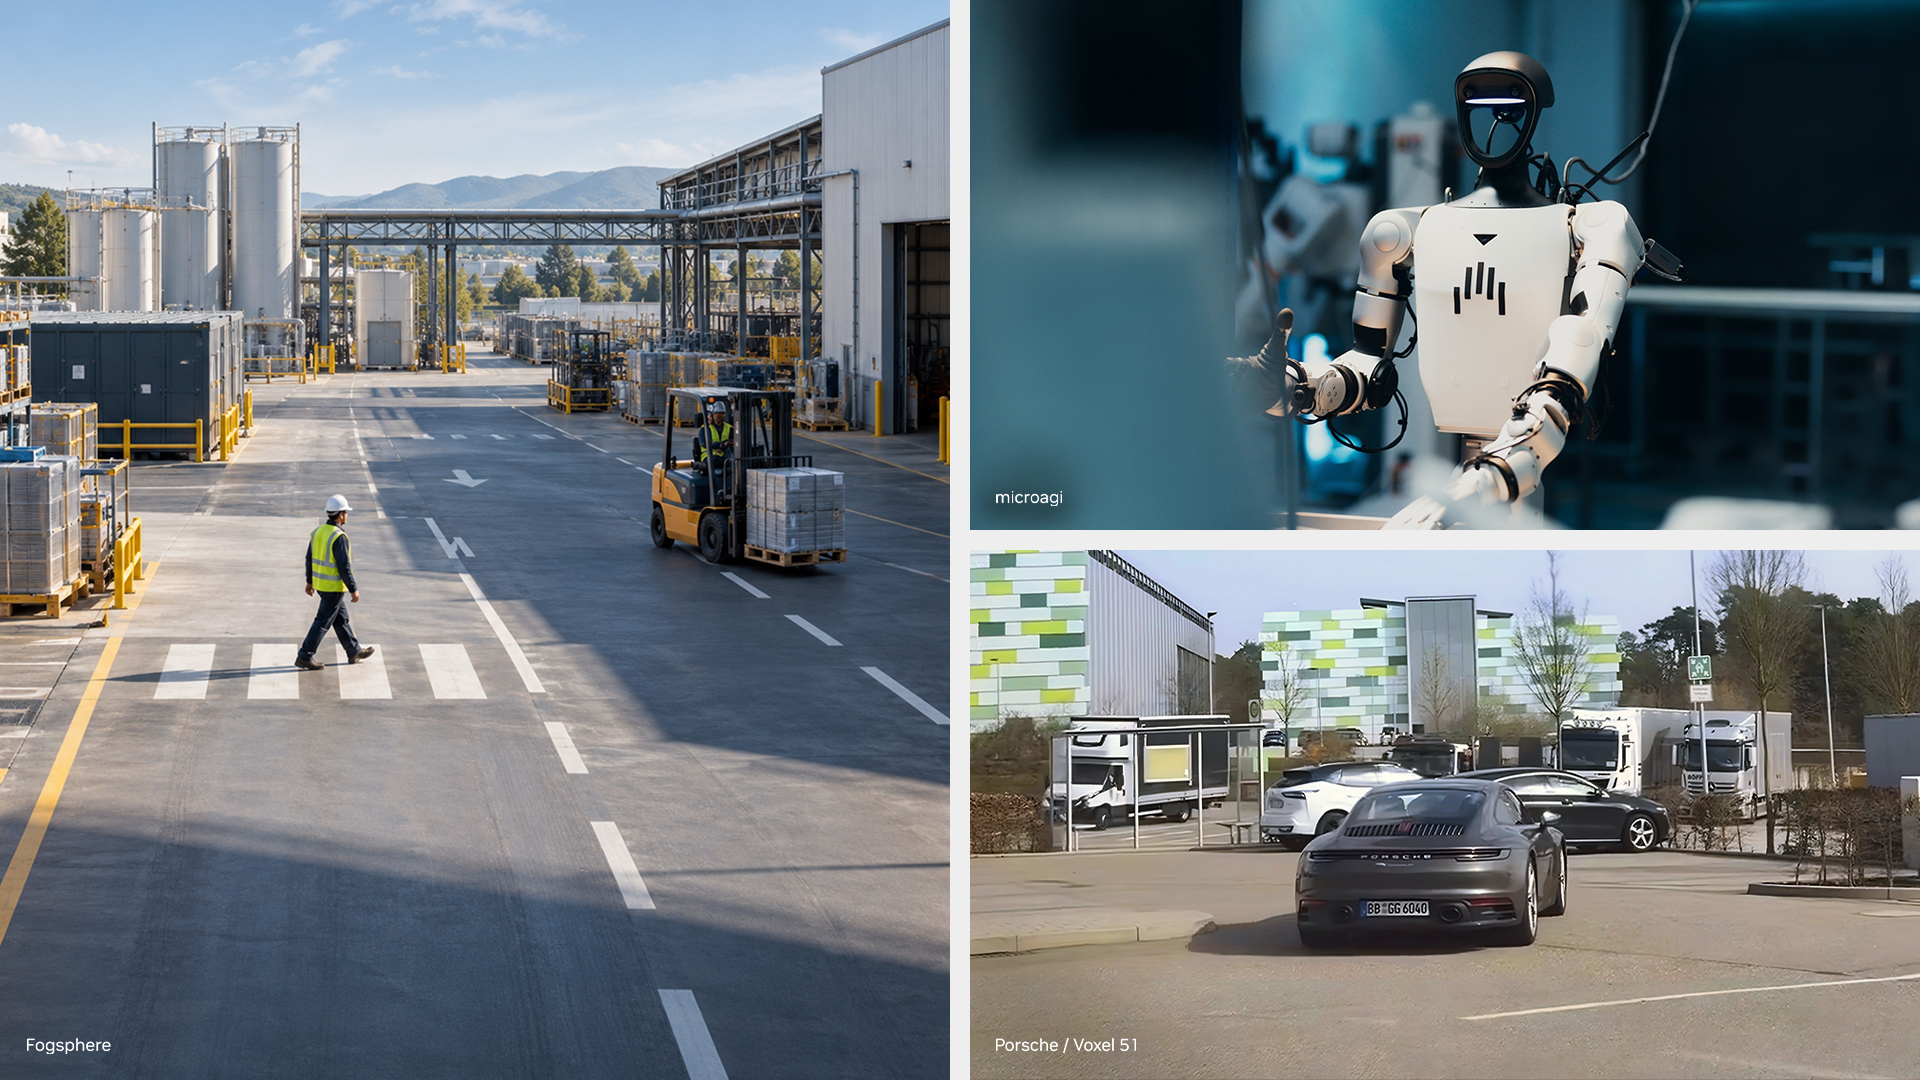
SiliconNVIDIA Cosmos Opens New Tools to Train, Evaluate and Deploy World Models NVIDIA Blog
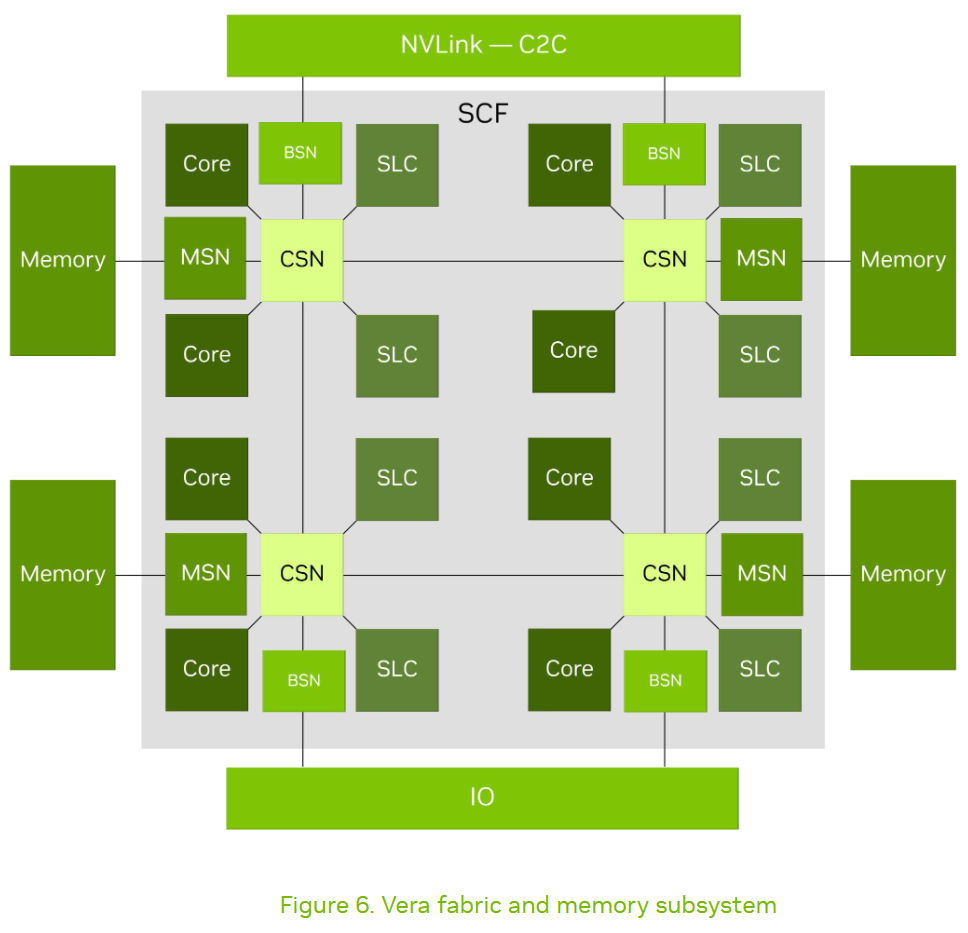
SiliconNvidia Vera’s System Architecture: Pushing Bandwidth Chips and Cheese
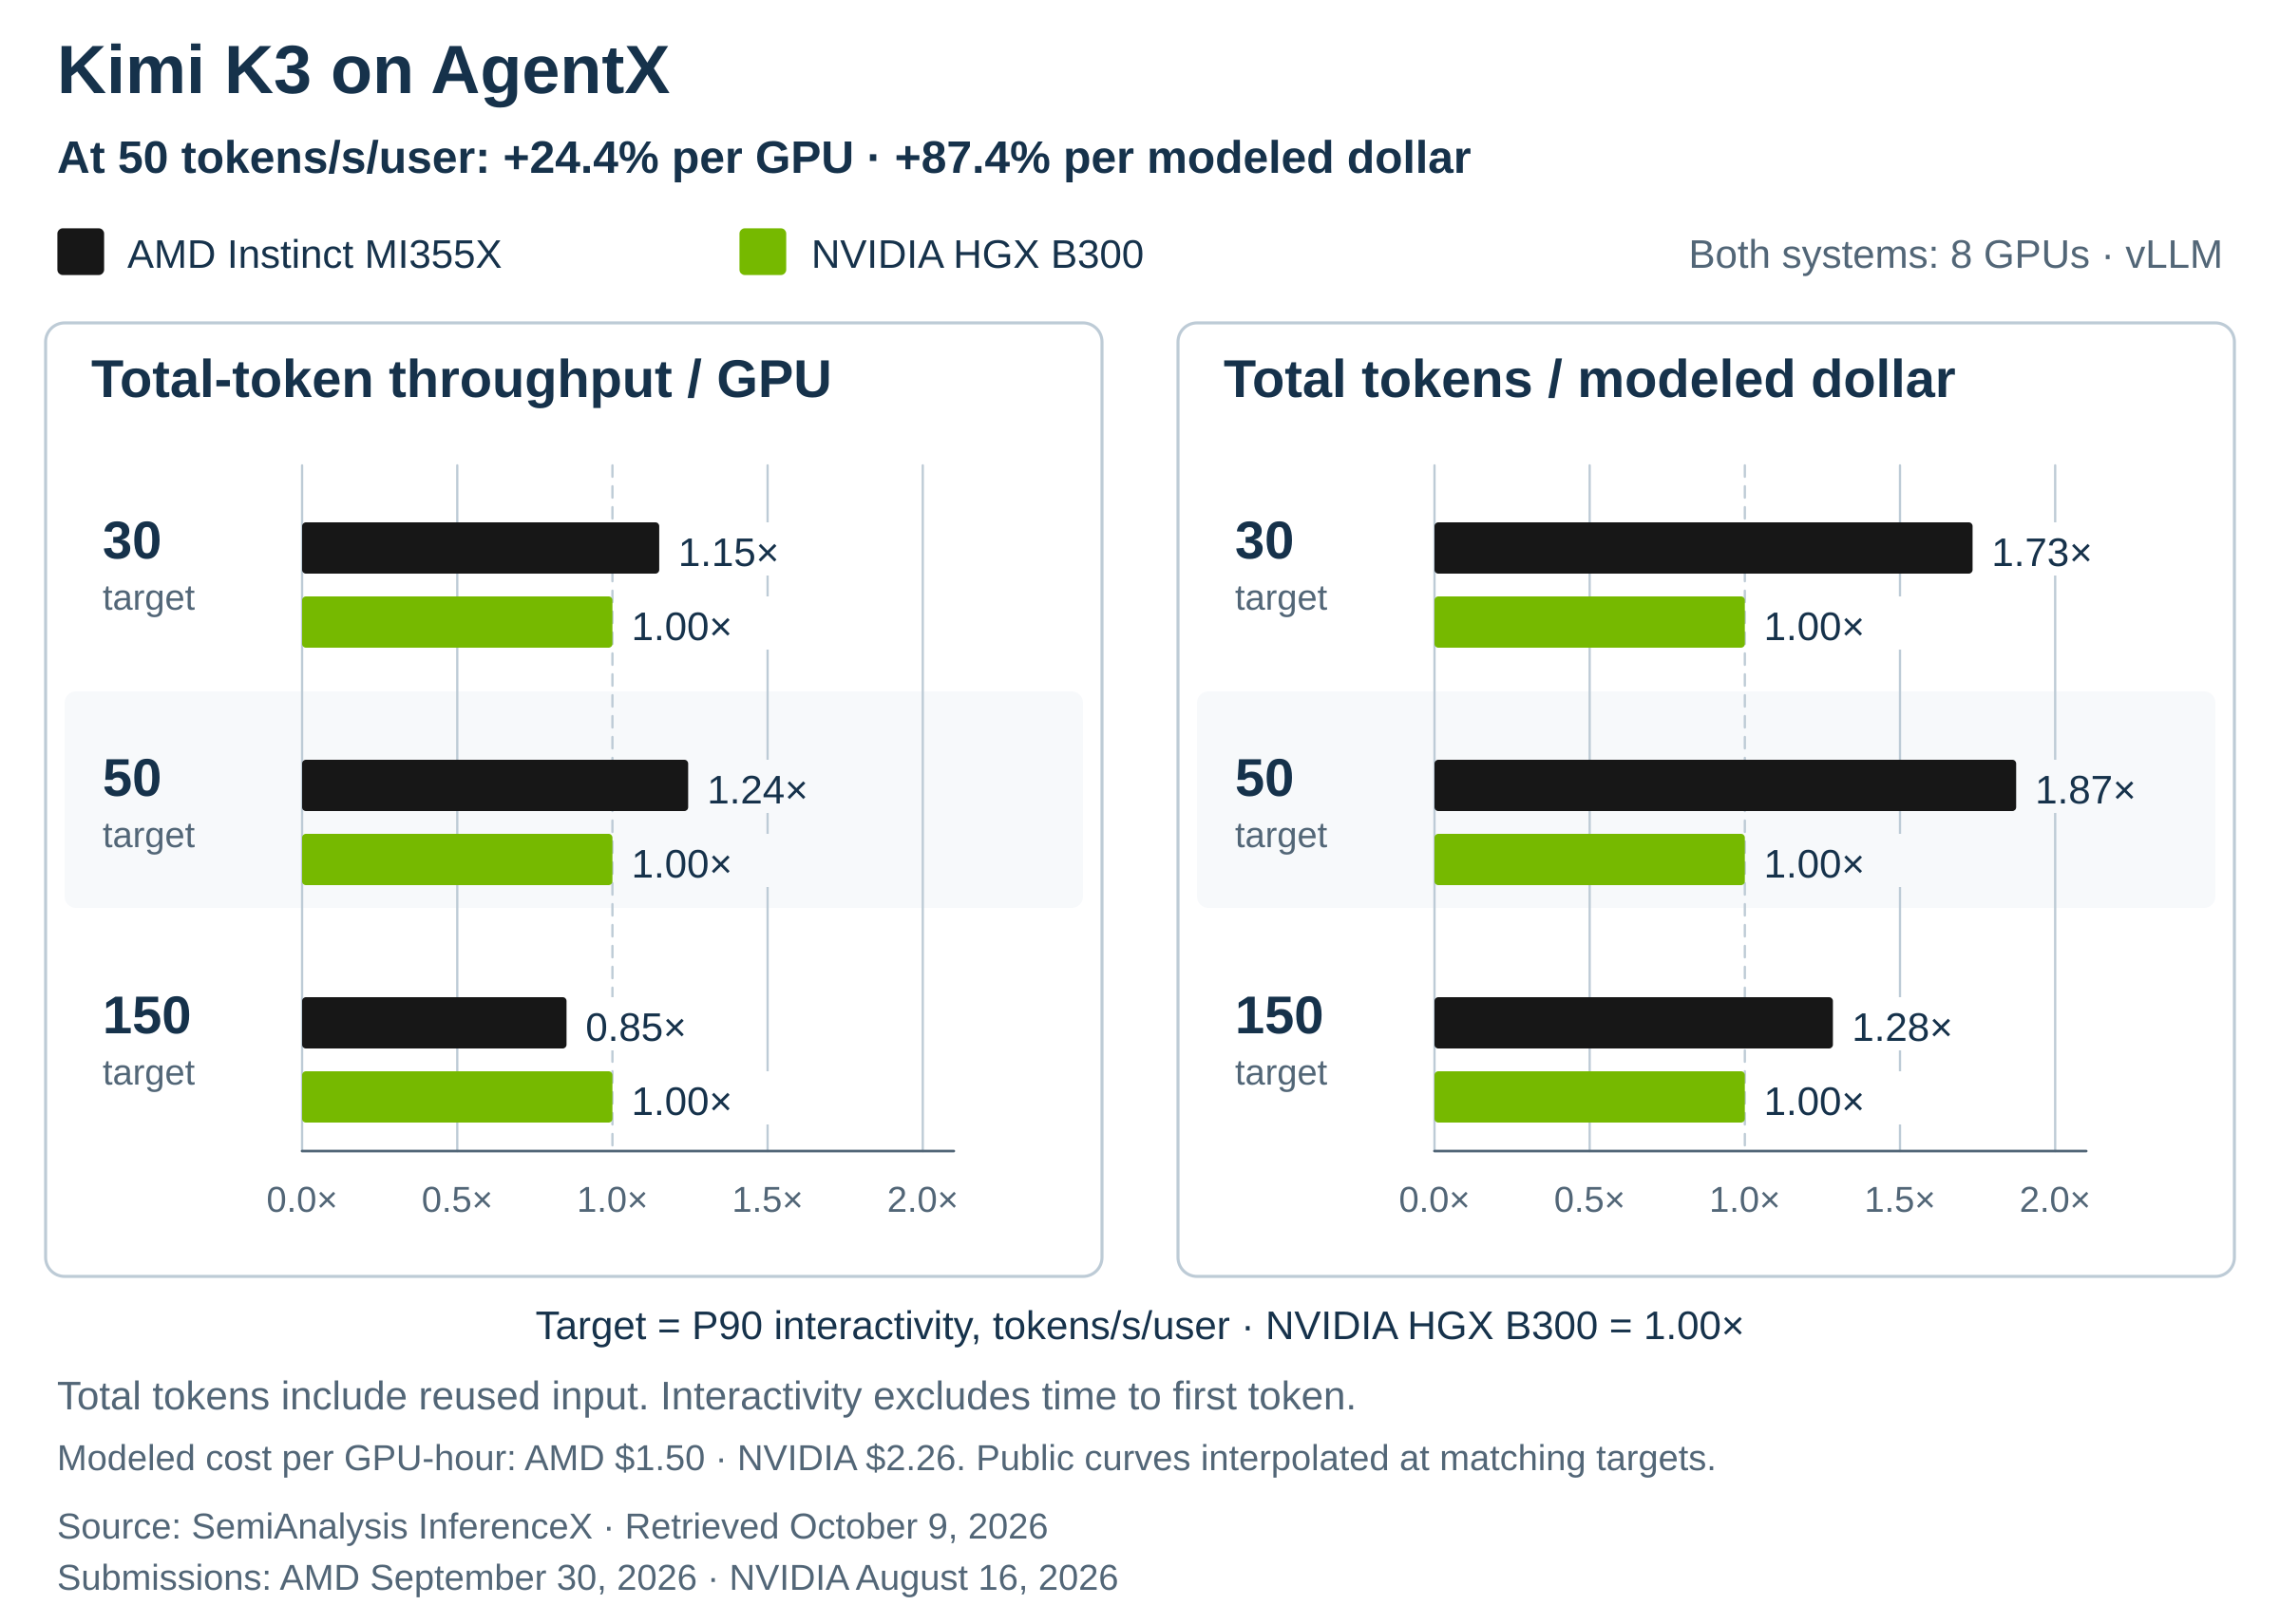
ToolsScaling Kimi K3 on AMD Instinct MI355X: Matching NVIDIA HGX B300 Throughput per GPU on AgentX vLLM Blog