NVIDIA Technical BlogSilicon
Scale Bitwise-Deterministic Pretraining with NVIDIA Megatron Core

Bitwise determinism makes large-scale pretraining easier to debug, validate, and resume reproducibly. These benefits become especially valuable when training...
Read at NVIDIA Technical Blog ↗Related
SiliconWhen One Datacenter Is No Longer Enough The Next Platform

ResearchShould We Track AI Chips? CSET Georgetown
ToolsExpanding our enterprise inference capacity with IBM Cloud and NVIDIA Together AI
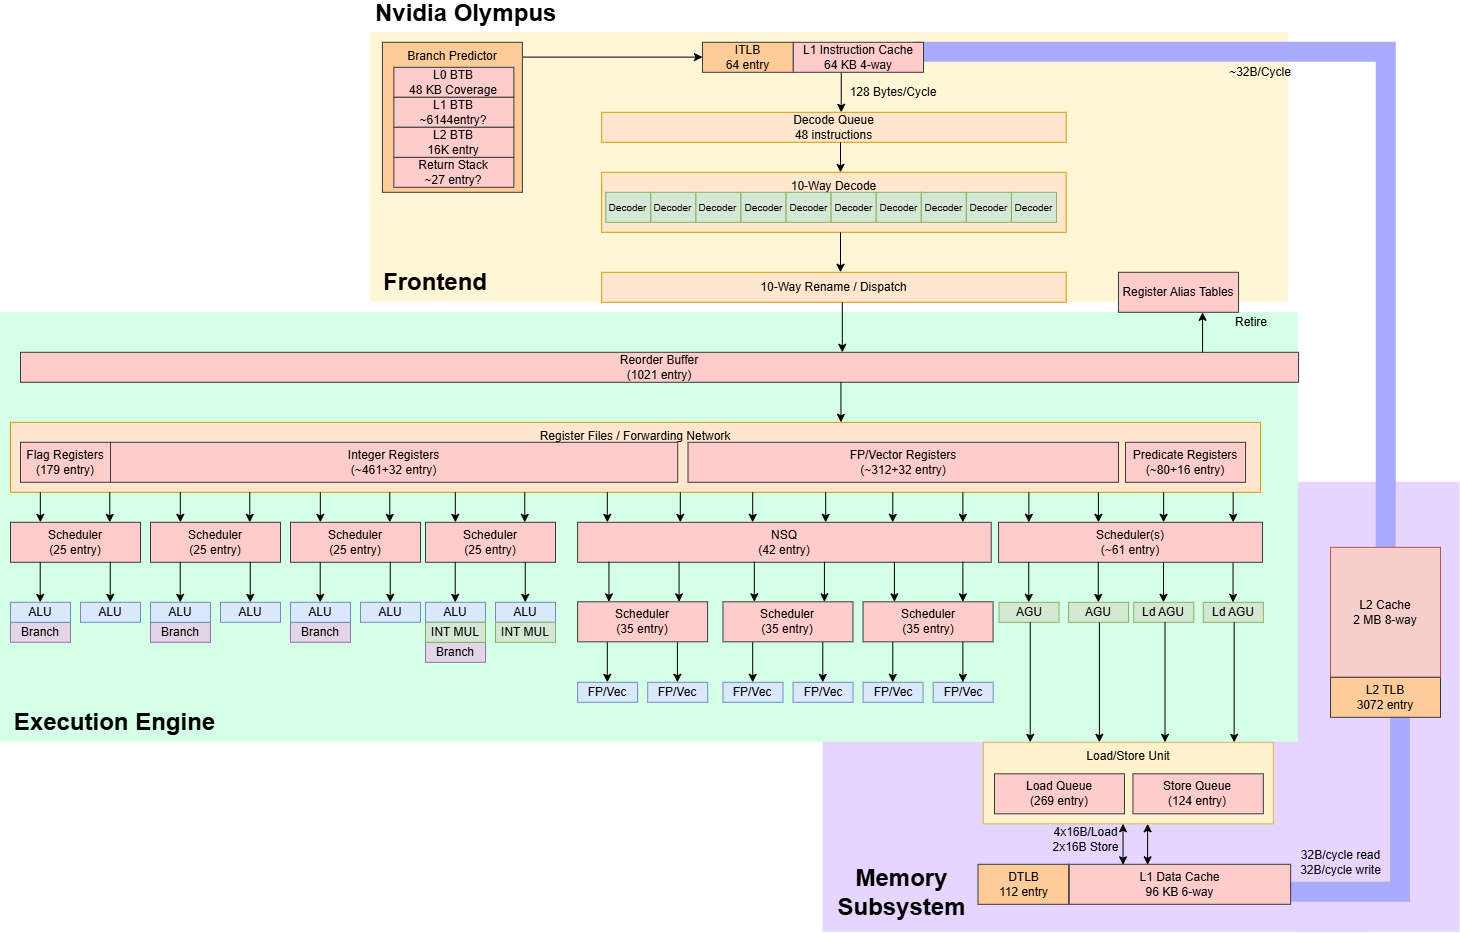
SiliconNVIDIA’s Olympus Core: Pushing Server Single Threaded Performance Boundaries Chips and Cheese
VoicesOpen models and the future of Physical AI with NVIDIA Practical AI