PyTorch BlogTools
From KTIR to SpyreCode: An MLIR Dataflow Backend for IBM Spyre
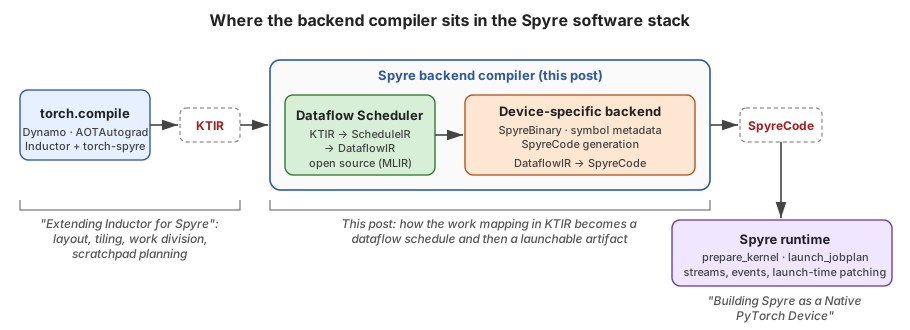
TL;DR Torch-spyre’s Inductor decides how each kernel’s work is divided across Spyre’s cores and manages tensor residency between on-chip scratchpad and off-chip memory, and the backend compiler turns…
Read at PyTorch Blog ↗Related
VoicesPhysical AI at NVIDIA Software Engineering Daily

LabsHugging Face ❤️ TorchTPU: TPUs, Natively Hugging Face Blog
ToolsIntroducing vLLM TorchTPU vLLM Blog
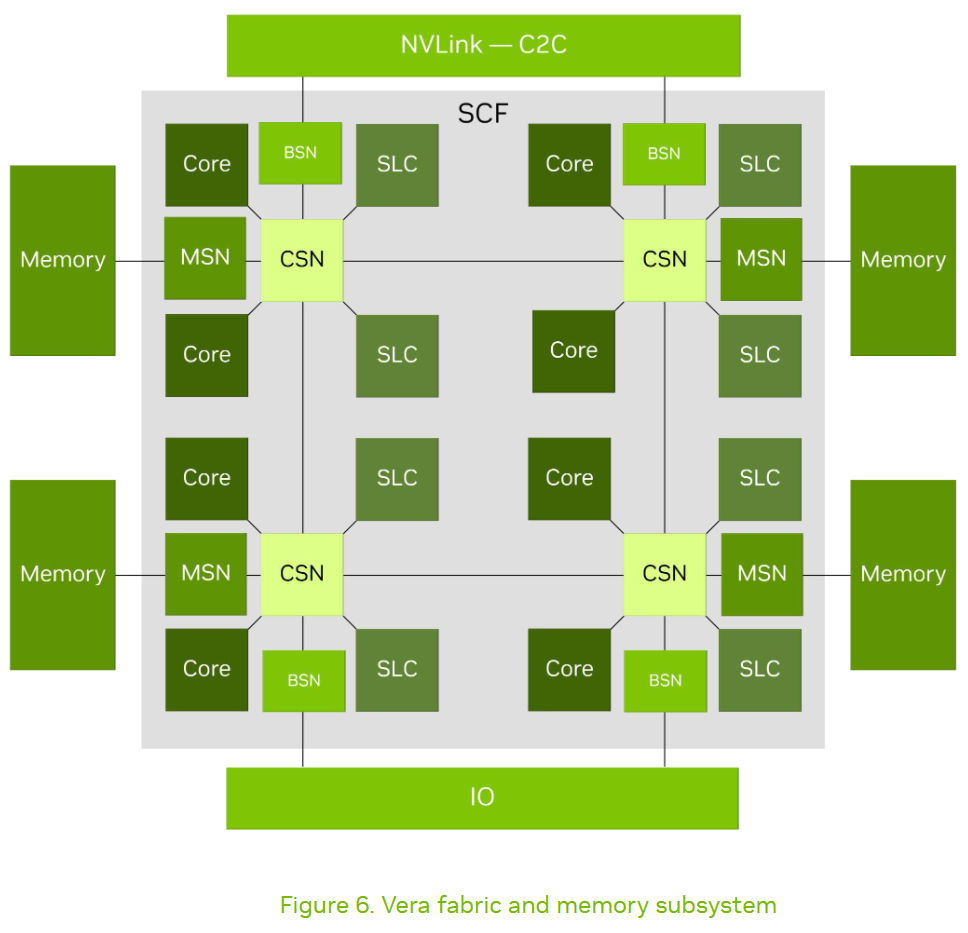
SiliconNvidia Vera’s System Architecture: Pushing Bandwidth Chips and Cheese

SiliconAccelerating Mamba-2 with High-Performance Forward Pass Kernels in NVIDIA CUDA Tile NVIDIA Technical Blog