JetBrains BlogTools
Coding-Agent Benchmarks Should Match Their Users’ Task Flows
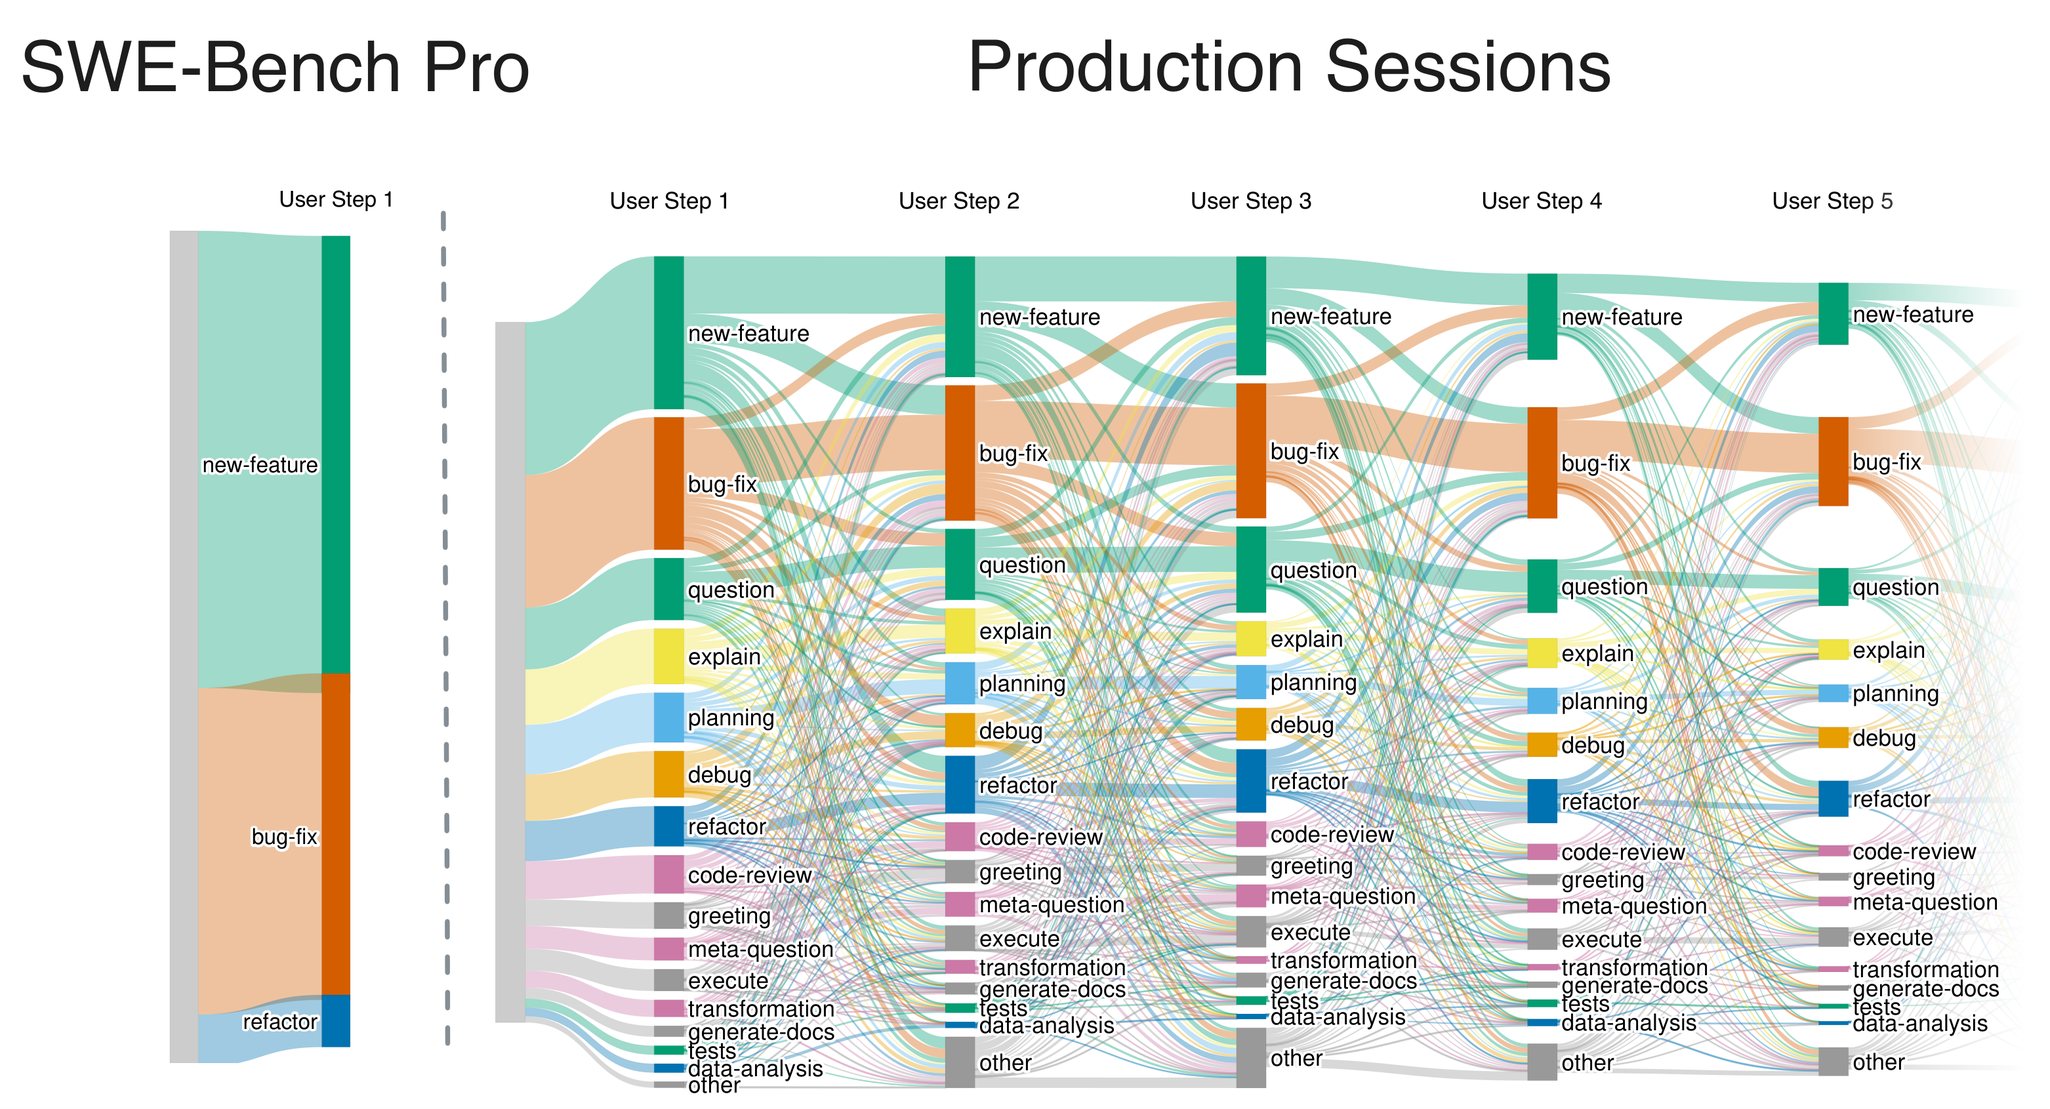
Left: SWE-Bench Pro, where each task is a single user message, almost always a new feature or a bug fix.
Read at JetBrains Blog ↗Related
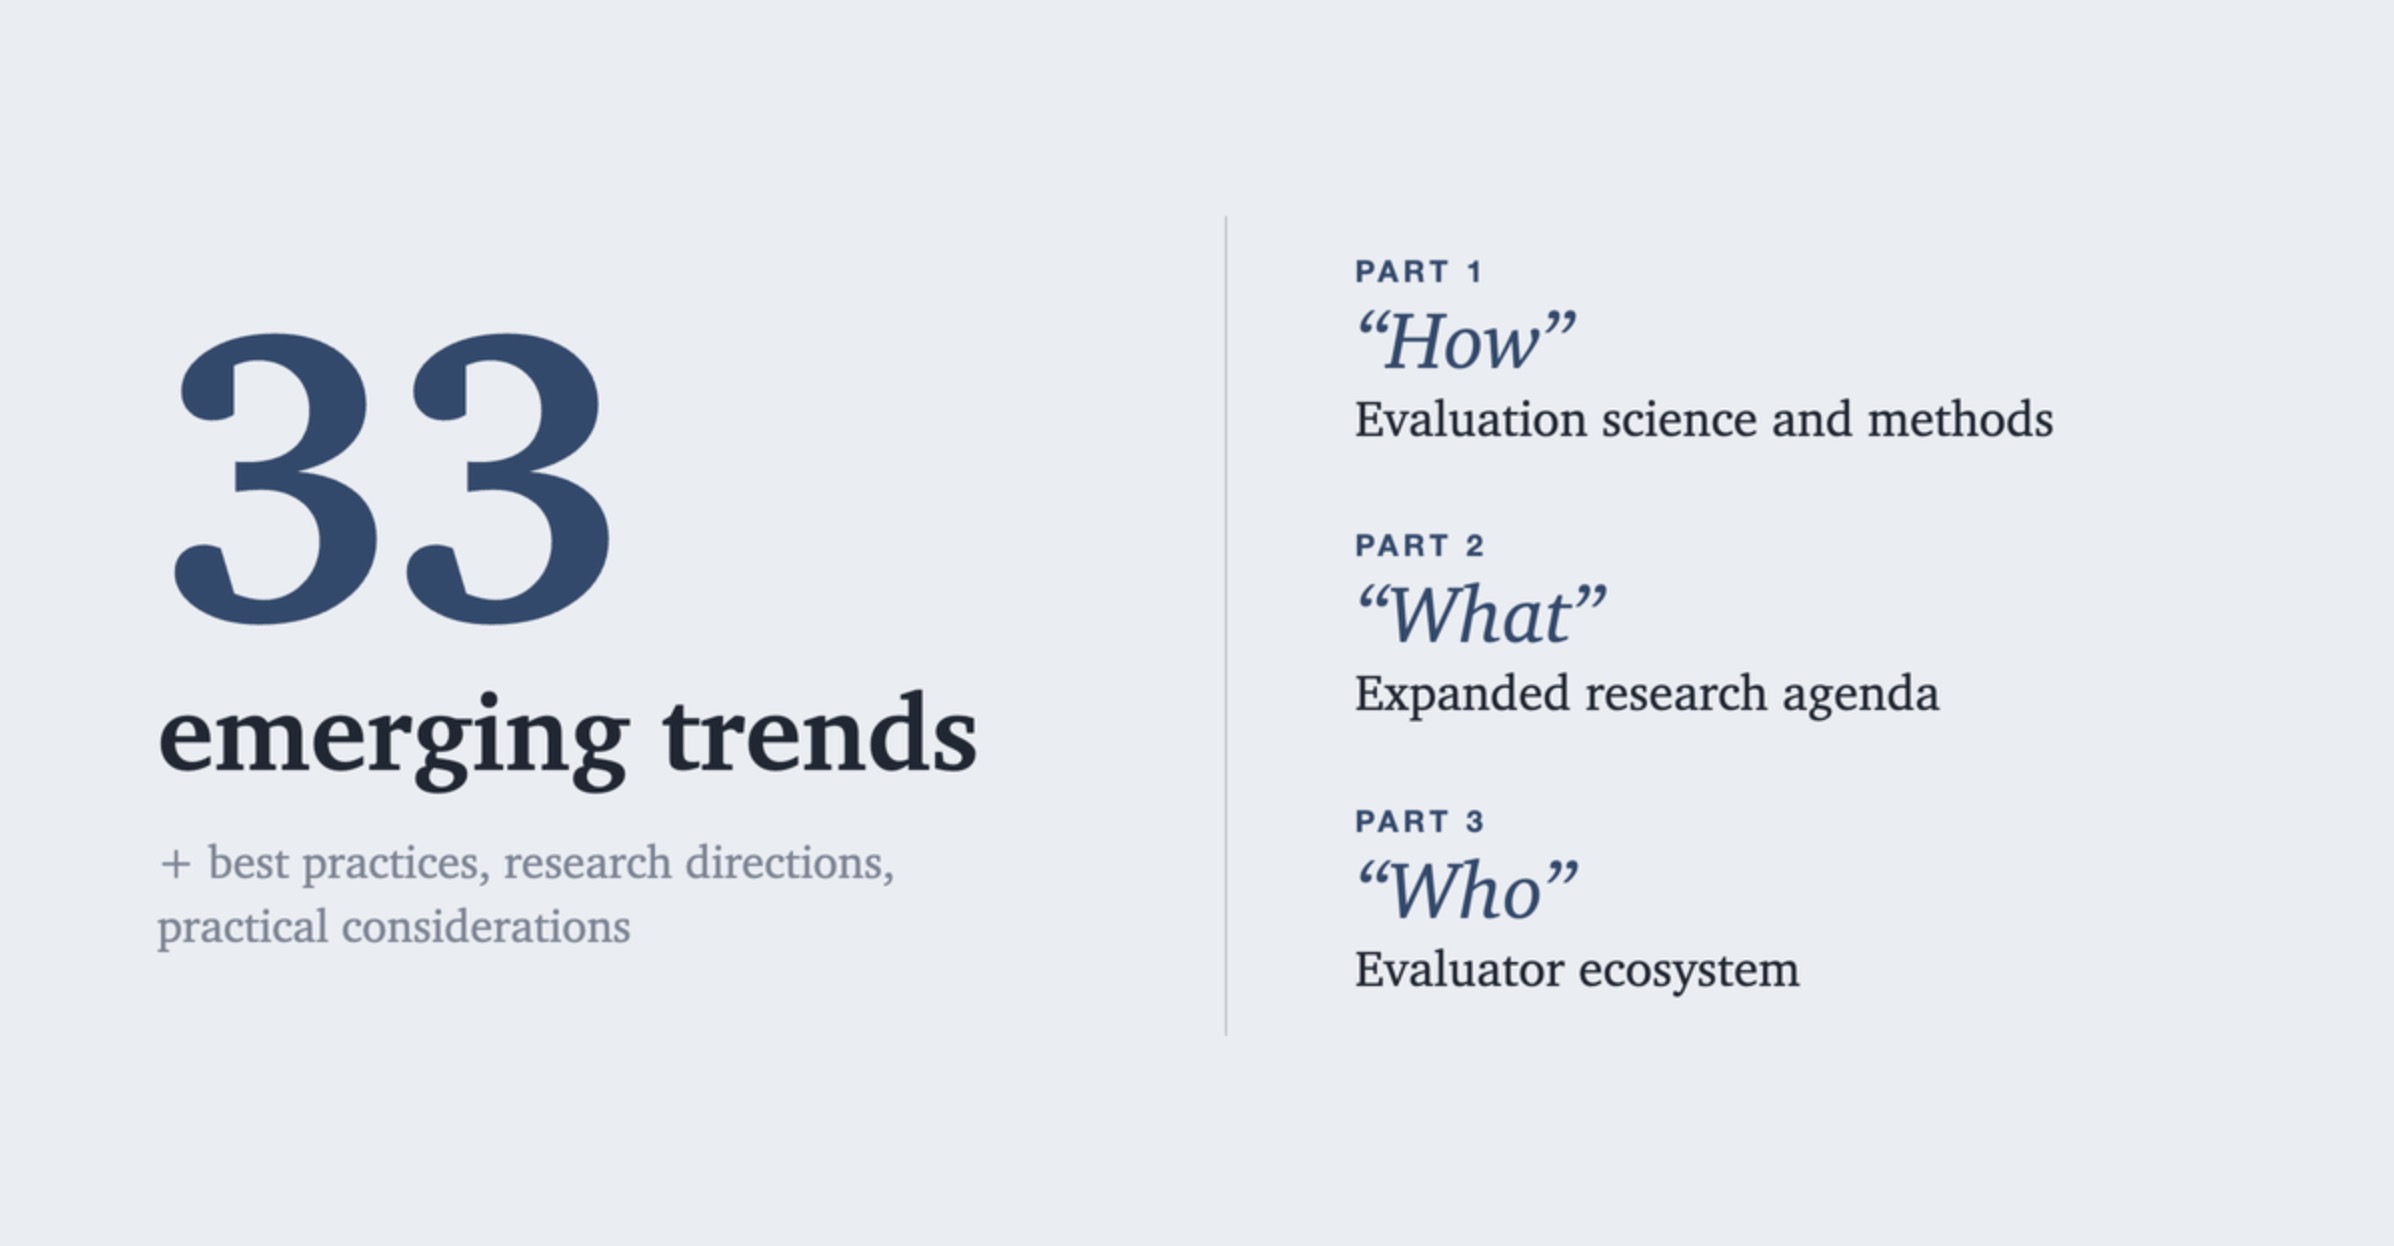
VoicesNew paper: Emerging trends in AI agent evaluation AI Snake Oil
GitHubArticle: From Microservices to Agents: the Next Evolution of Distributed Systems InfoQ AI
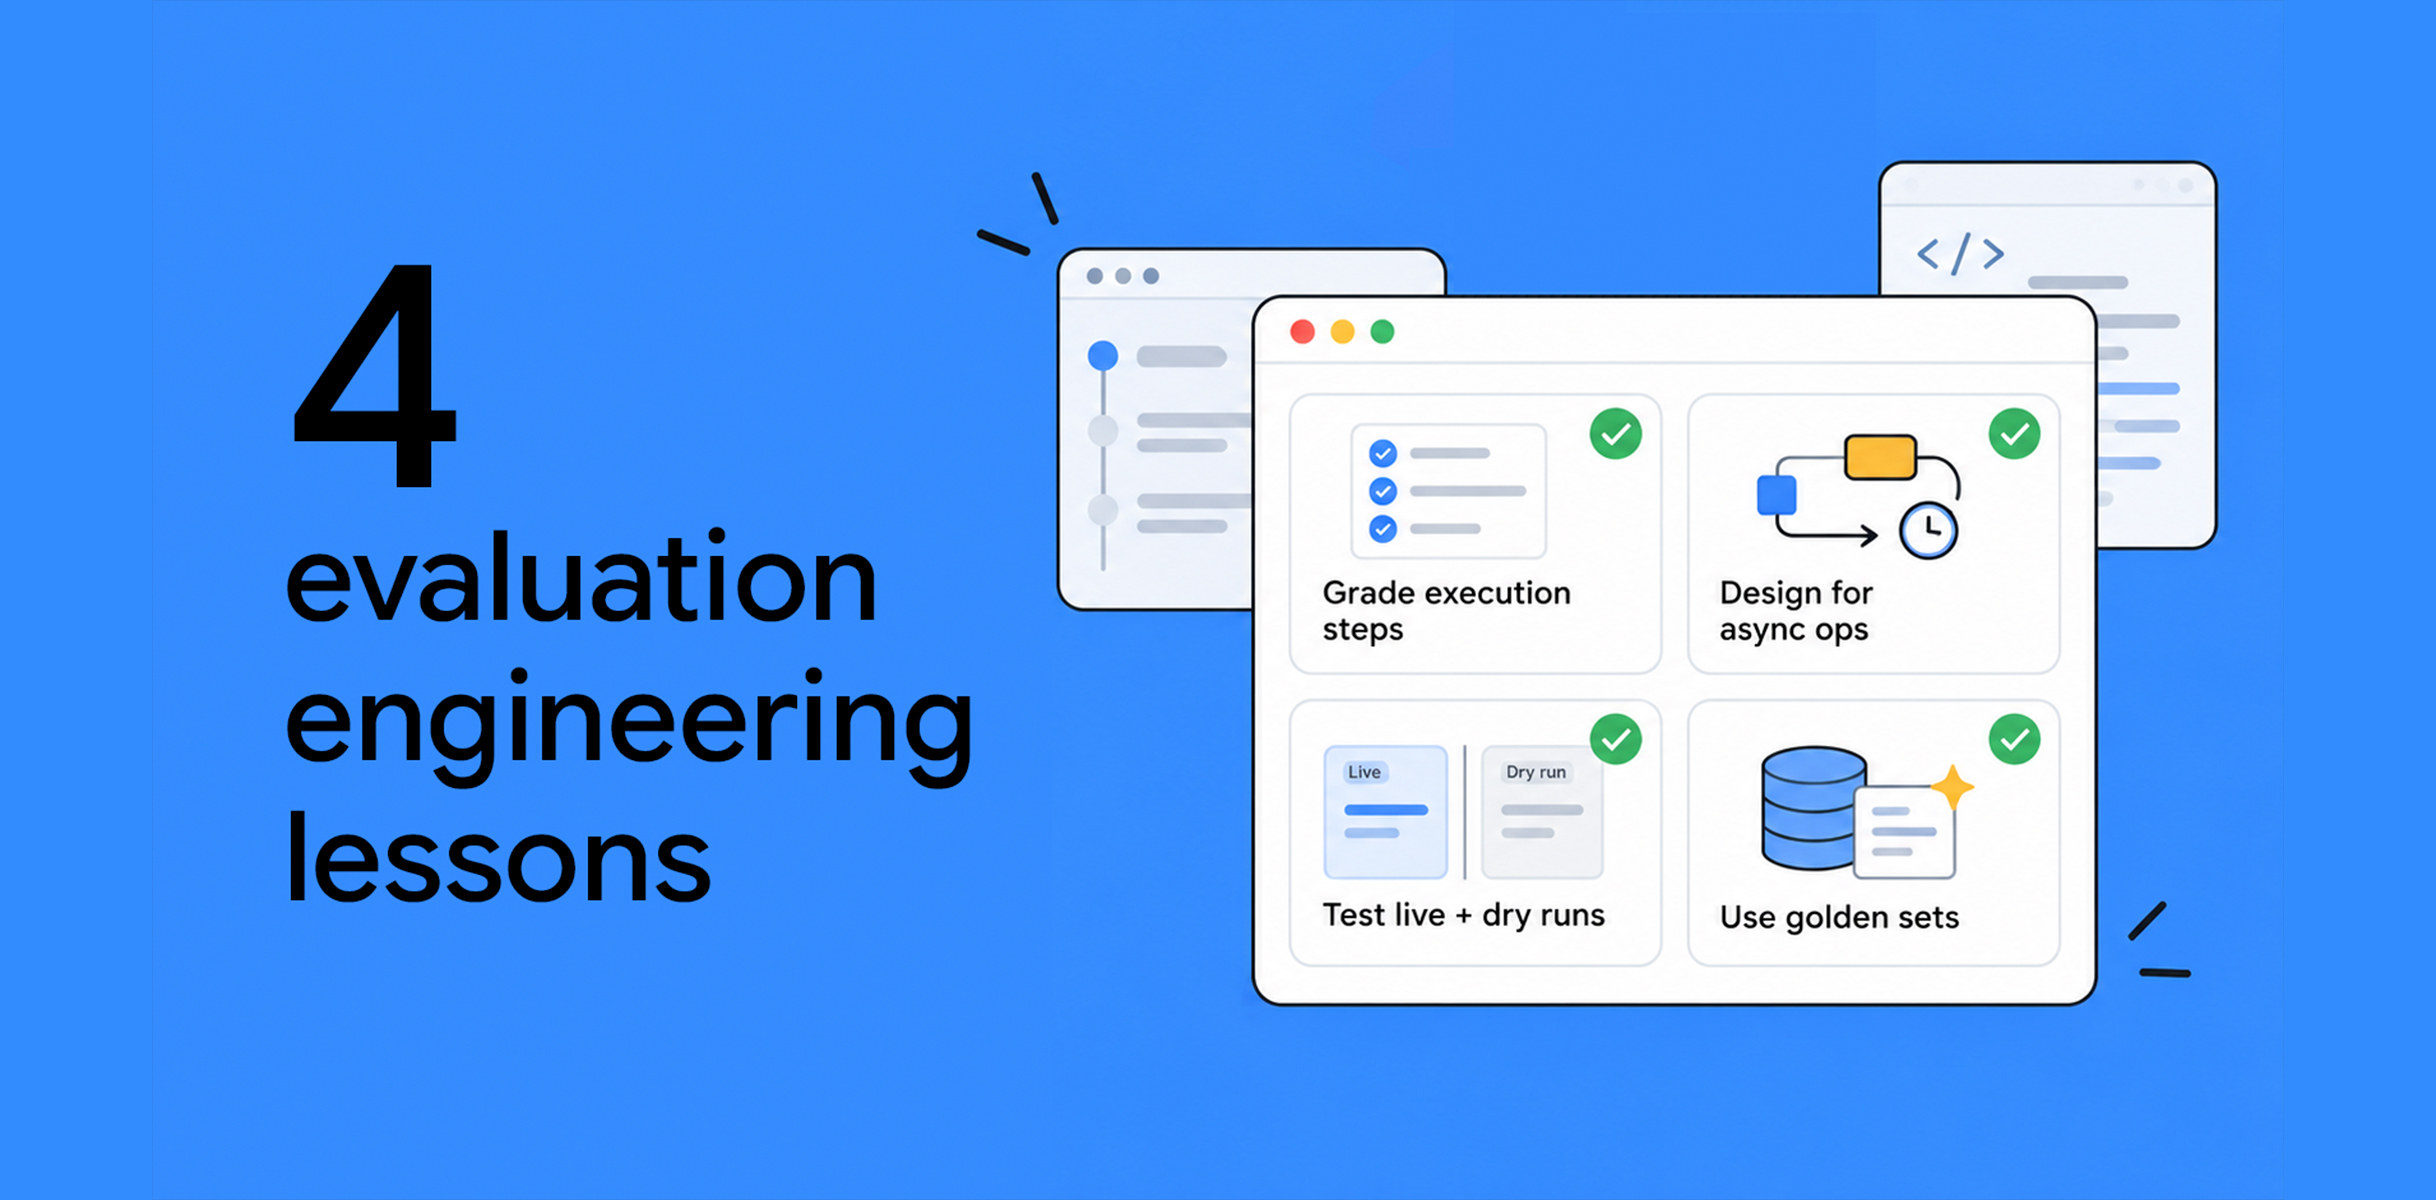
LabsFour evaluation engineering lessons learned from building agent plugins Google Cloud AI
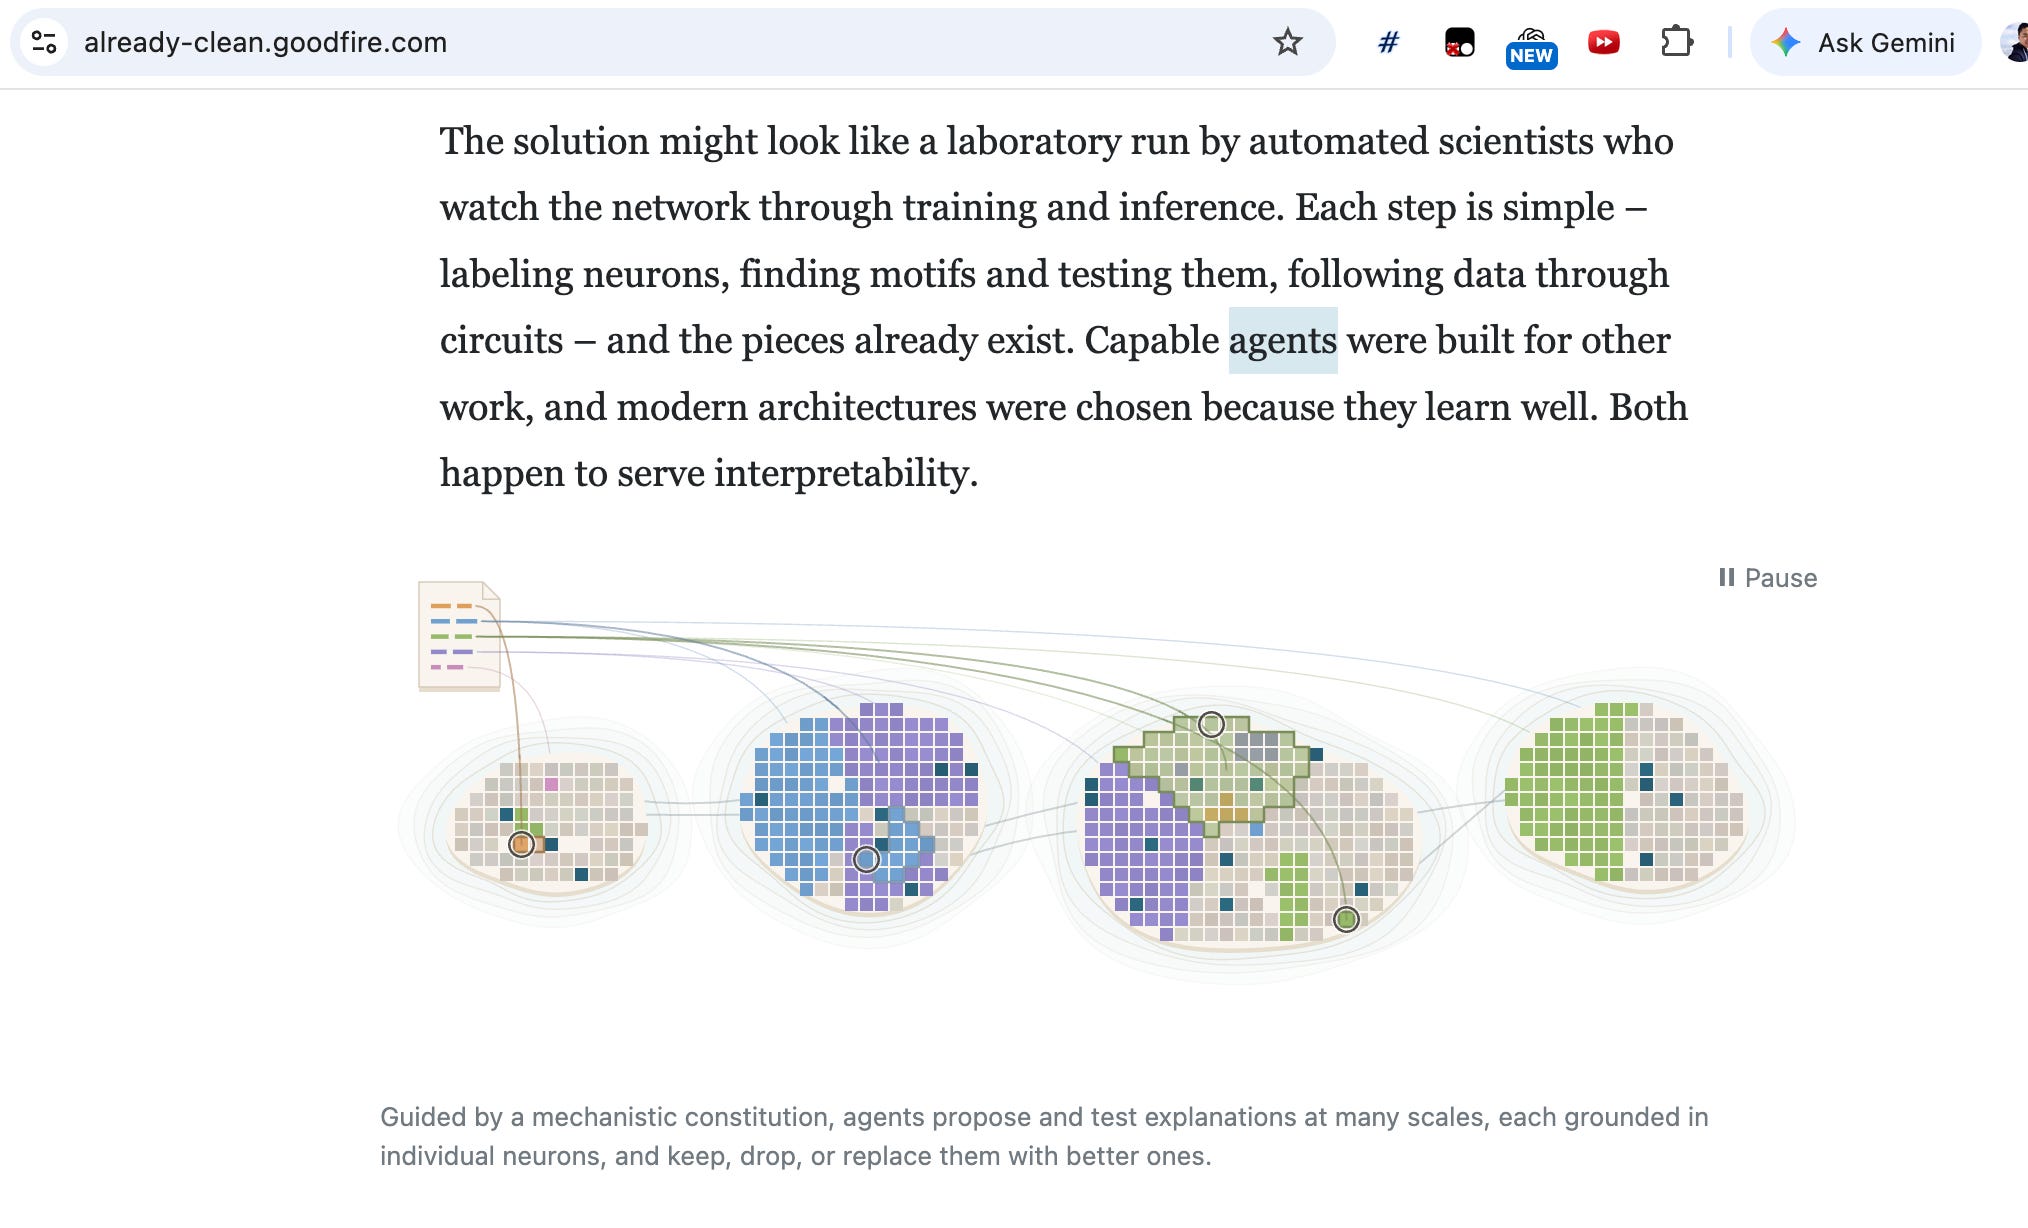
Voices[AINews] Agents disprove Polysemanticity; greatly improve Interpretability & Alignment Latent Space
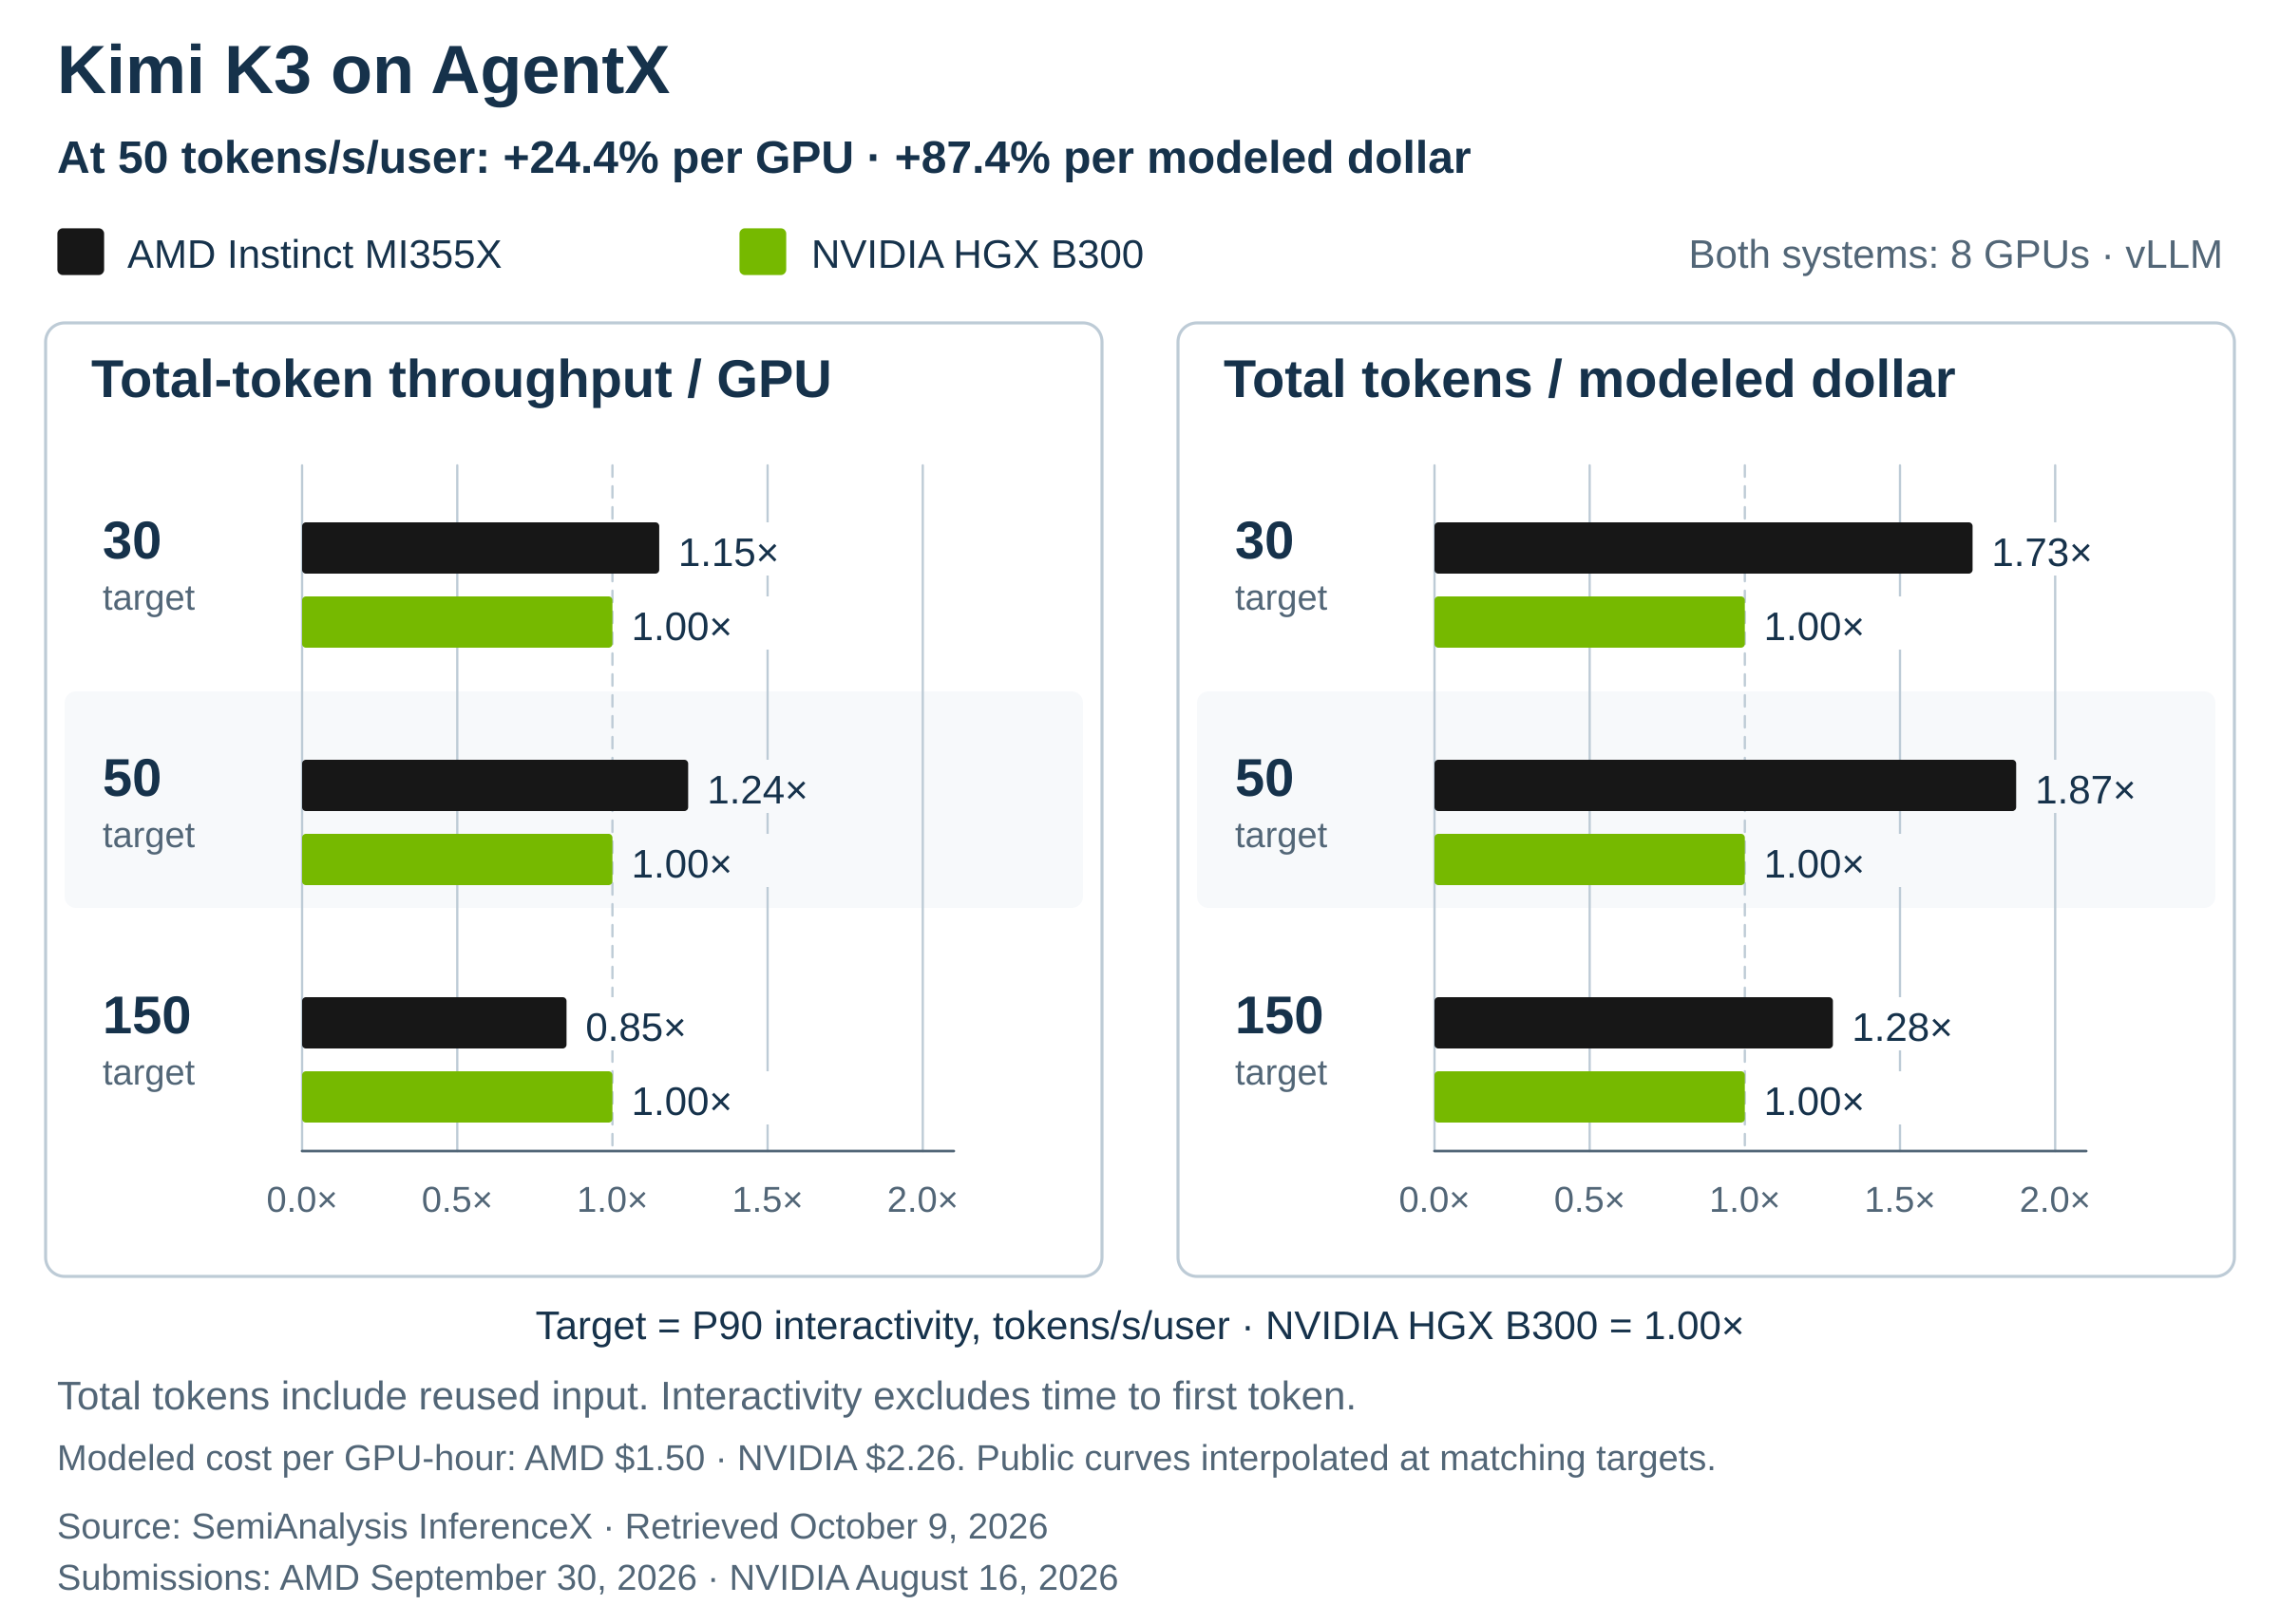
ToolsScaling Kimi K3 on AMD Instinct MI355X: Matching NVIDIA HGX B300 Throughput per GPU on AgentX vLLM Blog